Deep Learning · MT2 · formulas
Flatten and dense parameter count
Flattening rearranges all activation values into a list. It learns no new numbers. A dense layer then connects every value in that list to every receiving neuron; each receiving neuron also has one bias.
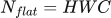 LaTeX:
N_{flat}=HWC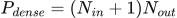 LaTeX:
P_{dense}=(N_{in}+1)N_{out}Counting parameters in a dense network
Definition. A dense layer connects every input component to every receiving neuron. Its trainable parameters are these connection weights and the receiving neurons' independently trainable biases.
Deriving the parameter count
For m inputs and n receiving neurons, each receiver needs m weights. There are therefore mn weights. With one bias per receiver, there are n additional parameters:
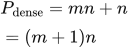 LaTeX:
P_{\mathrm{dense}}=mn+n=(m+1)nActivation values are computed from data and parameters; they are not additional trainable parameters. The input layer supplies data and does not acquire an extra bias merely because it appears in a diagram.
Complete numerical
Question. A network has 10 input features, three hidden layers with 5 neurons each, and 4 outputs. Every receiving neuron has a bias. Count its trainable parameters.
Given
Layer sizes: 10 inputs → 5 hidden → 5 hidden → 5 hidden → 4 outputs.
Every hidden/output neuron has one bias.
To find
Count weights and biases at each receiving layer, then the total.
Formula — which one and why
Dense-layer parameters. Every output neuron receives every input, so multiply inputs by outputs for weights. Add one bias per receiving neuron. Sum separate layers.
n_in = incoming features; n_out = receiving neurons. The input layer itself has no learned receiving weights or biases.
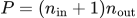 LaTeX:
P=(n_{\mathrm{in}}+1)n_{\mathrm{out}}Yaad rakhne ka cue: Har output ke liye saare inputs plus ek bias.
Solution — step by step
Step 1: identify the consecutive layer widths.
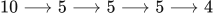 LaTeX:
10\longrightarrow5\longrightarrow5\longrightarrow5\longrightarrow4There are four trainable dense transformations. A connection between two hidden layers is counted once, as part of the receiving layer's parameters.
Step 2: count weights and biases for each transformation.
| Transformation | Weights | Biases | Layer total |
|---|---|---|---|
| Input → hidden 1 | 10 × 5 = 50 | 5 | 55 |
| Hidden 1 → hidden 2 | 5 × 5 = 25 | 5 | 30 |
| Hidden 2 → hidden 3 | 5 × 5 = 25 | 5 | 30 |
| Hidden 3 → output | 5 × 4 = 20 | 4 | 24 |
Step 3: add the layer totals.
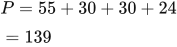 LaTeX:
P=55+30+30+24=139Equivalently, the network has 120 weights and 19 biases, so 120 + 19 = 139.
Final answer: 139 trainable parameters. If a question explicitly removes biases, count only the 120 weights. Optimizer states such as Adam's moments are extra training storage, not extra parameters in this predictive network.
One complete CNN pipeline
Question. Input 128 × 128 × 3 → convolution 3 × 3, 16 filters, stride 1, no padding → pooling 2 × 2, stride 2 → convolution 3 × 3, 32 filters, stride 1, no padding → pooling 2 × 2, stride 2 → dense 240 → dense 120 → dense 5 with softmax. Find every output shape and trainable parameter count. Assume one bias per receiving filter or dense neuron.
Given
Input = 128 × 128 × 3.
Conv: 3 × 3,16 filters,stride 1,valid → pool 2,stride 2.
Conv: 3 × 3,32 filters,stride 1,valid → pool 2,stride 2.
Flatten → dense 240 → dense 120 → dense 5.
One bias per learned filter/dense neuron.
To find
Find every output shape and layer parameter count, then the network total.
Formula — which one and why
Complete CNN calculation. Carry each output shape into the next layer. Convolution changes spatial size and channel count; pooling changes spatial size; flattening converts all activations into dense-layer inputs.
H,W,C = feature-map height, width and channels; K = kernel size; S = stride; P_pad = padding. One bias is assumed for each learned filter or dense neuron unless specified otherwise.
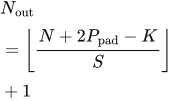 LaTeX:
N_{\mathrm{out}}=\left\lfloor\frac{N+2P_{\mathrm{pad}}-K}{S}\right\rfloor+1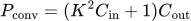 LaTeX:
P_{\mathrm{conv}}=(K^2C_{\mathrm{in}}+1)C_{\mathrm{out}}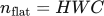 LaTeX:
n_{\mathrm{flat}}=HWC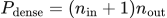 LaTeX:
P_{\mathrm{dense}}=(n_{\mathrm{in}}+1)n_{\mathrm{out}}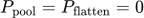 LaTeX:
P_{\mathrm{pool}}=P_{\mathrm{flatten}}=0Yaad rakhne ka cue: Ek layer ka output, next layer ka input; shape aur parameters alag count.
Solution — step by step
Step 1. Conv 1 size. (128 − 3)/1 + 1 = 126; output 126 × 126 × 16. Parameters = (3 × 3 × 3 + 1) × 16 = 448.
Step 2. Pool 1 size. 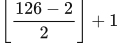 LaTeX:
\left\lfloor\frac{126 - 2}{2}\right\rfloor+1 = 63; output 63 × 63 × 16. Parameters = 0.
Step 3. Conv 2 size. (63 − 3)/1 + 1 = 61; output 61 × 61 × 32. Input channels are now 16, not the original 3. Parameters = (3 × 3 × 16 + 1) × 32 = 4,640.
Step 4. Pool 2 size. 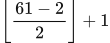 LaTeX:
\left\lfloor\frac{61 - 2}{2}\right\rfloor+1 =  LaTeX:
\left\lfloor 29.5\right\rfloor + 1 = 30; output 30 × 30 × 32. Parameters = 0.
Step 5. Flatten. 30 × 30 × 32 = 28,800 values. Parameters = 0.
Step 6. Dense 240. 28,800 weights per neuron plus one bias, multiplied by 240: (28,800 + 1) × 240 = 6,912,240.
Step 7. Dense 120. (240 + 1) × 120 = 28,920.
Step 8. Classifier. (120 + 1) × 5 = 605. Softmax itself adds no extra parameters; these 605 belong to the dense class-score layer.
Step 9. Total. 448 + 4,640 + 6,912,240 + 28,920 + 605 = 6,946,853. Most parameters come from the first dense layer.
Drill 35 Complete small CNN
Question
Question. Input 10 × 10 × 1 → Conv 3 × 3,4 filters, stride 1, valid → Pool 2 stride 2 → Flatten → Dense 3. Find all shapes and parameters.
Answer — step by step
Given
Input = 10 × 10 × 1.
Conv: 3 × 3, 4 filters, stride 1, valid padding.
Pool: 2 × 2, stride 2; then flatten and dense layer with 3 outputs.
Include one bias per filter/dense neuron.
To find
Find all output shapes, layer parameter counts and their sum.
Formula — which one and why
Complete CNN calculation. Carry each output shape into the next layer. Convolution changes spatial size and channel count; pooling changes spatial size; flattening converts all activations into dense-layer inputs.
H,W,C = feature-map height, width and channels; K = kernel size; S = stride; P_pad = padding. One bias is assumed for each learned filter or dense neuron unless specified otherwise.
LaTeX: N_{\mathrm{out}}=\left\lfloor\frac{N+2P_{\mathrm{pad}}-K}{S}\right\rfloor+1LaTeX: P_{\mathrm{conv}}=(K^2C_{\mathrm{in}}+1)C_{\mathrm{out}}LaTeX: n_{\mathrm{flat}}=HWCLaTeX: P_{\mathrm{dense}}=(n_{\mathrm{in}}+1)n_{\mathrm{out}}LaTeX: P_{\mathrm{pool}}=P_{\mathrm{flatten}}=0Yaad rakhne ka cue: Ek layer ka output, next layer ka input; shape aur parameters alag count.
Solution — step by step
Formulas and assumptions
“Valid” means zero padding. The convolution and dense layers each have one bias per receiving filter or neuron. Pooling and flattening have no learned parameters.
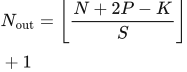 LaTeX:
N_{\mathrm{out}}=\left\lfloor\frac{N+2P-K}{S}\right\rfloor+1LaTeX: P_{\mathrm{conv}}=(K^2C_{\mathrm{in}}+1)C_{\mathrm{out}}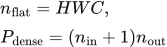 LaTeX:
n_{\mathrm{flat}}=HWC,\qquad P_{\mathrm{dense}}=(n_{\mathrm{in}}+1)n_{\mathrm{out}}Step 1: convolution shape
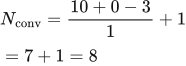 LaTeX:
N_{\mathrm{conv}}=\frac{10+0-3}{1}+1=7+1=8Four filters produce four channels: 8 × 8 × 4.
Step 2: convolution parameters
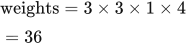 LaTeX:
\text{weights}=3\times3\times1\times4=36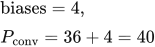 LaTeX:
\text{biases}=4,\qquad P_{\mathrm{conv}}=36+4=40Step 3: pooling shape
Pooling now receives size 8, not the original size 10.
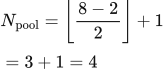 LaTeX:
N_{\mathrm{pool}}=\left\lfloor\frac{8-2}{2}\right\rfloor+1=3+1=4Channels remain 4: 4 × 4 × 4. Pooling parameters = 0.
Step 4: flatten
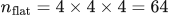 LaTeX:
n_{\mathrm{flat}}=4\times4\times4=64Flatten creates a vector of 64 numbers. It rearranges values, so its parameter count is 0.
Step 5: dense layer with 3 outputs
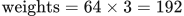 LaTeX:
\text{weights}=64\times3=192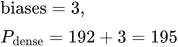 LaTeX:
\text{biases}=3,\qquad P_{\mathrm{dense}}=192+3=195Step 6: add learned parameters
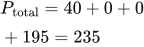 LaTeX:
P_{\mathrm{total}}=40+0+0+195=235Final answer: shapes 8 × 8 × 4 → 4 × 4 × 4 → 64 → 3; total 235 parameters.
Drill 43 Mixed CNN dimensions softmax and loss
Question
Question. Input 8 × 8 × 3 → Conv 3, stride 1, padding 1, 2 filters → Pool 2, stride 2 → Flatten → Dense 3. Logits [0,1,−1], true class is the second class (one-hot target [0,1,0]). Find shapes, parameters, probabilities and CCE.
Answer — step by step
Given
Input = 8 × 8 × 3.
Conv: kernel 3, stride 1, padding 1, 2 filters.
Pool: kernel 2, stride 2; flatten; dense layer with 3 outputs.
Logits = [0,1,−1]; true class is the second class (one-hot target [0,1,0]).
To find
Find shapes, parameter counts, probabilities and CCE.
Formula — which one and why
Complete CNN calculation. Carry each output shape into the next layer. Convolution changes spatial size and channel count; pooling changes spatial size; flattening converts all activations into dense-layer inputs.
H,W,C = feature-map height, width and channels; K = kernel size; S = stride; P_pad = padding. One bias is assumed for each learned filter or dense neuron unless specified otherwise.
LaTeX: N_{\mathrm{out}}=\left\lfloor\frac{N+2P_{\mathrm{pad}}-K}{S}\right\rfloor+1LaTeX: P_{\mathrm{conv}}=(K^2C_{\mathrm{in}}+1)C_{\mathrm{out}}LaTeX: n_{\mathrm{flat}}=HWCLaTeX: P_{\mathrm{dense}}=(n_{\mathrm{in}}+1)n_{\mathrm{out}}LaTeX: P_{\mathrm{pool}}=P_{\mathrm{flatten}}=0Yaad rakhne ka cue: Ek layer ka output, next layer ka input; shape aur parameters alag count.
Stable softmax. Exponentiate each logit and divide by the sum. Subtracting the largest logit first keeps the exponentials numerically manageable and leaves the probabilities unchanged.
zⱼ = class j score; M = largest score; pⱼ = class j probability. All probabilities sum to 1.
 LaTeX:
M=\max_j z_j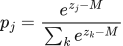 LaTeX:
p_j=\frac{e^{z_j-M}}{\sum_k e^{z_k-M}}Yaad rakhne ka cue: Largest score ghatao, exp nikalo, total se sabko divide karo.
Categorical cross-entropy. For mutually exclusive classes with a one-hot target, all zero-target terms disappear. The loss is the negative log of the probability assigned to the true class.
yⱼ = target entry; pⱼ = predicted probability; c = index of the true class. Use natural logarithms unless another base is specified.
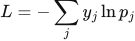 LaTeX:
L=-\sum_j y_j\ln p_j LaTeX:
L=-\ln p_cYaad rakhne ka cue: One-hot mein sirf correct class ki probability ka minus ln.
Solution — step by step
Formulas used
Separate shape from learned parameter count. H, W and C mean height, width and channels. K, P and S mean filter size, padding per side and stride.
LaTeX: N_{\mathrm{out}}=\left\lfloor\frac{N+2P-K}{S}\right\rfloor+1LaTeX: P_{\mathrm{conv}}=(K^2C_{\mathrm{in}}+1)C_{\mathrm{out}}LaTeX: n_{\mathrm{flat}}=HWC,\qquad P_{\mathrm{dense}}=(n_{\mathrm{in}}+1)n_{\mathrm{out}}The +1 counts one bias per receiving filter or neuron. Pooling and flattening add no learned parameters. Softmax converts scores to probabilities; CCE uses the probability of the correct class.
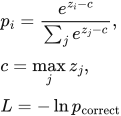 LaTeX:
p_i=\frac{e^{z_i-c}}{\sum_j e^{z_j-c}},\quad c=\max_jz_j,\quad L=-\ln p_{\mathrm{correct}}Conv size = (8+2−3)+1 = 8; output 8 × 8 × 2; parameters = (3 × 3 × 3+1) × 2 = 56. Pool 4 × 4 × 2; parameters 0. Flatten 32. Dense 3 parameters = (32+1) × 3 = 99. Total = 155.
Step 1 stabilize: subtract the largest logit 1 from every value: [-1, 0, -2]. This does not change softmax.
Step 2 exponentiate: exp values = [0.367879441, 1, 0.135335283].
Step 3 denominator: sum = 1.503214724.
Step 4 divide each value by this same sum: probabilities = [0.244728471, 0.665240956, 0.090030573]. Check: all are positive and their sum is 1 (apart from rounding); the largest logit gets the largest probability.
Correct class probability = 0.665240956; CCE = −ln(0.665240956) = 0.407605964.