Deep Learning · MT2 · section
MT1A Q3
Prerequisite repair and teacher backprop examples
Question
Question (3 marks). For z = [−1,0,1], calculate sigmoid, softmax and Leaky ReLU with α = 0.01 (an explicit assumption because the paper does not give the slope).
Answer — step by step
Given
Scores z = [−1,0,1].
Calculate sigmoid, softmax and Leaky ReLU.
The paper omits the Leaky slope: α = 0.01 is the stated practice assumption.
To find
Calculate every component under each of the three activations.
Formula — which one and why
Sigmoid and its slope. Use sigmoid when the neuron is specified to squash its preactivation into (0,1). Once its output is known, its derivative needs only output × (1−output).
z = preactivation; p = sigmoid output; e is the exponential base, not a prediction error in this formula.
 LaTeX:
p=\frac{1}{1+e^{-z}}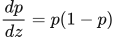 LaTeX:
\frac{dp}{dz}=p(1-p)Yaad rakhne ka cue: Sigmoid output p; uska slope p × (1−p).
Stable softmax. Exponentiate each logit and divide by the sum. Subtracting the largest logit first keeps the exponentials numerically manageable and leaves the probabilities unchanged.
zⱼ = class j score; M = largest score; pⱼ = class j probability. All probabilities sum to 1.
 LaTeX:
M=\max_j z_j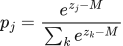 LaTeX:
p_j=\frac{e^{z_j-M}}{\sum_k e^{z_k-M}}Yaad rakhne ka cue: Largest score ghatao, exp nikalo, total se sabko divide karo.
ReLU and Leaky ReLU. ReLU returns zero for negative input and retains positive input. Leaky ReLU instead multiplies a negative input by its supplied slope.
z = preactivation; α (alpha) = supplied negative-side slope for Leaky ReLU. The derivative at zero needs an explicit convention.
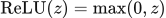 LaTeX:
\operatorname{ReLU}(z)=\max(0,z)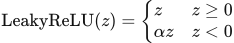 LaTeX:
\operatorname{LeakyReLU}(z)=\begin{cases}z&z\ge0\\\alpha z&z<0\end{cases}Yaad rakhne ka cue: Positive ko rehne do; negative ko zero. Leaky mein chhota negative rehne do.
Solution — step by step
Sigmoid is applied separately: σ(−1) =  LaTeX:
\frac{1}{1+e^{1}} = 0.268941421; σ(0) = 1/2 = 0.5; σ(1) =  LaTeX:
\frac{1}{1+e^{-1}} = 0.731058579.
Step 1 stabilize: subtract the largest logit 1 from every value: [-2, -1, 0]. This does not change softmax.
Step 2 exponentiate: exp values = [0.135335283, 0.367879441, 1].
Step 3 denominator: sum = 1.503214724.
Step 4 divide each value by this same sum: probabilities = [0.090030573, 0.244728471, 0.665240956]. Check: all are positive and their sum is 1 (apart from rounding); the largest logit gets the largest probability.
Leaky ReLU multiplies only negative values by α: [0.01 × (−1),0,1] = [−0.01,0,1]. Softmax normalizes the entire vector; independent sigmoid values need not sum to 1.