Deep Learning · MT2 · section
Teacher vectorized ReLU example
Prerequisite repair and teacher backprop examples
Question. Input x = [2, 3]. Each row below lists the incoming weights of one receiving neuron. W₁ = 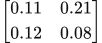 LaTeX:
\begin{bmatrix}0.11 & 0.21\\0.12 & 0.08\end{bmatrix}; b₁ = [0, 0]; W₂ =  LaTeX:
\begin{bmatrix}0.14 & 0.15\end{bmatrix}; b₂ = [0]. Hidden and output activations are ReLU. Target y = [1]. Learning rate η = 0.05. Use half squared loss and perform forward and backward passes.
Given
Input x = [2, 3].
W₁ = LaTeX: \begin{bmatrix}0.11 & 0.21\\0.12 & 0.08\end{bmatrix}.
b₁ = [0, 0].
W₂ = LaTeX: \begin{bmatrix}0.14 & 0.15\end{bmatrix}.
b₂ = [0].
Hidden and output activations are ReLU.
Target y = [1].
Learning rate η = 0.05.
Use half squared loss and perform forward and backward passes.
To find
Find all preactivations, hidden activations and final outputs. Calculate the half summed squared loss and its output derivatives. Find the requested deltas and parameter gradients, then update the specified parameters.
Formula — which one and why
Forward propagation. Evaluate one layer completely before supplying its activated outputs to the next layer. Each layer has its own weights and biases.
x = input vector; h = hidden outputs; W₁,b₁ = hidden parameters; W₂,b₂ = output parameters; f₁,f₂ = the stated activations.
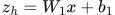 LaTeX:
z_h=W_1x+b_1 LaTeX:
h=f_1(z_h)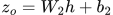 LaTeX:
z_o=W_2h+b_2 LaTeX:
o=f_2(z_o)Yaad rakhne ka cue: Pehli layer ka activated output hi agli layer ka input hai.
Half summed squared loss. This loss convention takes one-half of the sum of squared prediction errors. Use it when the question specifies it, or explicitly state it as an assumption when the paper omits the loss. Differentiating cancels the factor one-half against the square derivative.
oⱼ = output j; yⱼ = target j; L = half summed squared loss under the stated or explicitly assumed convention.
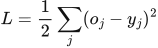 LaTeX:
L=\frac12\sum_j(o_j-y_j)^2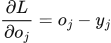 LaTeX:
\frac{\partial L}{\partial o_j}=o_j-y_jYaad rakhne ka cue: Half aur square ka 2 cancel: output derivative = prediction − target.
Backpropagation. The loss tells us how each output must change. Multiply by that neuron’s activation slope to obtain its delta. A weight gradient is receiving delta × sending value. Hidden deltas must include every outgoing path.
δ (delta) = derivative of loss with respect to a neuron’s preactivation; f′ = activation derivative; aᵢ = sending activation; Wⱼᵢ = connection weight. Use the exact loss scaling in the question.
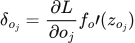 LaTeX:
\delta_{o_j}=\frac{\partial L}{\partial o_j}f_o\prime(z_{o_j})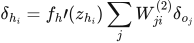 LaTeX:
\delta_{h_i}=f_h\prime(z_{h_i})\sum_jW_{ji}^{(2)}\delta_{o_j}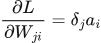 LaTeX:
\frac{\partial L}{\partial W_{ji}}=\delta_ja_i LaTeX:
\frac{\partial L}{\partial b_j}=\delta_j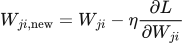 LaTeX:
W_{ji,\mathrm{new}}=W_{ji}-\eta\frac{\partial L}{\partial W_{ji}}Yaad rakhne ka cue: Receiving delta × sending value = us connection ka gradient.
Solution — step by step
Step 1 map the arrows. Each row of W₁ receives all inputs; each row of W₂ receives all hidden outputs. Bias is added once per receiving neuron. All gradients below use the OLD weights from this same forward pass.
Hidden neuron 1:
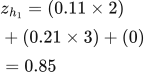 LaTeX:
z_{h_1} = (0.11 \times 2) + (0.21 \times 3) + (0) = 0.85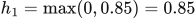 LaTeX:
h_{1} = \max(0,0.85) = 0.85Hidden neuron 2:
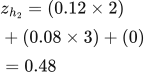 LaTeX:
z_{h_2} = (0.12 \times 2) + (0.08 \times 3) + (0) = 0.48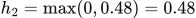 LaTeX:
h_{2} = \max(0,0.48) = 0.48Output neuron 1:
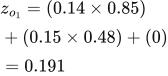 LaTeX:
z_{o_1} = (0.14 \times 0.85) + (0.15 \times 0.48) + (0) = 0.191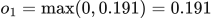 LaTeX:
o_{1} = \max(0,0.191) = 0.191Step 2 loss convention. This worked solution uses half summed squared loss, L = ½Σ(o − y)². Follow the loss specified in the question; where none is supplied, this is an explicit assumption.
Prediction minus target = [-0.809]. Squared errors = [0.654481]. Half-sum squared loss = 0.3272405; mean squared error = 0.654481. These are different unless the number of output components makes the scale coincide.
Output delta 1:
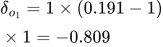 LaTeX:
\delta_{o_1} = 1 \times (0.191-1) \times 1 = -0.809The ReLU derivative is 1 here because this preactivation is positive.
Step 3 output weights. Gradient = receiving delta × sending activation. An output bias gradient equals its delta.
h1 → o1:
Subtract η × gradient = −0.0343825. This weight increases.
The sending value and receiving delta have different roles. All deltas still use the original forward-pass weights.
The receiving neuron supplies the delta; the sending neuron supplies its activation.
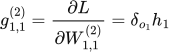 LaTeX:
g_{1,1}^{(2)}=\frac{\partial L}{\partial W^{(2)}_{1,1}}=\delta_{o_1}h_1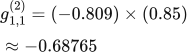 LaTeX:
g_{1,1}^{(2)}=(-0.809)\times(0.85)\approx -0.68765Apply the learning rate to this gradient and subtract the result from the old weight.
 LaTeX:
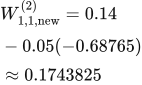
W^{(2)}_{1,1,\mathrm{new}}=0.14-0.05(-0.68765)\approx 0.1743825h2 → o1:
Subtract η × gradient = −0.019416. This weight increases.
The sending value and receiving delta have different roles. All deltas still use the original forward-pass weights.
The receiving neuron supplies the delta; the sending neuron supplies its activation.
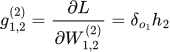 LaTeX:
g_{1,2}^{(2)}=\frac{\partial L}{\partial W^{(2)}_{1,2}}=\delta_{o_1}h_2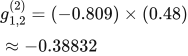 LaTeX:
g_{1,2}^{(2)}=(-0.809)\times(0.48)\approx -0.38832Apply the learning rate to this gradient and subtract the result from the old weight.
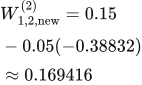 LaTeX:
W^{(2)}_{1,2,\mathrm{new}}=0.15-0.05(-0.38832)\approx 0.169416Step 4 hidden deltas. A hidden unit can influence EVERY connected output, so add those paths BEFORE multiplying by the hidden activation derivative.
Hidden 1 downstream contribution:
Calculate each outgoing path using the old outgoing weight and that output's delta.
Multiply within each path. Add the resulting contributions at the shared hidden neuron.
Contribution from output 1.
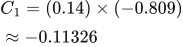 LaTeX:
C_1=(0.14)\times(-0.809)\approx -0.11326Accumulate the contributions, then apply the hidden activation derivative below.
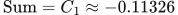 LaTeX:
\text{Sum}=C_1\approx -0.11326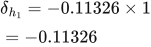 LaTeX:
\delta_{h_1} = -0.11326 \times 1 = -0.11326Hidden 2 downstream contribution:
Calculate each outgoing path using the old outgoing weight and that output's delta.
Multiply within each path. Add the resulting contributions at the shared hidden neuron.
Contribution from output 1.
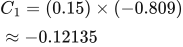 LaTeX:
C_1=(0.15)\times(-0.809)\approx -0.12135Accumulate the contributions, then apply the hidden activation derivative below.
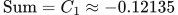 LaTeX:
\text{Sum}=C_1\approx -0.12135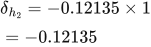 LaTeX:
\delta_{h_2} = -0.12135 \times 1 = -0.12135Step 5 input weights. Multiply the hidden delta by the corresponding raw input, not by the hidden output.
x1 → h1:
Subtract η × gradient = −0.011326. This weight increases.
The sending value and receiving delta have different roles. All deltas still use the original forward-pass weights.
The receiving neuron supplies the delta; the sending neuron supplies the input value.
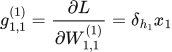 LaTeX:
g_{1,1}^{(1)}=\frac{\partial L}{\partial W^{(1)}_{1,1}}=\delta_{h_1}x_1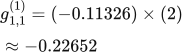 LaTeX:
g_{1,1}^{(1)}=(-0.11326)\times(2)\approx -0.22652Apply the learning rate to this gradient and subtract the result from the old weight.
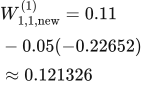 LaTeX:
W^{(1)}_{1,1,\mathrm{new}}=0.11-0.05(-0.22652)\approx 0.121326x2 → h1:
Subtract η × gradient = −0.016989. This weight increases.
The sending value and receiving delta have different roles. All deltas still use the original forward-pass weights.
The receiving neuron supplies the delta; the sending neuron supplies the input value.
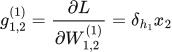 LaTeX:
g_{1,2}^{(1)}=\frac{\partial L}{\partial W^{(1)}_{1,2}}=\delta_{h_1}x_2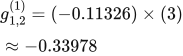 LaTeX:
g_{1,2}^{(1)}=(-0.11326)\times(3)\approx -0.33978Apply the learning rate to this gradient and subtract the result from the old weight.
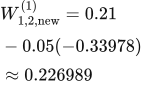 LaTeX:
W^{(1)}_{1,2,\mathrm{new}}=0.21-0.05(-0.33978)\approx 0.226989x1 → h2:
Subtract η × gradient = −0.012135. This weight increases.
The sending value and receiving delta have different roles. All deltas still use the original forward-pass weights.
The receiving neuron supplies the delta; the sending neuron supplies the input value.
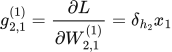 LaTeX:
g_{2,1}^{(1)}=\frac{\partial L}{\partial W^{(1)}_{2,1}}=\delta_{h_2}x_1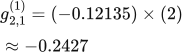 LaTeX:
g_{2,1}^{(1)}=(-0.12135)\times(2)\approx -0.2427Apply the learning rate to this gradient and subtract the result from the old weight.
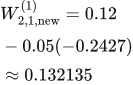 LaTeX:
W^{(1)}_{2,1,\mathrm{new}}=0.12-0.05(-0.2427)\approx 0.132135x2 → h2:
Subtract η × gradient = −0.0182025. This weight increases.
The sending value and receiving delta have different roles. All deltas still use the original forward-pass weights.
The receiving neuron supplies the delta; the sending neuron supplies the input value.
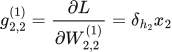 LaTeX:
g_{2,2}^{(1)}=\frac{\partial L}{\partial W^{(1)}_{2,2}}=\delta_{h_2}x_2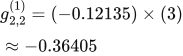 LaTeX:
g_{2,2}^{(1)}=(-0.12135)\times(3)\approx -0.36405Apply the learning rate to this gradient and subtract the result from the old weight.
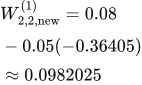 LaTeX:
W^{(1)}_{2,2,\mathrm{new}}=0.08-0.05(-0.36405)\approx 0.0982025Step 6 bias updates. A bias receives a constant input 1, so its gradient equals the corresponding delta. Use the same old forward pass and learning rate as the weight updates.
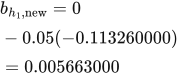 LaTeX:
b_{h_1,\mathrm{new}}=0-0.05(-0.113260000)=0.005663000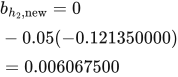 LaTeX:
b_{h_2,\mathrm{new}}=0-0.05(-0.121350000)=0.006067500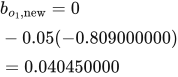 LaTeX:
b_{o_1,\mathrm{new}}=0-0.05(-0.809000000)=0.040450000These are independent per-neuron biases. If the question fixes biases, keep them fixed. If it specifies a single tied bias, add all deltas sharing that bias before updating it.
Correction to the handwritten working: the hidden deltas are negative (−0.11326 and −0.12135). A positive value at that step is a sign error. Keep output error as prediction minus target throughout.