Deep Learning · MT2 · section
F25 Q1d
F25 selected MT2 practice
Question
Question (5 marks). Describe sequence processing, context and variable-length sentences in RNNs. Explain their use in language translation, as illustrated by the historical reference to Google Translate.
Answer — step by step
A recurrent neural network processes a sequence in order and maintains a hidden state that summarizes earlier information. Its weights are shared across time steps.
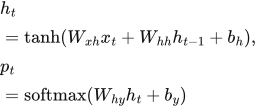 LaTeX:
h_t=\tanh(W_{xh}x_t+W_{hh}h_{t-1}+b_h),\quad p_t=\operatorname{softmax}(W_{hy}h_t+b_y)At each step, transform the current token representation, transform the previous hidden state, add the bias and apply the activation. An output layer may produce a prediction at each step or only at the end. This allows a sequence's length to vary while the parameter set stays fixed.
For next-word prediction, tokenize text, represent each word numerically, update the state for each prefix token, and apply an output softmax over the vocabulary. Train against the actual next token using cross-entropy. For sentiment classification, use the sequence representation to predict positive, neutral or negative. Word order matters: “not good” should not be interpreted like “good”.
A basic feedforward model has no built-in recurrent state, though a fixed window can be supplied explicitly. RNNs provide recurrent context but have sequential computation costs and difficulty learning long dependencies because of vanishing or exploding gradients. An encoder-decoder RNN can encode a source sentence and generate a target sentence of a different length; this is a historical RNN translation explanation, not a claim about any commercial service's current architecture.