Deep Learning · MT2 · section
F23 Q4a
F23 selected MT2 practice
Question
Question (10 marks). Determine feature-map dimensions and parameters at every layer of the pictured AlexNet-style CNN. The normalized architecture is Input 227 × 227 × 3. → Conv K = 11, filters = 96, stride = 4, padding = 0. → Pool K = 3, stride = 2, padding = 0. → Conv K = 5, filters = 256, stride = 1, padding = 2. → Pool K = 3, stride = 2, padding = 0. → Conv K = 3, filters = 384, stride = 1, padding = 1. → Conv K = 3, filters = 384, stride = 1, padding = 1. → Conv K = 3, filters = 256, stride = 1, padding = 1. → Pool K = 3, stride = 2, padding = 0. → Flatten. → Dense 4096 units. → Dense 4096 units. → Dense 1000 units.
Answer — step by step
Given
The normalized architecture is Input 227 × 227 × 3.
Conv K = 11, filters = 96, stride = 4, padding = 0.
Pool K = 3, stride = 2, padding = 0.
Conv K = 5, filters = 256, stride = 1, padding = 2.
Pool K = 3, stride = 2, padding = 0.
Conv K = 3, filters = 384, stride = 1, padding = 1.
Conv K = 3, filters = 384, stride = 1, padding = 1.
Conv K = 3, filters = 256, stride = 1, padding = 1.
Pool K = 3, stride = 2, padding = 0.
Dense 4096 units.
Dense 4096 units.
Dense 1000 units.
To find
Find every layer shape, its parameter count and the network total.
Formula — which one and why
Complete CNN calculation. Carry each output shape into the next layer. Convolution changes spatial size and channel count; pooling changes spatial size; flattening converts all activations into dense-layer inputs.
H,W,C = feature-map height, width and channels; K = kernel size; S = stride; P_pad = padding. One bias is assumed for each learned filter or dense neuron unless specified otherwise.
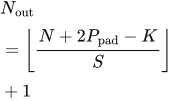 LaTeX:
N_{\mathrm{out}}=\left\lfloor\frac{N+2P_{\mathrm{pad}}-K}{S}\right\rfloor+1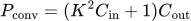 LaTeX:
P_{\mathrm{conv}}=(K^2C_{\mathrm{in}}+1)C_{\mathrm{out}}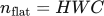 LaTeX:
n_{\mathrm{flat}}=HWC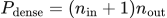 LaTeX:
P_{\mathrm{dense}}=(n_{\mathrm{in}}+1)n_{\mathrm{out}}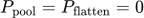 LaTeX:
P_{\mathrm{pool}}=P_{\mathrm{flatten}}=0Yaad rakhne ka cue: Ek layer ka output, next layer ka input; shape aur parameters alag count.
Solution — step by step
Use output size 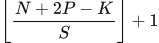 LaTeX:
\left\lfloor\frac{N+2P-K}{S}\right\rfloor+1, Conv weights K² × Cin × Cout and biases Cout, Dense weights Nin × Nout and biases Nout. Assume a bias per learned filter/unit, full input-channel connectivity and no trainable pooling parameters. ReLU and softmax activations themselves add no trainable parameters.
Layer-by-layer calculation
Carry the complete output shape of one layer into the next. Spatial size determines the number of activations; it does not multiply the number of shared convolution parameters.
Layer 1 — convolution
Spatial positions share the filter weights. Output depth equals the number of filters.
Input: 227 × 227 × 3. Use 96 filters of spatial size 11 × 11, stride 4, and padding 0 on each side.
1. Calculate height and width.
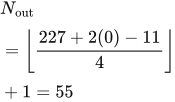 LaTeX:
N_{\mathrm{out}}=\left\lfloor\frac{227+2(0)-11}{4}\right\rfloor+1=552. Determine output channels. Each filter produces one feature map. Therefore the output is 55 × 55 × 96.
3. Count trainable values. Each filter receives all 3 input channels. Its weights are reused at every spatial position.
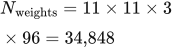 LaTeX:
N_{\mathrm{weights}}=11\times11\times3\times96=34{,}848 LaTeX:
N_{\mathrm{biases}}=96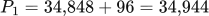 LaTeX:
P_1=34{,}848+96=34{,}944Layer 2 — pooling
Spatial dimensions change; the channel count stays the same. Pooling learns no weights.
Input: 55 × 55 × 96. Use a 3 × 3 window, stride 2, and zero padding.
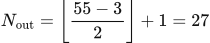 LaTeX:
N_{\mathrm{out}}=\left\lfloor\frac{55-3}{2}\right\rfloor+1=27Pooling acts independently on each channel. The output is 27 × 27 × 96.
Trainable parameters: 0. Max/average pooling has no learned filter weights or biases.
Layer 3 — convolution
Spatial positions share the filter weights. Output depth equals the number of filters.
Input: 27 × 27 × 96. Use 256 filters of spatial size 5 × 5, stride 1, and padding 2 on each side.
1. Calculate height and width.
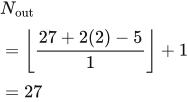 LaTeX:
N_{\mathrm{out}}=\left\lfloor\frac{27+2(2)-5}{1}\right\rfloor+1=272. Determine output channels. Each filter produces one feature map. Therefore the output is 27 × 27 × 256.
3. Count trainable values. Each filter receives all 96 input channels. Its weights are reused at every spatial position.
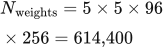 LaTeX:
N_{\mathrm{weights}}=5\times5\times96\times256=614{,}400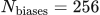 LaTeX:
N_{\mathrm{biases}}=256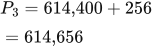 LaTeX:
P_3=614{,}400+256=614{,}656Layer 4 — pooling
Spatial dimensions change; the channel count stays the same. Pooling learns no weights.
Input: 27 × 27 × 256. Use a 3 × 3 window, stride 2, and zero padding.
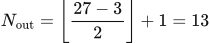 LaTeX:
N_{\mathrm{out}}=\left\lfloor\frac{27-3}{2}\right\rfloor+1=13Pooling acts independently on each channel. The output is 13 × 13 × 256.
Trainable parameters: 0. Max/average pooling has no learned filter weights or biases.
Layer 5 — convolution
Spatial positions share the filter weights. Output depth equals the number of filters.
Input: 13 × 13 × 256. Use 384 filters of spatial size 3 × 3, stride 1, and padding 1 on each side.
1. Calculate height and width.
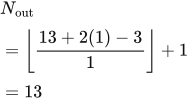 LaTeX:
N_{\mathrm{out}}=\left\lfloor\frac{13+2(1)-3}{1}\right\rfloor+1=132. Determine output channels. Each filter produces one feature map. Therefore the output is 13 × 13 × 384.
3. Count trainable values. Each filter receives all 256 input channels. Its weights are reused at every spatial position.
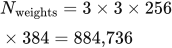 LaTeX:
N_{\mathrm{weights}}=3\times3\times256\times384=884{,}736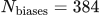 LaTeX:
N_{\mathrm{biases}}=384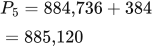 LaTeX:
P_5=884{,}736+384=885{,}120Layer 6 — convolution
Spatial positions share the filter weights. Output depth equals the number of filters.
Input: 13 × 13 × 384. Use 384 filters of spatial size 3 × 3, stride 1, and padding 1 on each side.
1. Calculate height and width.
LaTeX: N_{\mathrm{out}}=\left\lfloor\frac{13+2(1)-3}{1}\right\rfloor+1=132. Determine output channels. Each filter produces one feature map. Therefore the output is 13 × 13 × 384.
3. Count trainable values. Each filter receives all 384 input channels. Its weights are reused at every spatial position.
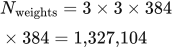 LaTeX:
N_{\mathrm{weights}}=3\times3\times384\times384=1{,}327{,}104LaTeX: N_{\mathrm{biases}}=384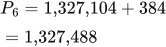 LaTeX:
P_6=1{,}327{,}104+384=1{,}327{,}488Layer 7 — convolution
Spatial positions share the filter weights. Output depth equals the number of filters.
Input: 13 × 13 × 384. Use 256 filters of spatial size 3 × 3, stride 1, and padding 1 on each side.
1. Calculate height and width.
LaTeX: N_{\mathrm{out}}=\left\lfloor\frac{13+2(1)-3}{1}\right\rfloor+1=132. Determine output channels. Each filter produces one feature map. Therefore the output is 13 × 13 × 256.
3. Count trainable values. Each filter receives all 384 input channels. Its weights are reused at every spatial position.
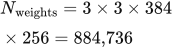 LaTeX:
N_{\mathrm{weights}}=3\times3\times384\times256=884{,}736LaTeX: N_{\mathrm{biases}}=256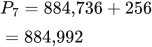 LaTeX:
P_7=884{,}736+256=884{,}992Layer 8 — pooling
Spatial dimensions change; the channel count stays the same. Pooling learns no weights.
Input: 13 × 13 × 256. Use a 3 × 3 window, stride 2, and zero padding.
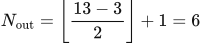 LaTeX:
N_{\mathrm{out}}=\left\lfloor\frac{13-3}{2}\right\rfloor+1=6Pooling acts independently on each channel. The output is 6 × 6 × 256.
Trainable parameters: 0. Max/average pooling has no learned filter weights or biases.
Layer 9 — flatten
The same activation values are rearranged into one vector. No parameter is learned.
Input: 6 × 6 × 256. Rearrange all activation values into one vector.
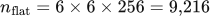 LaTeX:
n_{\mathrm{flat}}=6\times6\times256=9{,}216Output: a vector with 9,216 entries. Flattening changes the arrangement, so it adds 0 trainable parameters.
Layer 10 — fully connected layer
Every output neuron receives every input feature, with one bias per output neuron.
Input: 9,216 features. Output: 4,096 neurons. Every output neuron connects to every input feature and has one bias.
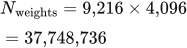 LaTeX:
N_{\mathrm{weights}}=9{,}216\times4{,}096=37{,}748{,}736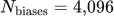 LaTeX:
N_{\mathrm{biases}}=4{,}096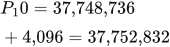 LaTeX:
P_10=37{,}748{,}736+4{,}096=37{,}752{,}832Layer 11 — fully connected layer
Every output neuron receives every input feature, with one bias per output neuron.
Input: 4,096 features. Output: 4,096 neurons. Every output neuron connects to every input feature and has one bias.
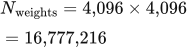 LaTeX:
N_{\mathrm{weights}}=4{,}096\times4{,}096=16{,}777{,}216LaTeX: N_{\mathrm{biases}}=4{,}096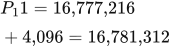 LaTeX:
P_11=16{,}777{,}216+4{,}096=16{,}781{,}312Layer 12 — fully connected layer
Every output neuron receives every input feature, with one bias per output neuron.
Input: 4,096 features. Output: 1,000 neurons. Every output neuron connects to every input feature and has one bias.
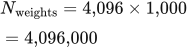 LaTeX:
N_{\mathrm{weights}}=4{,}096\times1{,}000=4{,}096{,}000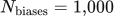 LaTeX:
N_{\mathrm{biases}}=1{,}000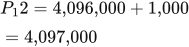 LaTeX:
P_12=4{,}096{,}000+1{,}000=4{,}097{,}000Summary of the complete network
| Layer | Spatial or flatten calculation | Output | Weights | Biases | Total |
|---|---|---|---|---|---|
| 1 conv | 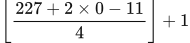 LaTeX: \left\lfloor\frac{227+2 \times 0-11}{4}\right\rfloor+1 | 55 x 55 x 96 | 34,848 | 96 | 34,944 |
| 2 pool | 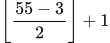 LaTeX: \left\lfloor\frac{55-3}{2}\right\rfloor+1 | 27 x 27 x 96 | 0 | 0 | 0 |
| 3 conv | 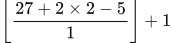 LaTeX: \left\lfloor\frac{27+2 \times 2-5}{1}\right\rfloor+1 | 27 x 27 x 256 | 614,400 | 256 | 614,656 |
| 4 pool | 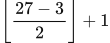 LaTeX: \left\lfloor\frac{27-3}{2}\right\rfloor+1 | 13 x 13 x 256 | 0 | 0 | 0 |
| 5 conv | 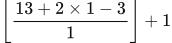 LaTeX: \left\lfloor\frac{13+2 \times 1-3}{1}\right\rfloor+1 | 13 x 13 x 384 | 884,736 | 384 | 885,120 |
| 6 conv | LaTeX: \left\lfloor\frac{13+2 \times 1-3}{1}\right\rfloor+1 | 13 x 13 x 384 | 1,327,104 | 384 | 1,327,488 |
| 7 conv | LaTeX: \left\lfloor\frac{13+2 \times 1-3}{1}\right\rfloor+1 | 13 x 13 x 256 | 884,736 | 256 | 884,992 |
| 8 pool | 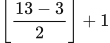 LaTeX: \left\lfloor\frac{13-3}{2}\right\rfloor+1 | 6 x 6 x 256 | 0 | 0 | 0 |
| 9 flat | 6 × 6 × 256 | 9216 | 0 | 0 | 0 |
| 10 dense | 9216 → 4096 | 4096 | 37,748,736 | 4,096 | 37,752,832 |
| 11 dense | 4096 → 4096 | 4096 | 16,777,216 | 4,096 | 16,781,312 |
| 12 dense | 4096 → 1000 | 1000 | 4,096,000 | 1,000 | 4,097,000 |
Parameter substitutions, in layer order:
Layer 1: (11 x 11 x 3 + 1) x 96 = 34,944.
Layer 3: (5 x 5 x 96 + 1) x 256 = 614,656.
Layer 5: (3 x 3 x 256 + 1) x 384 = 885,120.
Layer 6: (3 x 3 x 384 + 1) x 384 = 1,327,488.
Layer 7: (3 x 3 x 384 + 1) x 256 = 884,992.
Layer 10: (9216 + 1) x 4096 = 37,752,832.
Layer 11: (4096 + 1) x 4096 = 16,781,312.
Layer 12: (4096 + 1) x 1000 = 4,097,000.
Total: 34,944 + 614,656 + 885,120 + 1,327,488 + 884,992 + 37,752,832 + 16,781,312 + 4,097,000 = 62,378,344 trainable parameters. Pooling changes activation size; it does not itself add learned weights. Always floor noninteger spatial dimensions.
The count treats every listed convolution as connected to all input channels. Original grouped AlexNet implementations have different counts; do not insert grouping that is not shown in the question.