Deep Learning · MT2 · section
F23 Q6b
F23 selected MT2 practice
Question
Question (10 marks). Explain how ResNet addresses vanishing gradients. Compare a block output with and without a residual connection.
Answer — step by step
A residual block learns a residual mapping F(x) and adds the input through a shortcut: y = F(x)+x, followed by an activation when the block design specifies one. A plain block without the shortcut outputs F(x). If F(x) becomes zero, the residual block can still pass x forward.
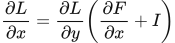 LaTeX:
\frac{\partial L}{\partial x}=\frac{\partial L}{\partial y}\left(\frac{\partial F}{\partial x}+I\right)The identity term gives a direct gradient path. This helps optimize very deep networks and reduces the burden of learning an identity mapping through many nonlinear layers. Features can be reused or refined instead of being completely reconstructed by every block. Residual connections address optimization degradation and can help gradient flow, although they do not guarantee that vanishing gradients can never occur anywhere in the network.
Elementwise addition requires compatible shapes. If channel counts or spatial sizes differ, use a suitable projection shortcut, often a 1 × 1 convolution with the required stride. A shortcut is an addition, not channel concatenation. Example: x = [2,−1] and F(x) = [0.5,0.2] give y = [2.5,−0.8]; a subsequent ReLU gives [2.5,0]. Without the shortcut the preactivation output would be [0.5,0.2].