Deep Learning · MT2 · section
F22 Q6b
F22 selected MT2 practice
Question
Question (10 marks). Design a clothes classifier for 250,000 six-dimensional samples,6 classes and 2 hidden layers. Give train/validation/test split, activations/loss, actions for 15% training 20% validation error, interpret improvement to 1%/1.5%, then address 15% test error.
Answer — step by step
One explicit design: 6 → 16 → 8 → 6, ReLU hidden layers,6-unit softmax output, categorical cross-entropy. The hidden widths are chosen assumptions, not supplied numerical requirements.
Architecture: 6 → 16 → 8 → 6. Each non-input neuron has one bias.
Layer 6 → 16
Step 1: count connections.
 LaTeX:
6(16)=96Step 2: count receiving-neuron biases.
There are 16 receiving neurons, so 16 biases.
Step 3: add weights and biases.
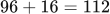 LaTeX:
96+16=112Layer 16 → 8
Step 1: count connections.
 LaTeX:
16(8)=128Step 2: count receiving-neuron biases.
There are 8 receiving neurons, so 8 biases.
Step 3: add weights and biases.
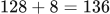 LaTeX:
128+8=136Layer 8 → 6
Step 1: count connections.
 LaTeX:
8(6)=48Step 2: count receiving-neuron biases.
There are 6 receiving neurons, so 6 biases.
Step 3: add weights and biases.
 LaTeX:
48+6=54Total = 302. Input values and activations are not trainable parameters.
Split: a stratified 70/15/15 split gives 175,000 training,37,500 validation,37,500 test samples. Fit preprocessing on training data only and keep related duplicates within a single split.
15%/20%: inspect learning curves and baseline difficulty. Substantial training error suggests capacity/optimization or data-quality issues; the 5 point gap also suggests a generalization issue. Improve training fit, tune regularization and collect useful representative data instead of blindly increasing capacity.
1%/1.5%: good comparable-set results with a small gap are encouraging; verify that validation has not leaked into training.
15% test: inspect distribution shift, preprocessing differences, label quality, leakage or repeated validation overfitting. Compare per-class errors and collection conditions. Address the actual cause and collect representative data if necessary. If test results guide retuning, use a fresh untouched final test set.