Deep Learning · MT2 · section
Drill 17 GD variation 2
MT2 numerical practice from direct to mixed
Question
Question. J(θ) = ½(θ−1)², θ₀ = -0.5, η = 0.1. Perform two GD updates.
Answer — step by step
Given
Objective: J(θ) = ½(θ−1)².
Initial θ₀ = −0.5; η = 0.1; two iterations.
To find
Find every stored state needed by the method and the parameter after each of two updates.
Formula — which one and why
Gradient descent. Evaluate the gradient at the current parameter, multiply by the learning rate and subtract. If the objective is supplied, differentiate it and recompute the gradient after each update.
θ (theta) = trainable parameter; g = derivative of the stated objective J; η = learning rate; t labels the update number.
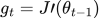 LaTeX:
g_t=J\prime(\theta_{t-1})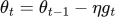 LaTeX:
\theta_t=\theta_{t-1}-\eta g_tYaad rakhne ka cue: Naya = purana − learning rate × current gradient.
Solution — step by step
Meaning of the symbols
θ (theta) is the number we update. η (eta) is learning rate 0.1. g is the derivative of the objective, evaluated at the required position. A subscript counts updates; θ₀ means the starting value.
Differentiate the objective first
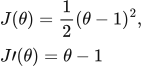 LaTeX:
J(\theta)=\frac12(\theta-1)^2,\qquad J\prime(\theta)=\theta-1The power rule brings down 2, which cancels the half. The inside derivative is 1, so the remaining gradient is θ minus 1.
Update formulas
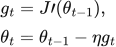 LaTeX:
g_t=J\prime(\theta_{t-1}),\quad \theta_t=\theta_{t-1}-\eta g_tStep 1: Update 1.
 LaTeX:
g_1=-0.5-(1)=-1.5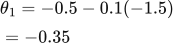 LaTeX:
\theta_1=-0.5-0.1(-1.5)=-0.35Step 2: Update 2.
 LaTeX:
g_2=-0.35-(1)=-1.35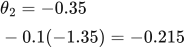 LaTeX:
\theta_2=-0.35-0.1(-1.35)=-0.215Final parameter after two updates: -0.215. The second gradient is evaluated again using the parameter obtained after the first update.