Deep Learning · MT2 · section
Drill 31 Inverted dropout
MT2 numerical practice from direct to mixed
Question
Question. Activations = [2,−1,0,3], keep probability 0.75, mask = [1,0,1,1]. Find training outputs and explain inference.
Answer — step by step
Given
Activations = [2,−1,0,3].
Keep probability q = 0.75; keep mask = [1,0,1,1].
To find
Find training outputs and state the inference rule.
Formula — which one and why
Inverted dropout. Multiply by the keep/drop mask, then divide retained activations by the keep probability. This preserves each activation’s expectation over random masks.
aᵢ = original activation; mᵢ is 1 to keep or 0 to drop; q = keep probability = 1−dropout rate. Disable this masking/scaling at inference.
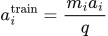 LaTeX:
a_i^{\mathrm{train}}=\frac{m_ia_i}{q} LaTeX:
a_i^{\mathrm{test}}=a_iYaad rakhne ka cue: Mask se keep/drop; kept value ko keep probability se divide.
Solution — step by step
Meaning and formula
The mask entry m is 1 when an activation is kept and 0 when dropped. The keep probability q is 0.75. Inverted dropout divides the kept activations by q during training so that their expected value is preserved.
 LaTeX:
a'_j=\frac{m_j a_j}{q}The multiplication is entry by entry; there is no dot-product sum.
Step 1: apply the mask
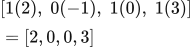 LaTeX:
[1(2),\;0(-1),\;1(0),\;1(3)]=[2,0,0,3]Step 2: divide each result by 0.75
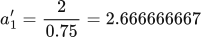 LaTeX:
a'_1=\frac2{0.75}=2.666666667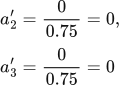 LaTeX:
a'_2=\frac0{0.75}=0,\qquad a'_3=\frac0{0.75}=0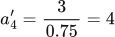 LaTeX:
a'_4=\frac3{0.75}=4Training output = [2.666666667, 0, 0, 4]. A kept activation that was already zero stays zero.
During inference
Disable the random mask and the division. If the incoming activations are the same [2,−1,0,3], they pass through unchanged. The scaling has already been accounted for during training.