Deep Learning · MT2 · section
Drill 44 Inception concatenation and parameter count
MT2 numerical practice from direct to mixed
Question
Question. Input 10 × 10 × 8. Parallel branches: A uses 1 × 1 conv 4 filters ; B uses 3 × 3 same Conv 6 filters; C max pool 3 same, stride 1 then 1 × 1 conv 2 filters. Find combined shape and trainable parameters.
Answer — step by step
Given
Input = 10 × 10 × 8.
Branch A: 1 × 1 convolution, 4 filters.
Branch B: 3 × 3 same convolution, 6 filters.
Branch C: 3 × 3 same max pool with stride 1, then 1 × 1 convolution, 2 filters.
To find
Find each branch shape and parameters, then the concatenated shape and total parameters.
Formula — which one and why
Inception channel concatenation. Parallel branches retain their separate features. Add their channel counts while keeping the common height and width. Add trainable parameters across branches.
C₁,C₂,… = branch output channels. Concatenation requires matching spatial dimensions.
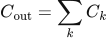 LaTeX:
C_{\mathrm{out}}=\sum_k C_k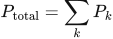 LaTeX:
P_{\mathrm{total}}=\sum_k P_kYaad rakhne ka cue: Channels jodo; height-width same rakho.
Convolution parameters. Every filter spans all input channels. Count its spatial coefficients across those channels, add one bias and multiply by the number of filters.
K_h,K_w = filter height/width; C_in = input channels; C_out = number of filters and output channels. Spatial output positions reuse these weights.
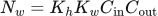 LaTeX:
N_w=K_hK_wC_{\mathrm{in}}C_{\mathrm{out}} LaTeX:
N_b=C_{\mathrm{out}}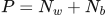 LaTeX:
P=N_w+N_bYaad rakhne ka cue: Filter area × input channels × filters; phir ek bias per filter.
Solution — step by step
Meaning and formulas
Each parallel branch receives the same original 10 × 10 × 8 input. “Same” with stride 1 preserves height and width. Concatenation joins the channel lists without adding the feature values.
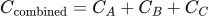 LaTeX:
C_{\mathrm{combined}}=C_A+C_B+C_C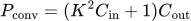 LaTeX:
P_{\mathrm{conv}}=(K^2C_{\mathrm{in}}+1)C_{\mathrm{out}}Assume one bias per filter. Pooling has no learned parameters.
Step 1: Branch A.
Its 4 filters produce shape 10 × 10 × 4.
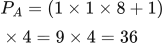 LaTeX:
P_A=(1\times1\times8+1)\times4=9\times4=36Step 2: Branch B.
Its 6 filters produce shape 10 × 10 × 6.
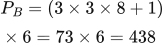 LaTeX:
P_B=(3\times3\times8+1)\times6=73\times6=438Step 3: Branch C.
Pooling preserves 10 × 10 × 8 here because stride is 1 and padding is same. Its parameter count is zero. The following 2-filter projection creates 10 × 10 × 2.
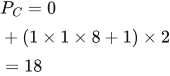 LaTeX:
P_C=0+(1\times1\times8+1)\times2=18Step 4: Join the shapes and add the parameters.
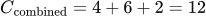 LaTeX:
C_{\mathrm{combined}}=4+6+2=12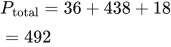 LaTeX:
P_{\mathrm{total}}=36+438+18=492Final answer: combined shape 10 × 10 × 12; 492 parameters. Branch B does not take branch A's four channels as input: they are parallel branches.