Deep Learning · MT2 · section
Drill 7 Sigmoid with binary cross entropy
MT2 numerical practice from direct to mixed
Question
Question. A binary classifier has logit z = 1, target 1. Find probability, BCE and the gradient with respect to z.
Answer — step by step
Given
Logit z = 1; binary target y = 1.
Output: sigmoid; loss: binary cross-entropy.
To find
Find probability, BCE and the loss derivative with respect to z.
Formula — which one and why
Sigmoid and its slope. Use sigmoid when the neuron is specified to squash its preactivation into (0,1). Once its output is known, its derivative needs only output × (1−output).
z = preactivation; p = sigmoid output; e is the exponential base, not a prediction error in this formula.
 LaTeX:
p=\frac{1}{1+e^{-z}}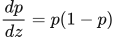 LaTeX:
\frac{dp}{dz}=p(1-p)Yaad rakhne ka cue: Sigmoid output p; uska slope p × (1−p).
Binary cross-entropy. For a binary target, choose the probability of the correct outcome and take its negative natural log. Sigmoid plus BCE has combined logit derivative p−y.
y is 0 or 1; p is the predicted probability of class 1; z is the sigmoid logit. The p−y derivative already includes the sigmoid derivative.
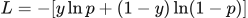 LaTeX:
L=-[y\ln p+(1-y)\ln(1-p)] LaTeX:
\frac{\partial L}{\partial z}=p-yYaad rakhne ka cue: Binary target 1 ho toh −ln(p); target 0 ho toh −ln(1−p).
Solution — step by step
Meaning and formulas
A logit is the raw score before sigmoid. Sigmoid converts it to a probability p. The target y = 1 says the positive class is correct. Binary cross-entropy measures how little probability the model assigned to the correct binary outcome.
 LaTeX:
p=\frac1{1+e^{-z}}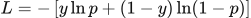 LaTeX:
L=-\left[y\ln p+(1-y)\ln(1-p)\right]For sigmoid combined with this loss, the gradient with respect to the logit has the simplified form:
LaTeX: \frac{\partial L}{\partial z}=p-yStep 1: convert logit 1 into probability
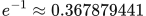 LaTeX:
e^{-1}\approx0.367879441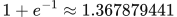 LaTeX:
1+e^{-1}\approx1.367879441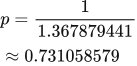 LaTeX:
p=\frac1{1.367879441}\approx0.731058579Step 2: substitute the target in the full loss formula
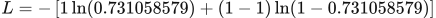 LaTeX:
L=-\left[1\ln(0.731058579)+(1-1)\ln(1-0.731058579)\right]The second term has multiplier zero, so it contributes zero.
 LaTeX:
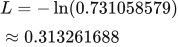
L=-\ln(0.731058579)\approx0.313261688Step 3: calculate the combined gradient
 LaTeX:
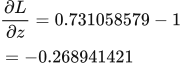
\frac{\partial L}{\partial z}=0.731058579-1=-0.268941421Final answer: probability ≈ 0.731059; BCE ≈ 0.313262; logit gradient ≈ −0.268941. The simplified gradient already includes sigmoid's effect. Multiplying by sigmoid's slope again would apply it twice.