Deep Learning · MT2 · section
The derivative of prediction error
The maths behind a network
For the half squared loss, use prediction minus target. Let target be y and prediction be ŷ.
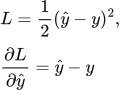 LaTeX:
L=\frac12(\hat y-y)^2,\qquad \frac{\partial L}{\partial \hat y}=\hat y-yThe 2 from differentiating a square cancels the half. Writing the loss as ½(y − ŷ)² gives the same derivative: the derivative of the inside y − ŷ adds a minus sign. This is why “target minus prediction” without the extra minus gives the wrong gradient.
If the question uses plain squared error, its derivative is 2(ŷ − y). If it averages errors over n values, also divide by n. Read the stated loss before using a memorized gradient.