Deep Learning · MT2 · section
Model answer: forward propagation, backpropagation and updating
Neural-network foundations
Question
Question. Explain how a feedforward neural network learns using forward propagation, a loss function, backpropagation and gradient descent. State the order of operations.
Answer — step by step
Training repeatedly uses labeled examples to improve a network's weights and biases. The four operations have different jobs.
| Operation | Direction or action | Result |
|---|---|---|
| Forward propagation | Inputs move through successive layers | Predictions and intermediate activations |
| Loss calculation | Compare predictions with targets | A scalar objective for the example or batch |
| Backpropagation | Apply the chain rule from the loss toward earlier layers | Gradients of the objective with respect to parameters |
| Optimizer update | Use those gradients to change parameters | A new set of weights and biases |
1. Forward propagation
At each layer, calculate its weighted sums and activations. Retain these values because derivatives such as the sigmoid derivative depend on them. Complete a whole layer before calculating the next.
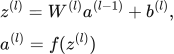 LaTeX:
z^{(l)}=W^{(l)}a^{(l-1)}+b^{(l)},\qquad a^{(l)}=f(z^{(l)})2. Loss
Use the loss specified by the task. For one regression output, half squared loss is one possible choice:
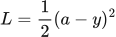 LaTeX:
L=\frac12(a-y)^2Here a is the prediction and y is the target. Other stated losses produce different derivatives.
3. Backpropagation
Multiply local derivatives along each dependency path. If a hidden unit influences several outputs, add the contributions from those branches. For a connection, the weight gradient is the receiving neuron's net-input derivative multiplied by the sending activation.
 LaTeX:
\frac{\partial L}{\partial w_{ji}}=\delta_j a_iHere δⱼ means the derivative of loss with respect to the receiving neuron's weighted sum. It is not automatically equal to raw prediction error; the activation and loss determine it.
4. Update and repeat
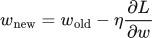 LaTeX:
w_{\mathrm{new}}=w_{\mathrm{old}}-\eta\frac{\partial L}{\partial w}Compute all gradients using the same pre-update weights. Then update the requested parameters. Run another forward pass to calculate the new loss. Backpropagation calculates gradients; gradient descent uses them. Those are related, separate operations.