Deep Learning · MT2 · section
Model answer: momentum and Nesterov
Optimization algorithms
Question
Question. Explain momentum and Nesterov accelerated gradient. How does the point at which the gradient is measured differ?
Answer — step by step
Momentum retains a fraction of the previous movement and combines it with the current gradient correction. Movement in a persistent direction can build up, while alternating directions can partially cancel. This can reduce zig-zagging and improve progress through poorly scaled regions.
Momentum formulas
This answer uses signed displacement velocity v: a negative velocity moves the parameter left. η is learning rate and β is the fraction of previous velocity retained.
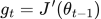 LaTeX:
g_t=J'(\theta_{t-1})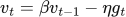 LaTeX:
v_t=\beta v_{t-1}-\eta g_t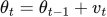 LaTeX:
\theta_t=\theta_{t-1}+v_tNesterov's change
Nesterov first forms a lookahead position using the old momentum. It measures the gradient there, then computes a new velocity and updates the actual old parameter.
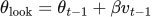 LaTeX:
\theta_{\mathrm{look}}=\theta_{t-1}+\beta v_{t-1}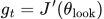 LaTeX:
g_t=J'(\theta_{\mathrm{look}})The velocity and parameter update formulas remain as displayed above. Add the new velocity to θ at the previous iteration, not to the lookahead point.
| Basis | Momentum | Nesterov |
|---|---|---|
| Gradient evaluated at | Current parameter | Lookahead parameter |
| Information retained | Previous velocity | Previous velocity |
| Intuition | Continue useful movement | Inspect the slope where old momentum points |
| Initial zero velocity | No movement contribution yet | First lookahead equals current parameter |
Both require suitable learning rate and momentum settings. Neither guarantees the global minimum of a general neural-network objective. Different books use different definitions of stored velocity, so the definition and update must be used together consistently.