Deep Learning · MT2 · section
Model answer: dropout with training and inference explained
Regularization and generalization
Question
Question. Explain dropout as a regularization technique. Distinguish its behavior during training and inference, and explain inverted-dropout scaling.
Answer — step by step
Dropout randomly replaces selected activations by zero during training. It discourages excessive reliance on particular units and their joint activity. The mask changes between training applications; it does not permanently remove neurons or stored weights.
Let p be the probability of dropping an activation and q = 1 − p the probability of keeping it. A mask value m = 1 means keep; m = 0 means drop.
Inverted dropout during training
 LaTeX:
a'=\frac{ma}{q}A kept activation is divided by q and a dropped activation becomes zero. This preserves the activation's expectation over masks.
For a = 3 and q = 0.5, the kept result is 3/0.5 = 6 and the dropped result is 0. Their probability-weighted average is:
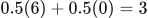 LaTeX:
0.5(6)+0.5(0)=3Inference
Disable dropout and use the ordinary activation. Under inverted dropout there is no further division or multiplication by q at inference. Under the alternative classical convention, training does not rescale kept activations and inference includes the compensating scaling; do not combine the two conventions.
Dropout has no trainable mask parameters. A dropped path contributes zero current data gradient through that activation, although a separately specified weight penalty can still contribute a parameter gradient. Excessive dropout can make optimization or fitting difficult. Choose its rate using validation data.