Deep Learning · MT2 · section
VGG16: small filters in a regular sequence
CNN architectures and transfer learning
Definition. VGG16 is a convolutional architecture with 13 convolutional layers and three dense layers. Its standard convolution blocks contain 2, 2, 3, 3 and 3 convolutions. Pooling, activations and flattening are not counted in the name's 16 weight layers.
Each convolution uses a 3 × 3 kernel, stride 1 and padding 1, preserving height and width. Each block ends with 2 × 2 max pooling of stride 2. The final classifier is 4,096 → 4,096 → 1,000 for the original 1,000-class task.
| Block | Convolutions | Channels after its convolutions | Size after its pooling |
|---|---|---|---|
| 1 | Two | 64 | 112 × 112 × 64 |
| 2 | Two | 128 | 56 × 56 × 128 |
| 3 | Three | 256 | 28 × 28 × 256 |
| 4 | Three | 512 | 14 × 14 × 512 |
| 5 | Three | 512 | 7 × 7 × 512 |
This table starts with 224 × 224 × 3. The flattened length is 7 × 7 × 512 = 25,088. Flattening has zero learned parameters. Stacking small filters provides repeated nonlinear transformations while progressively combining spatial information. A limitation is the large dense classifier and its memory cost.
Question (practice, 3 marks). VGG16's first block contains two same-padded 3 × 3 convolutions with 64 output filters each, followed by 2 × 2 max pooling with stride 2. Input is 224 × 224 × 3. Find both convolution parameter counts including bias and the pooled output shape.
Given
Conv1: 3 input channels, 64 output channels. Conv2: 64 input channels, 64 output channels. Both have kernel 3, stride 1 and padding 1. Pooling has kernel 2, stride 2 and no padding.
To find
Trainable parameters in each convolution and the output after pooling.
Formula — which one and why
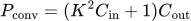 LaTeX:
P_{\mathrm{conv}}=(K^2C_{\mathrm{in}}+1)C_{\mathrm{out}}Use each layer's own input depth; the second layer receives the first layer's 64 maps. Use the spatial-output formula for pooling. Max pooling introduces no trainable parameters.
Solution — step by step
Step 1: first convolution. Each filter has 3 × 3 × 3 = 27 weights and one bias.
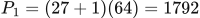 LaTeX:
P_1=(27+1)(64)=1792Step 2: second convolution. Each filter now spans 64 channels, giving 3 × 3 × 64 = 576 weights.
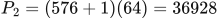 LaTeX:
P_2=(576+1)(64)=36928Step 3: add parameters.
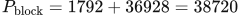 LaTeX:
P_{\mathrm{block}}=1792+36928=38720Step 4: calculate pooled side length. The same-padded convolutions retained side length 224.
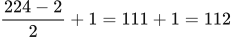 LaTeX:
\frac{224-2}{2}+1=111+1=112Final answer: 1,792 and 36,928 parameters; total = 38,720; pooled shape = 112 × 112 × 64.
Exam convention: use the architecture explicitly supplied in a calculation. For the standard VGG16 architecture, remember 2–2–3–3–3 convolutions and 2 × 2 pooling; 25,088 is the flattened feature length.