Deep Learning · MT2 · section
A complete vector RNN calculation
Recurrent neural networks
Question from R26 Q5a. xₜ = [0,1], hₜ₋₁ = [0,1], no bias is supplied, Wxh is shown below, Whh is shown below. Use tanh and rows as receiving neurons.
Given
Input x = [0,1]ᵀ; previous h = [0,1]ᵀ.
Wxh =  LaTeX:
\begin{bmatrix}0.6 & 0.4\\0.3 & 0.7\end{bmatrix}.
Whh =  LaTeX:
\begin{bmatrix}0.5 & 0.3\\0.2 & 0.4\end{bmatrix}; bias = 0.
Apply tanh separately to the two sums.
To find
Find the new two-component hidden state; output-layer parameters are not supplied.
Formula — which one and why
Recurrent forward pass. At each time step, combine the current input contribution with the previous activated hidden state, add the bias and apply tanh. The same weights are reused at every time step.
x_t = current input; h_(t−1) = previous hidden state; W_xh = input weights; W_hh = recurrent weights; b = bias.
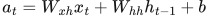 LaTeX:
a_t=W_{xh}x_t+W_{hh}h_{t-1}+b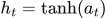 LaTeX:
h_t=\tanh(a_t)Yaad rakhne ka cue: Naya input + pichhla activated state; phir activation.
Solution — step by step
Step 1 new input: Wxh x = [0.6 × 0 + 0.4 × 1, 0.3 × 0 + 0.7 × 1] = [0.4,0.7].
Step 2 old memory: Whh hprevious = [0.5 × 0 + 0.3 × 1, 0.2 × 0 + 0.4 × 1] = [0.3,0.4].
Step 3 add: a = [0.4+0.3, 0.7+0.4] = [0.7,1.1].
Step 4 activate each element: h = [tanh(0.7), tanh(1.1)] = [0.604368,0.800499]. An output-layer prediction cannot be numerically calculated without its weights and bias.