Deep Learning · TEE · formulas
Categorical cross entropy
For one-hot multiclass targets, only one target entry is 1. The other entries are zero, so the loss becomes minus the logarithm of the true class probability. The worked question first calculates every softmax probability, then selects the correct one.
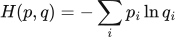 LaTeX:
H(p,q)=-\sum_i p_i\ln q_i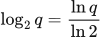 LaTeX:
\log_2q=\frac{\ln q}{\ln2}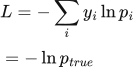 LaTeX:
L=-\sum_i y_i\ln p_i=-\ln p_{true}Cross-entropy for probability distributions
Definition. For a discrete target distribution p and a predicted distribution q over the same classes, cross-entropy is the target-weighted negative logarithm of the predicted probabilities.
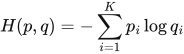 LaTeX:
H(p,q)=-\sum_{i=1}^{K}p_i\log q_iHere pᵢ and qᵢ refer to the same class i, and each distribution sums to 1. The target supplies the weights outside the logarithm; the prediction goes inside it. If the target is one-hot, only the correct-class term remains. For a soft target with several nonzero entries, include all its nonzero terms.
Logarithm base and units
Natural logarithms produce nats; base-2 logarithms produce bits. These notes use ln unless a question states another base. On a calculator with ln, use the change-of-base rule for base 2:
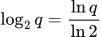 LaTeX:
\log_2 q=\frac{\ln q}{\ln 2}For a target entry pᵢ = 0, its contribution is defined as zero. If pᵢ > 0 but qᵢ = 0, the loss is infinite. For numerical stability, software normally calculates cross-entropy from logits or carefully handles boundary probabilities.
A target distribution with two nonzero entries
Question. A two-class target distribution is p = [0.75, 0.25] and the model predicts q = [0.5, 0.5]. Calculate cross-entropy using natural logarithms and using base-2 logarithms.
Given
A two-class target distribution is p = [0.75, 0.25] and the model predicts q = [0.5, 0.5].
Calculate cross-entropy using natural logarithms and using base-2 logarithms.
To find
Find cross-entropy in the requested units.
Formula — which one and why
Cross-entropy between distributions. Weight each negative log prediction by the target probability. Unlike one-hot targets, several terms can contribute.
pᵢ = target-distribution probability; qᵢ = predicted probability. Natural logs give nats; base-2 logs give bits.
LaTeX: H(p,q)=-\sum_i p_i\ln q_i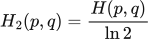 LaTeX:
H_2(p,q)=\frac{H(p,q)}{\ln2}Yaad rakhne ka cue: Target probability batati hai kis log-loss ka kitna hissa lena hai.
Solution — step by step
Step 1: write the two terms. Both target entries are nonzero, so neither term can be discarded.
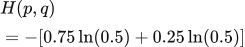 LaTeX:
H(p,q)=-[0.75\ln(0.5)+0.25\ln(0.5)]Step 2: calculate the logarithms.
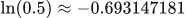 LaTeX:
\ln(0.5)\approx-0.693147181Step 3: weight each negative logarithm by its target probability.
 LaTeX:
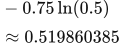
-0.75\ln(0.5)\approx0.519860385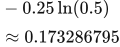 LaTeX:
-0.25\ln(0.5)\approx0.173286795Step 4: add the contributions, retaining calculator precision.
 LaTeX:
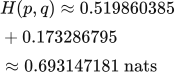
H(p,q)\approx0.519860385+0.173286795\approx0.693147181\ \text{nats}Step 5: repeat with base 2. Since 2⁻¹ = 0.5, log₂(0.5) = −1.
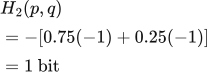 LaTeX:
H_2(p,q)=-[0.75(-1)+0.25(-1)]=1\ \text{bit}Final answer: 0.693147 nats or 1 bit. The distributions are unchanged; the logarithm base changes the unit and the numerical scale.
Cross-entropy, entropy and relative entropy
These names are related but do not denote the same quantity. Entropy uses the target distribution in both positions. Relative entropy, also called KL divergence, measures their difference through a probability ratio.
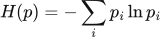 LaTeX:
H(p)=-\sum_i p_i\ln p_i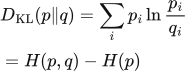 LaTeX:
D_{\mathrm{KL}}(p\Vert q)=\sum_i p_i\ln\frac{p_i}{q_i}=H(p,q)-H(p)For fixed p, H(p) is constant with respect to the model parameters, so minimizing cross-entropy also minimizes this KL divergence. KL is clarified here to distinguish the terminology; it is not a separately named unit in the official syllabus.
Question. For the same p = [0.75, 0.25] and q = [0.5, 0.5], find H(p) and DKL(p ∥ q) in nats.
Given
For the same p = [0.75, 0.25] and q = [0.5, 0.5], find H(p) and DKL(p ∥ q) in nats.
To find
Find entropy and KL divergence in nats.
Formula — which one and why
Entropy and relative entropy. Entropy measures the target distribution’s uncertainty. Relative entropy measures the extra cross-entropy when q is used instead of p.
p = target distribution; q = model distribution; H(p) = entropy; DKL = Kullback–Leibler divergence.
LaTeX: H(p)=-\sum_i p_i\ln p_i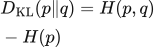 LaTeX:
D_{\mathrm{KL}}(p\Vert q)=H(p,q)-H(p)Yaad rakhne ka cue: KL = cross-entropy minus target ki own entropy.
Solution — step by step
Step 1: calculate the target entropy.
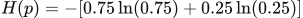 LaTeX:
H(p)=-[0.75\ln(0.75)+0.25\ln(0.25)]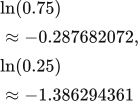 LaTeX:
\ln(0.75)\approx-0.287682072,\qquad\ln(0.25)\approx-1.386294361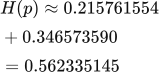 LaTeX:
H(p)\approx0.215761554+0.346573590=0.562335145Step 2: subtract target entropy from cross-entropy.
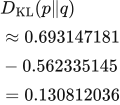 LaTeX:
D_{\mathrm{KL}}(p\Vert q)\approx0.693147181-0.562335145=0.130812036Final answer: H(p) ≈ 0.562335 nats and DKL(p ∥ q) ≈ 0.130812 nats. For a one-hot target H(p) = 0, so cross-entropy and this KL divergence coincide; for this soft target they differ.
Drill 9 Softmax and true class loss
Question
Question. Scores = [1,2,0], true one-hot class = [0,1,0]. Find probabilities and categorical cross-entropy.
Answer — step by step
Given
Logits = [1,2,0].
One-hot target = [0,1,0]: class 2 is correct.
To find
Find all three softmax probabilities and CCE.
Formula — which one and why
Stable softmax. Exponentiate each logit and divide by the sum. Subtracting the largest logit first keeps the exponentials numerically manageable and leaves the probabilities unchanged.
zⱼ = class j score; M = largest score; pⱼ = class j probability. All probabilities sum to 1.
 LaTeX:
M=\max_j z_j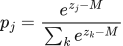 LaTeX:
p_j=\frac{e^{z_j-M}}{\sum_k e^{z_k-M}}Yaad rakhne ka cue: Largest score ghatao, exp nikalo, total se sabko divide karo.
Categorical cross-entropy. For mutually exclusive classes with a one-hot target, all zero-target terms disappear. The loss is the negative log of the probability assigned to the true class.
yⱼ = target entry; pⱼ = predicted probability; c = index of the true class. Use natural logarithms unless another base is specified.
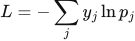 LaTeX:
L=-\sum_j y_j\ln p_j LaTeX:
L=-\ln p_cYaad rakhne ka cue: One-hot mein sirf correct class ki probability ka minus ln.
Solution — step by step
Meaning and formulas
The scores z are raw class scores. Softmax converts the whole group into class probabilities. The label [0,1,0] says class 2 is correct; it is not a set of predicted probabilities.
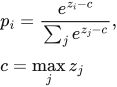 LaTeX:
p_i=\frac{e^{z_i-c}}{\sum_j e^{z_j-c}},\qquad c=\max_jz_jSubtracting the same c from every score keeps the probabilities unchanged and avoids very large exponentials.
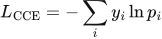 LaTeX:
L_{\mathrm{CCE}}=-\sum_i y_i\ln p_iStep 1: subtract the largest score
The largest of [1,2,0] is 2.
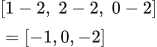 LaTeX:
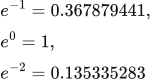
[1-2,\;2-2,\;0-2]=[-1,0,-2]Step 2: calculate the three exponentials
 LaTeX:
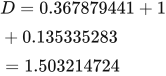
e^{-1}=0.367879441,\quad e^0=1,\quad e^{-2}=0.135335283Step 3: add them to get one common denominator
 LaTeX:
D=0.367879441+1+0.135335283=1.503214724Step 4: divide each exponential by this denominator
 LaTeX:
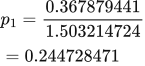
p_1=\frac{0.367879441}{1.503214724}=0.244728471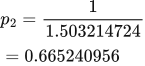 LaTeX:
p_2=\frac{1}{1.503214724}=0.665240956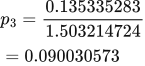 LaTeX:
p_3=\frac{0.135335283}{1.503214724}=0.090030573The probabilities add to 1, apart from rounding. Class 2 has the highest score and the highest probability.
Step 5: use the probability of the correct class in CCE
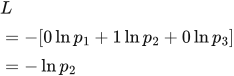 LaTeX:
L=-[0\ln p_1+1\ln p_2+0\ln p_3]=-\ln p_2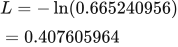 LaTeX:
L=-\ln(0.665240956)=0.407605964Final answer: probabilities ≈ [0.244728, 0.665241, 0.090031]; CCE ≈ 0.407606.