Deep Learning · TEE · formulas
Adam: both memories
Adam keeps two separate running averages. The first remembers signed gradients and can be negative. The second remembers squared gradients and is nonnegative. These stored averages are not weights, and they are not extra gradients to multiply together.
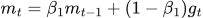 LaTeX:
m_t=\beta_1m_{t-1}+(1-\beta_1)g_t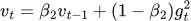 LaTeX:
v_t=\beta_2v_{t-1}+(1-\beta_2)g_t^2Optimizer notation: old value, memory, new value
1. A parameter and a stored state are different
θ is the parameter we want to learn. A memory such as v, s or m helps an optimizer decide how to change θ; it is not a second prediction. Each trainable parameter usually has its own corresponding memory entries.
At time t = 0, the problem supplies starting values. At update t = 1, read the old values, calculate the current gradient and new memory, then calculate the new parameter. At update t = 2, use the results of update 1 as the old values.
2. A supplied gradient versus a supplied objective
If the question says gradients are 2 and −1, use those values in order. If it instead gives J(θ) = θ², first differentiate to get g(θ) = 2θ. Recalculate g using the current parameter at each iteration. Nesterov evaluates at its lookahead point instead.
For θ₀ = 1 and η = 0.1 with ordinary GD, g₁ = 2 and θ₁ = 0.8. The next gradient is 2 × 0.8 = 1.6, not the old value 2. Therefore θ₂ = 0.8 − 0.1 × 1.6 = 0.64.
3. A squared gradient keeps size and loses sign
Both 2² and (−2)² equal 4. Squared-gradient memory tells us about scale. The signed numerator still decides the update direction. Never replace the gradient in every part of an optimizer by its square.
4. Square root and epsilon belong to the denominator
If s = 4 and ε = 0.01, the denominator √s + ε is 2 + 0.01 = 2.01. It is different from √(s + ε), which is √4.01. Use the placement specified by the formula. Small ε keeps a zero accumulator from causing division by zero.
5. A table prevents mixing iterations
Write one row per iteration. Ordinary GD needs current θ, gradient and new θ. Momentum adds old and new velocity. Adam adds both memories and their corrected values. Complete a row before starting the next; otherwise a new value from iteration 2 may accidentally be used inside iteration 1.
The worked examples below use this exact order, with every state shown.
Adam remembers both direction and squared size
Definition. Adam, or adaptive moment estimation, uses bias-corrected exponentially weighted estimates of the first moment and the uncentered second moment of gradients to calculate parameter-specific updates.
What the two states represent
| State or coefficient | Meaning |
|---|---|
| mₜ | Moving average of signed gradients; retains directional information |
| sₜ | Moving average of squared gradients; estimates their uncentered second moment |
| β₁ | Decay coefficient for the first-moment estimate |
| β₂ | Decay coefficient for the second-moment estimate |
| t | Update number, starting at 1 for the first update |
| η and ε | Base learning rate and small denominator stabilizer |
The second moment is not the variance: it averages g² without subtracting a mean. Both states start at zero unless specified otherwise. These notes use s throughout this lesson; texts that use v for Adam's second moment mean the same state, not momentum's displacement velocity.
Recurrences, bias correction and update
LaTeX: m_t=\beta_1m_{t-1}+(1-\beta_1)g_t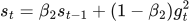 LaTeX:
s_t=\beta_2s_{t-1}+(1-\beta_2)g_t^2Zero initialization reduces the total weight initially attached to observed gradients. Divide by the appropriate accumulated observation weight:
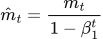 LaTeX:
\hat m_t=\frac{m_t}{1-\beta_1^t} LaTeX:
\hat s_t=\frac{s_t}{1-\beta_2^t}The update uses the corrected signed average in the numerator and the root of the corrected squared-gradient average in the denominator:
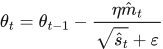 LaTeX:
\theta_t=\theta_{t-1}-\frac{\eta\hat m_t}{\sqrt{\hat s_t}+\varepsilon}The derivation in the next lesson explains why the correction factors contain powers of the iteration number. No additional multiplication by gₜ belongs in this final update: its contribution is already inside mₜ.
Complete numerical: changing gradient magnitude
Question. θ₀ = 1, m₀ = s₀ = 0, η = 0.1, β₁ = 0.9, β₂ = 0.999. Given g₁ = 2 and g₂ = 1, find two Adam updates, neglecting epsilon only in the numerical arithmetic.
Given
θ₀ = 1; initial state(s) = 0; η = 0.1.
Supplied gradients g₁ = 2, g₂ = 1.
ε = 0 for this hand calculation.
β₁ = 0.9; β₂ = 0.999; use bias correction.
To find
Calculate all required states and the parameter after each of two updates.
Formula — which one and why
Adam with bias correction. Keep two states: one averages signed gradients, the other averages squared gradients. Correct their initial bias toward zero before combining them in the parameter update.
m = signed average; s (also written v) = squared average; β₁ and β₂ = retained fractions; t = iteration number. A hat marks a corrected value. Carry raw m and s into the next recurrence.
LaTeX: m_t=\beta_1m_{t-1}+(1-\beta_1)g_tLaTeX: s_t=\beta_2s_{t-1}+(1-\beta_2)g_t^2LaTeX: \hat m_t=\frac{m_t}{1-\beta_1^t}LaTeX: \hat s_t=\frac{s_t}{1-\beta_2^t}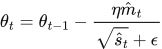 LaTeX:
\theta_t=\theta_{t-1}-\frac{\eta\hat m_t}{\sqrt{\hat s_t}+\epsilon}Yaad rakhne ka cue: Direction memory + square memory; hats lagao, phir update.
Solution — step by step
Iteration 1 — step 1: update the two raw states.
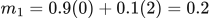 LaTeX:
m_1=0.9(0)+0.1(2)=0.2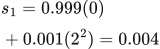 LaTeX:
s_1=0.999(0)+0.001(2^2)=0.004Step 2: correct both states using t = 1.
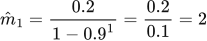 LaTeX:
\hat m_1=\frac{0.2}{1-0.9^1}=\frac{0.2}{0.1}=2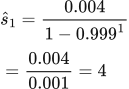 LaTeX:
\hat s_1=\frac{0.004}{1-0.999^1}=\frac{0.004}{0.001}=4Step 3: update the parameter.
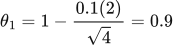 LaTeX:
\theta_1=1-\frac{0.1(2)}{\sqrt4}=0.9Start with the current gradient and the two states saved from the previous iteration.
Carry forward raw states: m = 0.2, s = 0.004. The corrected values are used for this update.
Iteration 2 — step 1: carry forward the raw states m₁ and s₁.
The recurrence uses the raw states 0.2 and 0.004, not the corrected values 2 and 4.
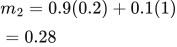 LaTeX:
m_2=0.9(0.2)+0.1(1)=0.28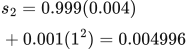 LaTeX:
s_2=0.999(0.004)+0.001(1^2)=0.004996Step 2: correct both states using t = 2.
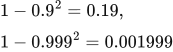 LaTeX:
1-0.9^2=0.19,\qquad1-0.999^2=0.001999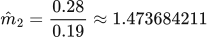 LaTeX:
\hat m_2=\frac{0.28}{0.19}\approx1.473684211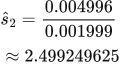 LaTeX:
\hat s_2=\frac{0.004996}{0.001999}\approx2.499249625Step 3: divide the corrected first moment by the corrected root.
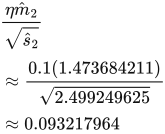 LaTeX:
\frac{\eta\hat m_2}{\sqrt{\hat s_2}}\approx\frac{0.1(1.473684211)}{\sqrt{2.499249625}}\approx0.093217964Step 4: update from θ₁.
 LaTeX:
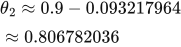
\theta_2\approx0.9-0.093217964\approx0.806782036Start with the current gradient and the two states saved from the previous iteration.
Carry forward raw states: m = 0.28, s = 0.004996. The corrected values are used for this update.
| State | After iteration 1 | After iteration 2 |
|---|---|---|
| Raw first moment m | 0.2 | 0.28 |
| Raw second moment s | 0.004 | 0.004996 |
| Corrected first moment | 2 | 1.473684211 |
| Corrected second moment | 4 | 2.499249625 |
| Parameter θ | 0.9 | 0.806782036 |
Final answer: θ₁ = 0.9 and θ₂ ≈ 0.806782. Store the raw moments for the next recurrence and use the corrected moments for the current parameter update.
Properties and limitations
Adam combines directional averaging with coordinate-specific scaling, which can be useful with noisy or differently scaled gradients. It requires two state values per parameter in addition to the parameter itself. η, β₁, β₂ and ε remain hyperparameters. Faster reduction of training loss does not establish better generalization, and Adam does not guarantee the global optimum of a general neural-network objective.
Drill 28 Adam variation 1
Question
Question. θ₀ = 1, η = 0.1, supplied successive gradients = [2, 1]. Use Adam for two updates, zero initial accumulators and ε = 0 for this hand calculation. Use β₁ = 0.9, β₂ = 0.999 and bias correction.
Answer — step by step
Given
Initial θ₀ = 1; η = 0.1.
Supplied gradients: [2,1].
Initial accumulator(s) = 0; ε = 0 for this nonzero-denominator hand calculation.
β₁ = 0.9; β₂ = 0.999; use bias correction.
To find
Find every stored state needed by the method and the parameter after each of two updates.
Formula — which one and why
Adam with bias correction. Keep two states: one averages signed gradients, the other averages squared gradients. Correct their initial bias toward zero before combining them in the parameter update.
m = signed average; s (also written v) = squared average; β₁ and β₂ = retained fractions; t = iteration number. A hat marks a corrected value. Carry raw m and s into the next recurrence.
LaTeX: m_t=\beta_1m_{t-1}+(1-\beta_1)g_tLaTeX: s_t=\beta_2s_{t-1}+(1-\beta_2)g_t^2LaTeX: \hat m_t=\frac{m_t}{1-\beta_1^t}LaTeX: \hat s_t=\frac{s_t}{1-\beta_2^t}LaTeX: \theta_t=\theta_{t-1}-\frac{\eta\hat m_t}{\sqrt{\hat s_t}+\epsilon}Yaad rakhne ka cue: Direction memory + square memory; hats lagao, phir update.
Solution — step by step
Symbols and formulas used
θ is the parameter; η is the base learning rate; gₜ is the supplied gradient for update t. The gradients are already given, so no loss differentiation is needed here. Use ε = 0 only as specified in this exercise.
m remembers signed gradients; v remembers squared gradients. The hats mean bias-corrected values, compensating for memories starting at zero. They are not extra powers. Here β₁ = 0.9 and β₂ = 0.999.
LaTeX: m_t=\beta_1m_{t-1}+(1-\beta_1)g_tLaTeX: v_t=\beta_2v_{t-1}+(1-\beta_2)g_t^2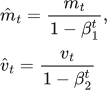 LaTeX:
\hat m_t=\frac{m_t}{1-\beta_1^t},\qquad \hat v_t=\frac{v_t}{1-\beta_2^t}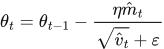 LaTeX:
\theta_t=\theta_{t-1}-\frac{\eta\hat m_t}{\sqrt{\hat v_t}+\varepsilon}Use the supplied gradients in order. Initialize the stated memories to zero. Epsilon is set to zero only for this exercise because every denominator is nonzero. Keep calculator precision until the final result.
Step 1: Iteration 1 with supplied gradient 2.
First calculate the signed-gradient mean m and squared-gradient mean v.
LaTeX: m_1=0.9(0)+0.1(2)=0.2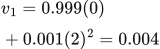 LaTeX:
v_1=0.999(0)+0.001(2)^2=0.004Correct each zero-initialized mean using this iteration number in the power.
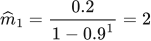 LaTeX:
\widehat m_1=\frac{0.2}{1-0.9^{1}}=2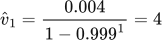 LaTeX:
\widehat v_1=\frac{0.004}{1-0.999^{1}}=4Divide the corrected direction by the corrected root, then subtract the scaled step.
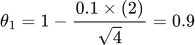 LaTeX:
\theta_1=1-\frac{0.1\times(2)}{\sqrt{4}}=0.9Step 2: Iteration 2 with supplied gradient 1.
First calculate the signed-gradient mean m and squared-gradient mean v.
LaTeX: m_2=0.9(0.2)+0.1(1)=0.28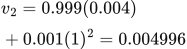 LaTeX:
v_2=0.999(0.004)+0.001(1)^2=0.004996Correct each zero-initialized mean using this iteration number in the power.
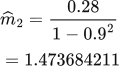 LaTeX:
\widehat m_2=\frac{0.28}{1-0.9^{2}}=1.473684211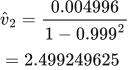 LaTeX:
\widehat v_2=\frac{0.004996}{1-0.999^{2}}=2.499249625Divide the corrected direction by the corrected root, then subtract the scaled step.
 LaTeX:
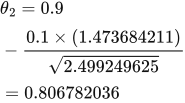
\theta_2=0.9-\frac{0.1\times(1.473684211)}{\sqrt{2.499249625}}=0.806782036Drill 29 Adam variation 2
Question
Question. θ₀ = -0.5, η = 0.1, supplied successive gradients = [-1, 2]. Use Adam for two updates, zero initial accumulators and ε = 0 for this hand calculation. Use β₁ = 0.9, β₂ = 0.999 and bias correction.
Answer — step by step
Given
Initial θ₀ = −0.5; η = 0.1.
Supplied gradients: [−1,2].
Initial accumulator(s) = 0; ε = 0 for this nonzero-denominator hand calculation.
β₁ = 0.9; β₂ = 0.999; use bias correction.
To find
Find every stored state needed by the method and the parameter after each of two updates.
Formula — which one and why
Adam with bias correction. Keep two states: one averages signed gradients, the other averages squared gradients. Correct their initial bias toward zero before combining them in the parameter update.
m = signed average; s (also written v) = squared average; β₁ and β₂ = retained fractions; t = iteration number. A hat marks a corrected value. Carry raw m and s into the next recurrence.
LaTeX: m_t=\beta_1m_{t-1}+(1-\beta_1)g_tLaTeX: s_t=\beta_2s_{t-1}+(1-\beta_2)g_t^2LaTeX: \hat m_t=\frac{m_t}{1-\beta_1^t}LaTeX: \hat s_t=\frac{s_t}{1-\beta_2^t}LaTeX: \theta_t=\theta_{t-1}-\frac{\eta\hat m_t}{\sqrt{\hat s_t}+\epsilon}Yaad rakhne ka cue: Direction memory + square memory; hats lagao, phir update.
Solution — step by step
Symbols and formulas used
θ is the parameter; η is the base learning rate; gₜ is the supplied gradient for update t. The gradients are already given, so no loss differentiation is needed here. Use ε = 0 only as specified in this exercise.
m remembers signed gradients; v remembers squared gradients. The hats mean bias-corrected values, compensating for memories starting at zero. They are not extra powers. Here β₁ = 0.9 and β₂ = 0.999.
LaTeX: m_t=\beta_1m_{t-1}+(1-\beta_1)g_tLaTeX: v_t=\beta_2v_{t-1}+(1-\beta_2)g_t^2LaTeX: \hat m_t=\frac{m_t}{1-\beta_1^t},\qquad \hat v_t=\frac{v_t}{1-\beta_2^t}LaTeX: \theta_t=\theta_{t-1}-\frac{\eta\hat m_t}{\sqrt{\hat v_t}+\varepsilon}Use the supplied gradients in order. Initialize the stated memories to zero. Epsilon is set to zero only for this exercise because every denominator is nonzero. Keep calculator precision until the final result.
Step 1: Iteration 1 with supplied gradient -1.
First calculate the signed-gradient mean m and squared-gradient mean v.
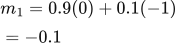 LaTeX:
m_1=0.9(0)+0.1(-1)=-0.1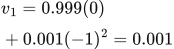 LaTeX:
v_1=0.999(0)+0.001(-1)^2=0.001Correct each zero-initialized mean using this iteration number in the power.
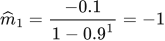 LaTeX:
\widehat m_1=\frac{-0.1}{1-0.9^{1}}=-1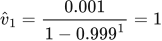 LaTeX:
\widehat v_1=\frac{0.001}{1-0.999^{1}}=1Divide the corrected direction by the corrected root, then subtract the scaled step.
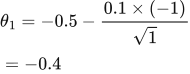 LaTeX:
\theta_1=-0.5-\frac{0.1\times(-1)}{\sqrt{1}}=-0.4Step 2: Iteration 2 with supplied gradient 2.
First calculate the signed-gradient mean m and squared-gradient mean v.
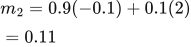 LaTeX:
m_2=0.9(-0.1)+0.1(2)=0.11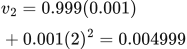 LaTeX:
v_2=0.999(0.001)+0.001(2)^2=0.004999Correct each zero-initialized mean using this iteration number in the power.
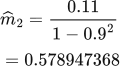 LaTeX:
\widehat m_2=\frac{0.11}{1-0.9^{2}}=0.578947368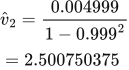 LaTeX:
\widehat v_2=\frac{0.004999}{1-0.999^{2}}=2.500750375Divide the corrected direction by the corrected root, then subtract the scaled step.
 LaTeX:
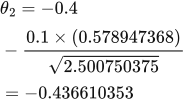
\theta_2=-0.4-\frac{0.1\times(0.578947368)}{\sqrt{2.500750375}}=-0.436610353