Deep Learning · TEE · formulas
Convolution parameter count
A filter has one learned weight for each spatial position in each input channel. Count the weights in one filter, add its one bias, then multiply by the number of filters. Sliding a filter to many positions reuses these weights; it does not create new parameters.
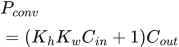 LaTeX:
P_{conv}=(K_hK_wC_{in}+1)C_{out}Output size and parameter count are different
Definition. Output shape specifies the size of a layer's computed tensor. Parameter count specifies the number of independent trainable coefficients. Spatial weight sharing allows a convolutional layer to produce many activations from comparatively few parameters.
Explanation and working
Question. A 7 × 7 × 3 input passes through two 3 × 3 filters, stride 2 and padding 1. Find output shape and parameter count, including bias.
Given
Input = 7 × 7 × 3; two 3 × 3 filters.
Stride = 2; padding = 1; include biases.
To find
Find the output shape and trainable parameter count.
Formula — which one and why
Convolution/pooling spatial size. Padding adds P positions at both ends. Subtract kernel width to find the last valid start, divide by stride, take the floor and include the initial placement with +1.
N = current height or width; K = kernel/window size; S = stride; P = padding per side. Apply separately to height and width; dilation is 1 here.
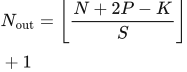 LaTeX:
N_{\mathrm{out}}=\left\lfloor\frac{N+2P-K}{S}\right\rfloor+1Yaad rakhne ka cue: Input + dono sides ki padding − kernel; stride se divide; floor + 1.
Convolution parameters. Every filter spans all input channels. Count its spatial coefficients across those channels, add one bias and multiply by the number of filters.
K_h,K_w = filter height/width; C_in = input channels; C_out = number of filters and output channels. Spatial output positions reuse these weights.
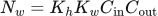 LaTeX:
N_w=K_hK_wC_{\mathrm{in}}C_{\mathrm{out}} LaTeX:
N_b=C_{\mathrm{out}}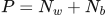 LaTeX:
P=N_w+N_bYaad rakhne ka cue: Filter area × input channels × filters; phir ek bias per filter.
Solution — step by step
Step 1 spatial size: padding adds two, giving 7 + 2 − 3 = 6. Divide by stride: 6 ÷ 2 = 3. Apply floor and add the first position: 3 + 1 = 4. There are two filters, so output is 4 × 4 × 2.
Step 2 parameters: one filter has 3 × 3 × 3 = 27 weights and one bias, giving 28. Two filters have 56 parameters. The 4 × 4 output positions reuse those weights; they do not create 16 new sets of parameters.
Model answer: shape, activations and parameters
Question
Question. Distinguish a CNN layer's output shape, number of output activations and number of trainable parameters. Explain the formulas used to calculate them.
Answer — step by step
Output shape tells how the produced values are arranged. The activation count tells how many values were produced for one input. Parameter count tells how many learned weights and biases define the layer. These are three different questions.
Spatial output shape
For an ordinary convolution with dilation 1:
LaTeX: N_{\mathrm{out}}=\left\lfloor\frac{N+2P-K}{S}\right\rfloor+1N is the incoming spatial size, P is padding on each side, K is kernel size and S is stride. Apply the rule independently to height and width. The number of output channels is the number of filters.
Output activations
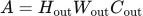 LaTeX:
A=H_{\mathrm{out}}W_{\mathrm{out}}C_{\mathrm{out}}This is the number of output values for one example, excluding any batch dimension.
Trainable parameters
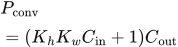 LaTeX:
P_{\mathrm{conv}}=(K_hK_wC_{\mathrm{in}}+1)C_{\mathrm{out}}Each filter spans every incoming channel. The +1 is one bias per filter. Remove it if biases are disabled. Spatial output dimensions do not appear here because filters share their weights across positions.
Small example
A 7 × 7 × 3 input, two 3 × 3 filters, stride 2 and padding 1 gives output 4 × 4 × 2. It contains 32 activations but has (3 × 3 × 3 + 1) × 2 = 56 parameters. These counts do not need to match. In a multilayer question, the current layer's output channels become the next convolution's input channels.
Faculty CNN table: shapes, activations and 62958 parameters
Question. A CNN receives a 32 × 32 × 3 image. It uses Conv1: eight 5 × 5 filters, stride 1, no padding; Pool1: 2 × 2, stride 2; Conv2: sixteen 5 × 5 filters, stride 1, no padding; Pool2: 2 × 2, stride 2; flatten; dense 120; dense 84; dense 10 followed by softmax. Include one bias per filter or receiving dense neuron. Find every output shape, activation count and trainable-parameter count. (Practice: 10 marks)
Given
Input = 32 × 32 × 3. Both convolutions are ordinary full-channel convolutions. Pooling has no padding. Dense widths are 120, 84 and 10. No batch-normalization layer is present in this particular question.
To find
Output shape and number of output values for each layer, its trainable parameters, and the total parameters.
Formula — which one and why
Use the spatial-size formula for each convolution/pool. Use one full-depth kernel plus one bias per convolutional filter. Flattening counts all remaining values before the first dense layer. Each dense neuron then receives one weight per input plus one bias.
LaTeX: N_{\mathrm{out}}=\left\lfloor\frac{N+2P-K}{S}\right\rfloor+1LaTeX: A=H_{\mathrm{out}}W_{\mathrm{out}}C_{\mathrm{out}}LaTeX: P_{\mathrm{conv}}=(K_hK_wC_{\mathrm{in}}+1)C_{\mathrm{out}}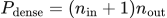 LaTeX:
P_{\mathrm{dense}}=(n_{\mathrm{in}}+1)n_{\mathrm{out}}A counts produced activations. P_conv and P_dense count independent learned coefficients. They are not the same quantity. Pooling, flattening and softmax itself add zero learned parameters here.
Solution — step by step
Step 1: input. Shape = 32 × 32 × 3. Values = 32×32×3 = 3,072. Trainable parameters = 0.
Step 2: Conv1 spatial size. (32−5)/1 +1 = 28. Eight filters give shape 28 × 28 × 8. Activations = 28×28×8 = 6,272.
Step 3: Conv1 parameters. One filter contains 5×5×3 = 75 weights. Add one bias: 76. Multiply by eight filters: 76×8 = 608.
Step 4: Pool1. (28−2)/2 +1 = 14. Shape = 14 × 14 × 8. Activations = 14×14×8 = 1,568. Parameters = 0; channel count remains eight.
Step 5: Conv2 spatial size. (14−5)/1 +1 = 10. Sixteen filters give shape 10 × 10 × 16. Activations = 1,600.
Step 6: Conv2 parameters. Its input has eight channels. Each filter has 5×5×8 = 200 weights, then one bias. Total = 201×16 = 3,216.
Step 7: Pool2 and flatten. (10−2)/2 +1 = 5. Pool shape = 5 × 5 × 16. Flattened length = 5×5×16 = 400. Neither operation adds parameters.
Step 8: dense 120. Weights = 400×120 = 48,000. Biases = 120. Parameters = 48,120. Output contains 120 activations.
Step 9: dense 84. Weights = 120×84 = 10,080. Biases = 84. Parameters = 10,164. Output contains 84 activations.
Step 10: dense 10 and softmax. Weights = 84×10 = 840. Biases = 10. Dense parameters = 850. Softmax converts the ten logits into ten probabilities and adds zero parameters. A table naming the combined classifier row “Softmax” attributes these 850 parameters to its preceding dense transformation.
Step 11: add only the trainable counts. 608+3,216 = 3,824; +48,120 = 51,944; +10,164 = 62,108; +850 = 62,958.
| Layer | Output shape | Activations | Parameters |
|---|---|---|---|
| Input | 32 × 32 × 3 | 3,072 | 0 |
| Conv1 | 28 × 28 × 8 | 6,272 | 608 |
| Pool1 | 14 × 14 × 8 | 1,568 | 0 |
| Conv2 | 10 × 10 × 16 | 1,600 | 3,216 |
| Pool2 / flatten | 5 × 5 × 16 / 400 | 400 | 0 |
| Dense 120 | 120 | 120 | 48,120 |
| Dense 84 | 84 | 84 | 10,164 |
| Dense 10 → softmax | 10 | 10 | 850 + 0 |
Final answer: The network has 62,958 trainable parameters. This is the specified classroom CNN, not a universal parameter total for every LeNet-like network.
Yaad rakho: Shape aage carry karo; weights aur activations ko alag columns mein rakho.
Parameters are different from activation values
Definition. Parameters are learned coefficients shared across evaluations. Activations are input-dependent values computed during a forward pass. The number of activation values therefore differs from the number of trainable parameters.
Explanation and working
An activation is a number produced for a particular input. A parameter is a learned number reused across inputs. A 100 × 100 feature map can be produced by a filter with only a few weights.
LaTeX: P_{\mathrm{conv}}=(K_hK_wC_{\mathrm{in}}+1)C_{\mathrm{out}}The +1 is one bias per filter. If bias is explicitly disabled, remove it. Height and width of the image do not enter the parameter formula; they enter the number of output activations and the amount of computation.
One filter, then all filters
Question. A 3 × 3 convolution receives 3 input channels and has 16 filters, each with one bias. Find its trainable parameters and output-channel count.
Given
Kernel = 3 × 3; input channels = 3; filters = 16; one bias per filter.
To find
Weights, biases, total trainable parameters and output channels.
Formula — which one and why
Each filter spans every input channel and owns one bias. Spatial reuse does not create extra weights.
Kₕ,Kw are kernel dimensions; Cᵢₙ is input depth; Cₒᵤₜ is the number of filters.
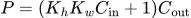 LaTeX:
P=(K_hK_wC_{\mathrm{in}}+1)C_{\mathrm{out}}Yaad rakhne ka cue: Ek filter ka count banao, phir filters se multiply.
Solution — step by step
Step 1: count weights in one filter.
 LaTeX:
3(3)(3)=27Step 2: include its one bias.
 LaTeX:
27+1=28Step 3: count all weights.
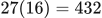 LaTeX:
27(16)=432Step 4: count all biases.
 LaTeX:
1(16)=16Step 5: add and state channel count.
 LaTeX:
P=432+16=448Each filter produces one channel, so output channels = 16.
Final answer: 432 weights + 16 biases = 448 trainable parameters; 16 output channels.
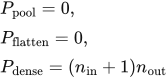 LaTeX:
P_{\mathrm{pool}}=0,\quad P_{\mathrm{flatten}}=0,\quad P_{\mathrm{dense}}=(n_{\mathrm{in}}+1)n_{\mathrm{out}}Flatten rearranges H × W × C activation values into one vector of length HWC. It does not learn anything. A following dense layer connects to every one of those values.
Drill 37 Complete small CNN
Question
Question. Input 10 × 10 × 1 → Conv 3 × 3,4 filters, stride 1, valid → Pool 2 stride 2 → Flatten → Dense 3. Find all shapes and parameters.
Answer — step by step
Given
Input = 10 × 10 × 1.
Conv: 3 × 3, 4 filters, stride 1, valid padding.
Pool: 2 × 2, stride 2; then flatten and dense layer with 3 outputs.
Include one bias per filter/dense neuron.
To find
Find all output shapes, layer parameter counts and their sum.
Formula — which one and why
Complete CNN calculation. Carry each output shape into the next layer. Convolution changes spatial size and channel count; pooling changes spatial size; flattening converts all activations into dense-layer inputs.
H,W,C = feature-map height, width and channels; K = kernel size; S = stride; P_pad = padding. One bias is assumed for each learned filter or dense neuron unless specified otherwise.
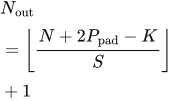 LaTeX:
N_{\mathrm{out}}=\left\lfloor\frac{N+2P_{\mathrm{pad}}-K}{S}\right\rfloor+1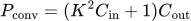 LaTeX:
P_{\mathrm{conv}}=(K^2C_{\mathrm{in}}+1)C_{\mathrm{out}}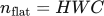 LaTeX:
n_{\mathrm{flat}}=HWCLaTeX: P_{\mathrm{dense}}=(n_{\mathrm{in}}+1)n_{\mathrm{out}}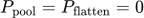 LaTeX:
P_{\mathrm{pool}}=P_{\mathrm{flatten}}=0Yaad rakhne ka cue: Ek layer ka output, next layer ka input; shape aur parameters alag count.
Solution — step by step
Formulas and assumptions
“Valid” means zero padding. The convolution and dense layers each have one bias per receiving filter or neuron. Pooling and flattening have no learned parameters.
LaTeX: N_{\mathrm{out}}=\left\lfloor\frac{N+2P-K}{S}\right\rfloor+1LaTeX: P_{\mathrm{conv}}=(K^2C_{\mathrm{in}}+1)C_{\mathrm{out}}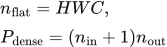 LaTeX:
n_{\mathrm{flat}}=HWC,\qquad P_{\mathrm{dense}}=(n_{\mathrm{in}}+1)n_{\mathrm{out}}Step 1: convolution shape
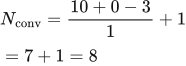 LaTeX:
N_{\mathrm{conv}}=\frac{10+0-3}{1}+1=7+1=8Four filters produce four channels: 8 × 8 × 4.
Step 2: convolution parameters
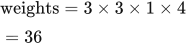 LaTeX:
\text{weights}=3\times3\times1\times4=36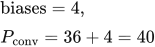 LaTeX:
\text{biases}=4,\qquad P_{\mathrm{conv}}=36+4=40Step 3: pooling shape
Pooling now receives size 8, not the original size 10.
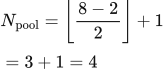 LaTeX:
N_{\mathrm{pool}}=\left\lfloor\frac{8-2}{2}\right\rfloor+1=3+1=4Channels remain 4: 4 × 4 × 4. Pooling parameters = 0.
Step 4: flatten
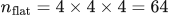 LaTeX:
n_{\mathrm{flat}}=4\times4\times4=64Flatten creates a vector of 64 numbers. It rearranges values, so its parameter count is 0.
Step 5: dense layer with 3 outputs
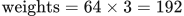 LaTeX:
\text{weights}=64\times3=192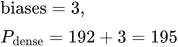 LaTeX:
\text{biases}=3,\qquad P_{\mathrm{dense}}=192+3=195Step 6: add learned parameters
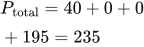 LaTeX:
P_{\mathrm{total}}=40+0+0+195=235Final answer: shapes 8 × 8 × 4 → 4 × 4 × 4 → 64 → 3; total 235 parameters.