Deep Learning · TEE · formulas
Vanilla RNN
A recurrent state uses two sources: the current input and the previous hidden state. Transform each with its own weight, add the contributions and bias, and apply tanh. The activated state—not its raw sum—is carried into the next time step.
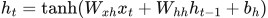 LaTeX:
h_t=\tanh(W_{xh}x_t+W_{hh}h_{t-1}+b_h)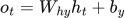 LaTeX:
o_t=W_{hy}h_t+b_yThe vanilla RNN equations from scratch
Definition. A vanilla recurrent neural network updates a hidden state from the current sequence input and the previous hidden state, using the same trainable parameters at every time step. An output transformation converts that state into the task's prediction.
Hidden-state and output equations
For a tanh recurrent layer:
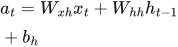 LaTeX:
a_t=W_{xh}x_t+W_{hh}h_{t-1}+b_h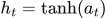 LaTeX:
h_t=\tanh(a_t)aₜ is the preactivation and hₜ is the activated hidden state. Wₓₕ transforms the new input; Wₕₕ transforms the previous state. Both contributions have the same hidden dimension before they are added. bₕ has one component per hidden unit.
For classification at time t, an output layer can produce logits and probabilities:
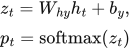 LaTeX:
z_t=W_{hy}h_t+b_y,\qquad p_t=\operatorname{softmax}(z_t)A regression output may instead be linear. A question asking only for hidden states does not require an output-layer prediction, and such a prediction cannot be calculated without the output transformation.
Complete numerical: two recurrent time steps
Question. Let h₀ = 0, Wₓₕ = 0.5, Wₕₕ = 0.2, bₕ = 0, x₁ = 1 and x₂ = 2. Calculate h₁ and h₂ using tanh activation.
Given
h₀ = 0; Wxh = 0.5; Whh = 0.2; b = 0.
x₁ = 1; x₂ = 2; activation = tanh.
To find
Find h₁ and h₂ in order.
Formula — which one and why
Recurrent forward pass. At each time step, combine the current input contribution with the previous activated hidden state, add the bias and apply tanh. The same weights are reused at every time step.
x_t = current input; h_(t−1) = previous hidden state; W_xh = input weights; W_hh = recurrent weights; b = bias.
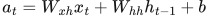 LaTeX:
a_t=W_{xh}x_t+W_{hh}h_{t-1}+bLaTeX: h_t=\tanh(a_t)Yaad rakhne ka cue: Naya input + pichhla activated state; phir activation.
Solution — step by step
Step 1: Time step 1 — calculate the preactivation.
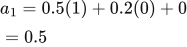 LaTeX:
a_1=0.5(1)+0.2(0)+0=0.5Apply the recurrent activation.
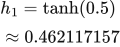 LaTeX:
h_1=\tanh(0.5)\approx0.462117157This activated value, not a₁ = 0.5, is passed to the next time step.
Step 2: Time step 2 — combine the new input and previous state.
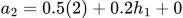 LaTeX:
a_2=0.5(2)+0.2h_1+0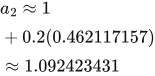 LaTeX:
a_2\approx1+0.2(0.462117157)\approx1.092423431Apply tanh to the complete new preactivation.
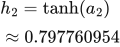 LaTeX:
h_2=\tanh(a_2)\approx0.797760954| Time step | Current input | Previous state | Preactivation | New state |
|---|---|---|---|---|
| 1 | 1 | 0 | 0.5 | 0.462117157 |
| 2 | 2 | 0.462117157 | 1.092423431 | 0.797760954 |
Final answer: h₁ ≈ 0.462117 and h₂ ≈ 0.797761. Keep the full calculator value of h₁ while computing the second step. Although a₂ is greater than 1, h₂ is between −1 and 1 because tanh is applied after the affine sum. Both time steps use the same weights; this calculation contains no parameter update.
A complete vector RNN calculation
Question from R26 Q5a. xₜ = [0,1], hₜ₋₁ = [0,1], no bias is supplied, Wxh is shown below, Whh is shown below. Use tanh and rows as receiving neurons.
Given
Input x = [0,1]ᵀ; previous h = [0,1]ᵀ.
Wxh =  LaTeX:
\begin{bmatrix}0.6 & 0.4\\0.3 & 0.7\end{bmatrix}.
Whh =  LaTeX:
\begin{bmatrix}0.5 & 0.3\\0.2 & 0.4\end{bmatrix}; bias = 0.
Apply tanh separately to the two sums.
To find
Find the new two-component hidden state; output-layer parameters are not supplied.
Formula — which one and why
Recurrent forward pass. At each time step, combine the current input contribution with the previous activated hidden state, add the bias and apply tanh. The same weights are reused at every time step.
x_t = current input; h_(t−1) = previous hidden state; W_xh = input weights; W_hh = recurrent weights; b = bias.
LaTeX: a_t=W_{xh}x_t+W_{hh}h_{t-1}+bLaTeX: h_t=\tanh(a_t)Yaad rakhne ka cue: Naya input + pichhla activated state; phir activation.
Solution — step by step
Step 1 new input: Wxh x = [0.6 × 0 + 0.4 × 1, 0.3 × 0 + 0.7 × 1] = [0.4,0.7].
Step 2 old memory: Whh hprevious = [0.5 × 0 + 0.3 × 1, 0.2 × 0 + 0.4 × 1] = [0.3,0.4].
Step 3 add: a = [0.4+0.3, 0.7+0.4] = [0.7,1.1].
Step 4 activate each element: h = [tanh(0.7), tanh(1.1)] = [0.604368,0.800499]. An output-layer prediction cannot be numerically calculated without its weights and bias.
Drill 41 Two RNN steps
Question
Question. h₀ = 0, Wxh = 0.5, Whh = 0.2, b = 0, x₁ = 1, x₂ = 2, tanh activation. Find h₁, h₂.
Answer — step by step
Given
Initial h₀ = 0; input weight Wxh = 0.5; recurrent weight Whh = 0.2; b = 0.
Inputs: x₁ = 1, x₂ = 2; activation: tanh.
To find
Calculate h₁, then use it to calculate h₂.
Formula — which one and why
Recurrent forward pass. At each time step, combine the current input contribution with the previous activated hidden state, add the bias and apply tanh. The same weights are reused at every time step.
x_t = current input; h_(t−1) = previous hidden state; W_xh = input weights; W_hh = recurrent weights; b = bias.
LaTeX: a_t=W_{xh}x_t+W_{hh}h_{t-1}+bLaTeX: h_t=\tanh(a_t)Yaad rakhne ka cue: Naya input + pichhla activated state; phir activation.
Solution — step by step
Meaning and formulas
At time t, the RNN combines the current input xₜ and the previous hidden state hₜ₋₁. The same two weights are reused at both times.
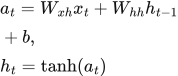 LaTeX:
a_t=W_{xh}x_t+W_{hh}h_{t-1}+b,\qquad h_t=\tanh(a_t)The raw sum a is not the hidden state. Tanh converts that sum into the state that is carried forward.
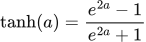 LaTeX:
\tanh(a)=\frac{e^{2a}-1}{e^{2a}+1}Step 1: calculate the first raw sum
LaTeX: a_1=0.5(1)+0.2(0)+0=0.5Step 2: activate it to obtain the first state
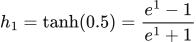 LaTeX:
h_1=\tanh(0.5)=\frac{e^1-1}{e^1+1}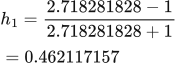 LaTeX:
h_1=\frac{2.718281828-1}{2.718281828+1}=0.462117157Step 3: use that state in the second raw sum
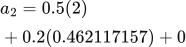 LaTeX:
a_2=0.5(2)+0.2(0.462117157)+0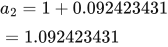 LaTeX:
a_2=1+0.092423431=1.092423431Step 4: activate the second sum
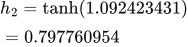 LaTeX:
h_2=\tanh(1.092423431)=0.797760954Final answer: h₁ ≈ 0.462117157; h₂ ≈ 0.797760954. Pass h₁ to the next step, not the unactivated value 0.5.