Deep Learning · TEE · formulas
Perceptron update
The perceptron uses a threshold to choose a class and an error-based learning rule to change weights. Its threshold convention must be stated, especially at zero. This discrete learning rule is different from sigmoid backpropagation.
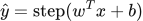 LaTeX:
\widehat y=\operatorname{step}(w^Tx+b)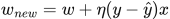 LaTeX:
w_{new}=w+\eta(y-\widehat y)x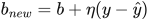 LaTeX:
b_{new}=b+\eta(y-\widehat y)Perceptrons and the threshold
A perceptron is a simple neuron used for classification with a threshold decision. If a question says output 1 for z ≥ 0 and 0 otherwise, then z = 0 gives 1. If it says output 1 for z > 0 and 0 otherwise, then z = 0 gives 0. That single equality sign can change an entire training table.
Question. Implement binary AND with w₁ = w₂ = 0.6, b = −0.8 and output 1 when z ≥ 0.
Given
w₁ = w₂ = 0.6; bias b = −0.8.
Binary inputs; output 1 when z ≥ 0.
To find
Calculate the output for 00,01,10,11 and show that the result is AND.
Formula — which one and why
Threshold logic. Compute the weighted sum for every binary input combination and apply the threshold rule exactly. Hidden neurons can provide separate threshold decisions before the output combines them.
step(z) returns 1 at or above zero unless the question specifies a strict inequality; otherwise it returns 0.
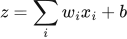 LaTeX:
z=\sum_iw_ix_i+b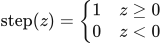 LaTeX:
\operatorname{step}(z)=\begin{cases}1&z\ge0\\0&z<0\end{cases}Yaad rakhne ka cue: Har input row ka sum nikalo, phir threshold lagao.
Solution — step by step
Input (0, 0)
Step 1: multiply input 1 by its weight.
 LaTeX:
0.6(0)=0Step 2: multiply input 2 by its weight.
LaTeX: 0.6(0)=0Step 3: add the two products.
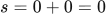 LaTeX:
s=0+0=0Step 4: add the bias once.
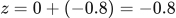 LaTeX:
z=0+(-0.8)=-0.8Step 5: apply the stated threshold.
z = -0.8; output = 0 because output is 1 exactly when z ≥ 0.
Input (0, 1)
Step 1: multiply input 1 by its weight.
LaTeX: 0.6(0)=0Step 2: multiply input 2 by its weight.
 LaTeX:
0.6(1)=0.6Step 3: add the two products.
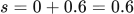 LaTeX:
s=0+0.6=0.6Step 4: add the bias once.
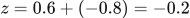 LaTeX:
z=0.6+(-0.8)=-0.2Step 5: apply the stated threshold.
z = -0.2; output = 0 because output is 1 exactly when z ≥ 0.
Input (1, 0)
Step 1: multiply input 1 by its weight.
LaTeX: 0.6(1)=0.6Step 2: multiply input 2 by its weight.
LaTeX: 0.6(0)=0Step 3: add the two products.
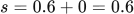 LaTeX:
s=0.6+0=0.6Step 4: add the bias once.
LaTeX: z=0.6+(-0.8)=-0.2Step 5: apply the stated threshold.
z = -0.2; output = 0 because output is 1 exactly when z ≥ 0.
Input (1, 1)
Step 1: multiply input 1 by its weight.
LaTeX: 0.6(1)=0.6Step 2: multiply input 2 by its weight.
LaTeX: 0.6(1)=0.6Step 3: add the two products.
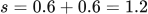 LaTeX:
s=0.6+0.6=1.2Step 4: add the bias once.
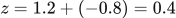 LaTeX:
z=1.2+(-0.8)=0.4Step 5: apply the stated threshold.
z = 0.4; output = 1 because output is 1 exactly when z ≥ 0.
Final answer: outputs are [0, 0, 0, 1] for inputs 00, 01, 10, 11: exactly AND.
Summary of the four cases
| Inputs | Full net calculation | Net z | Output | AND target |
|---|---|---|---|---|
| 0, 0 | 0.6(0) + 0.6(0) − 0.8 | −0.8 | 0 | 0 |
| 0, 1 | 0.6(0) + 0.6(1) − 0.8 | −0.2 | 0 | 0 |
| 1, 0 | 0.6(1) + 0.6(0) − 0.8 | −0.2 | 0 | 0 |
| 1, 1 | 0.6(1) + 0.6(1) − 0.8 | 0.4 | 1 | 1 |
The neuron fires only when both inputs are 1. No weight update was requested, so this is a forward evaluation, not a training problem.
For binary targets, a common learning rule is w ← w + η(t − a)x and b ← b + η(t − a). For bipolar targets −1 and +1, the class notes use a different rule: on a mismatch, w ← w + η tx and b ← b + ηt; otherwise keep them. The notes give output 0 at zero threshold, +1 above it and −1 below it. Never combine the activation from one convention with an unexplained update from another.
Training table routine: copy current weights → calculate z → apply the stated threshold → compare output with target → compute every weight change → update bias → carry new values to the next row. Reset nothing between rows or epochs unless instructed.
Binary perceptron: target 1
Question. A binary perceptron has x = [1,2], weights [-0.2, 0.1], bias 0 and target 1. Use output 1 for net ≥ 0 and learning rate 0.1. Perform one update.
Given
x = [1,2]; w = [-0.2, 0.1]; b = 0; target = 1; η = 0.1.
To find
Net, threshold output, correction and new weights/bias.
Formula — which one and why
This binary learning rule uses target minus output. Carry the same correction into every input weight and the bias.
t is target; o is threshold output; Δ means the amount added to the current parameter.
LaTeX: z=\sum_iw_ix_i+b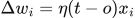 LaTeX:
\Delta w_i=\eta(t-o)x_i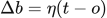 LaTeX:
\Delta b=\eta(t-o)Yaad rakhne ka cue: Target minus output; correct prediction ho toh correction zero.
Solution — step by step
Step 1: calculate the net input.
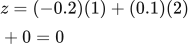 LaTeX:
z=(-0.2)(1)+(0.1)(2)+0=0Step 2: apply the threshold.
Net = 0; output = 1 under the stated ≥ 0 rule.
Step 3: calculate the correction.
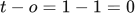 LaTeX:
t-o=1-1=0Step 4: update weight 1.
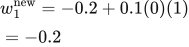 LaTeX:
w_1^{\mathrm{new}}=-0.2+0.1(0)(1)=-0.2Step 5: update weight 2.
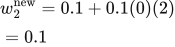 LaTeX:
w_2^{\mathrm{new}}=0.1+0.1(0)(2)=0.1Step 6: update the bias.
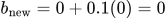 LaTeX:
b_{\mathrm{new}}=0+0.1(0)=0Final answer: New weights = [-0.2,0.1]; new bias = 0.
Binary perceptron: target 0
Question. A binary perceptron has x = [1,2], weights [0.2, 0.1], bias 0 and target 0. Use output 1 for net ≥ 0 and learning rate 0.1. Perform one update.
Given
x = [1,2]; w = [0.2, 0.1]; b = 0; target = 0; η = 0.1.
To find
Net, threshold output, correction and new weights/bias.
Formula — which one and why
This binary learning rule uses target minus output. Carry the same correction into every input weight and the bias.
t is target; o is threshold output; Δ means the amount added to the current parameter.
LaTeX: z=\sum_iw_ix_i+bLaTeX: \Delta w_i=\eta(t-o)x_iLaTeX: \Delta b=\eta(t-o)Yaad rakhne ka cue: Target minus output; correct prediction ho toh correction zero.
Solution — step by step
Step 1: calculate the net input.
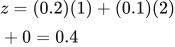 LaTeX:
z=(0.2)(1)+(0.1)(2)+0=0.4Step 2: apply the threshold.
Net = 0.4; output = 1 under the stated ≥ 0 rule.
Step 3: calculate the correction.
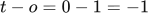 LaTeX:
t-o=0-1=-1Step 4: update weight 1.
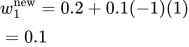 LaTeX:
w_1^{\mathrm{new}}=0.2+0.1(-1)(1)=0.1Step 5: update weight 2.
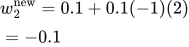 LaTeX:
w_2^{\mathrm{new}}=0.1+0.1(-1)(2)=-0.1Step 6: update the bias.
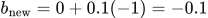 LaTeX:
b_{\mathrm{new}}=0+0.1(-1)=-0.1Final answer: New weights = [0.1,-0.1]; new bias = -0.1.
Drill 11 One perceptron learning update
Question
Question. Binary perceptron, w = [0,0], b = 0, x = [1,1], target 1, η = 0.5. Use output 1 if z>0 else 0. Perform one update.
Answer — step by step
Given
w = [0,0]; b = 0; x = [1,1]; target t = 1.
Learning rate η = 0.5.
Output 1 only when z > 0; otherwise output 0.
To find
Perform one update and report new weights and bias.
Formula — which one and why
Perceptron learning rule. Evaluate the stated threshold, compare the predicted class with its target, then correct weights and bias. The next sample uses the newly updated parameters.
t = target; o = thresholded output; η = learning rate; xᵢ = input i. Binary and bipolar output conventions must follow the question.
LaTeX: z=\sum_iw_ix_i+b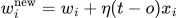 LaTeX:
w_i^{\mathrm{new}}=w_i+\eta(t-o)x_i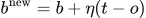 LaTeX:
b^{\mathrm{new}}=b+\eta(t-o)Yaad rakhne ka cue: Prediction nikalo; target−prediction se correction nikalo.
Solution — step by step
Meaning and formula
A perceptron first computes a weighted sum z and then applies the exact threshold rule in the question. This question uses strictly greater than zero, so z = 0 produces output 0.
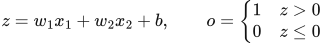 LaTeX:
z=w_1x_1+w_2x_2+b,\qquad o=\begin{cases}1&z>0\\0&z\le0\end{cases}The perceptron learning rule uses target minus output, written e below. This is a discrete perceptron rule, not the sigmoid backpropagation derivative.
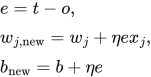 LaTeX:
e=t-o,\qquad w_{j,\mathrm{new}}=w_j+\eta e x_j,\qquad b_{\mathrm{new}}=b+\eta eStep 1: obtain the old output
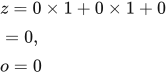 LaTeX:
z=0\times1+0\times1+0=0,\qquad o=0Step 2: compare it with the target
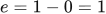 LaTeX:
e=1-0=1Step 3: update each weight separately
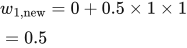 LaTeX:
w_{1,\mathrm{new}}=0+0.5\times1\times1=0.5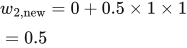 LaTeX:
w_{2,\mathrm{new}}=0+0.5\times1\times1=0.5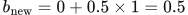 LaTeX:
b_{\mathrm{new}}=0+0.5\times1=0.5Step 4: interpret the updated prediction
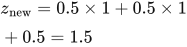 LaTeX:
z_{\mathrm{new}}=0.5\times1+0.5\times1+0.5=1.5Since 1.5 > 0, the new output is 1. Final parameters: w = [0.5, 0.5], b = 0.5.