Deep Learning · TEE · section
Teams photos full sigmoid example
Current MT1 and the two teacher backprop examples
The three photographs show this 2 → 2 → 2 network and its chain rule. The photo label for w₃ is read as 0.25, consistent with the visible output/error values and the matching worked example in S05. Learning rate is not legible/specified in these photos; η = 0.5 below is an explicit practice assumption.
Question. Input x = [0.05, 0.1]. Each row below lists the incoming weights of one receiving neuron. W₁ =  LaTeX:
\begin{bmatrix}0.15 & 0.2\\0.25 & 0.3\end{bmatrix}; b₁ = [0.35, 0.35]; W₂ =  LaTeX:
\begin{bmatrix}0.4 & 0.45\\0.5 & 0.55\end{bmatrix}; b₂ = [0.6, 0.6]. Hidden and output activations are sigmoid. Target y = [0.01, 0.99]. Learning rate η = 0.5. Compute all outputs, total half squared loss, all eight weight gradients and one simultaneous weight update. Map weights in order: w₁ = x₁ → h₁, w₂ = x₂ → h₁, w₃ = x₁ → h₂, w₄ = x₂ → h₂; w₅ = h₁ → o₁, w₆ = h₂ → o₁, w₇ = h₁ → o₂, w₈ = h₂ → o₂.
Given
Input x = [0.05, 0.1].
W₁ = LaTeX: \begin{bmatrix}0.15 & 0.2\\0.25 & 0.3\end{bmatrix}.
b₁ = [0.35, 0.35].
W₂ = LaTeX: \begin{bmatrix}0.4 & 0.45\\0.5 & 0.55\end{bmatrix}.
b₂ = [0.6, 0.6].
Hidden and output activations are sigmoid.
Target y = [0.01, 0.99].
Learning rate η = 0.5.
To find
Find all preactivations, hidden activations and final outputs. Calculate the half summed squared loss and its output derivatives. Find the sigmoid output and, if requested, its derivative. Find the requested deltas and parameter gradients, then update the specified parameters.
Formula — which one and why
Forward propagation. Evaluate one layer completely before supplying its activated outputs to the next layer. Each layer has its own weights and biases.
x = input vector; h = hidden outputs; W₁,b₁ = hidden parameters; W₂,b₂ = output parameters; f₁,f₂ = the stated activations.
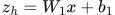 LaTeX:
z_h=W_1x+b_1 LaTeX:
h=f_1(z_h)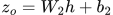 LaTeX:
z_o=W_2h+b_2 LaTeX:
o=f_2(z_o)Yaad rakhne ka cue: Pehli layer ka activated output hi agli layer ka input hai.
Half summed squared loss. This loss convention takes one-half of the sum of squared prediction errors. Use it when the question specifies it, or explicitly state it as an assumption when the paper omits the loss. Differentiating cancels the factor one-half against the square derivative.
oⱼ = output j; yⱼ = target j; L = half summed squared loss under the stated or explicitly assumed convention.
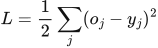 LaTeX:
L=\frac12\sum_j(o_j-y_j)^2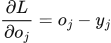 LaTeX:
\frac{\partial L}{\partial o_j}=o_j-y_jYaad rakhne ka cue: Half aur square ka 2 cancel: output derivative = prediction − target.
Sigmoid and its slope. Use sigmoid when the neuron is specified to squash its preactivation into (0,1). Once its output is known, its derivative needs only output × (1−output).
z = preactivation; p = sigmoid output; e is the exponential base, not a prediction error in this formula.
 LaTeX:
p=\frac{1}{1+e^{-z}}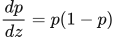 LaTeX:
\frac{dp}{dz}=p(1-p)Yaad rakhne ka cue: Sigmoid output p; uska slope p × (1−p).
Backpropagation. The loss tells us how each output must change. Multiply by that neuron’s activation slope to obtain its delta. A weight gradient is receiving delta × sending value. Hidden deltas must include every outgoing path.
δ (delta) = derivative of loss with respect to a neuron’s preactivation; f′ = activation derivative; aᵢ = sending activation; Wⱼᵢ = connection weight. Use the exact loss scaling in the question.
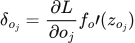 LaTeX:
\delta_{o_j}=\frac{\partial L}{\partial o_j}f_o\prime(z_{o_j})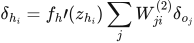 LaTeX:
\delta_{h_i}=f_h\prime(z_{h_i})\sum_jW_{ji}^{(2)}\delta_{o_j}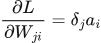 LaTeX:
\frac{\partial L}{\partial W_{ji}}=\delta_ja_i LaTeX:
\frac{\partial L}{\partial b_j}=\delta_j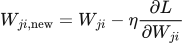 LaTeX:
W_{ji,\mathrm{new}}=W_{ji}-\eta\frac{\partial L}{\partial W_{ji}}Yaad rakhne ka cue: Receiving delta × sending value = us connection ka gradient.
Solution — step by step
Step 1 map the arrows. Each row of W₁ receives all inputs; each row of W₂ receives all hidden outputs. Bias is added once per receiving neuron. All gradients below use the OLD weights from this same forward pass.
Hidden neuron 1:
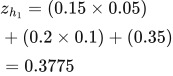 LaTeX:
z_{h_1} = (0.15 \times 0.05) + (0.2 \times 0.1) + (0.35) = 0.3775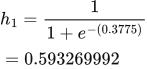 LaTeX:
h_{1}=\frac{1}{1+e^{-(0.3775)}}=0.593269992Hidden neuron 2:
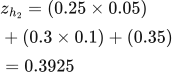 LaTeX:
z_{h_2} = (0.25 \times 0.05) + (0.3 \times 0.1) + (0.35) = 0.3925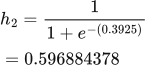 LaTeX:
h_{2}=\frac{1}{1+e^{-(0.3925)}}=0.596884378Output neuron 1:
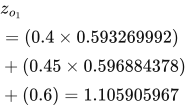 LaTeX:
z_{o_1} = (0.4 \times 0.593269992) + (0.45 \times 0.596884378) + (0.6) = 1.105905967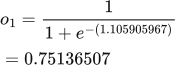 LaTeX:
o_{1}=\frac{1}{1+e^{-(1.105905967)}}=0.75136507Output neuron 2:
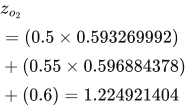 LaTeX:
z_{o_2} = (0.5 \times 0.593269992) + (0.55 \times 0.596884378) + (0.6) = 1.224921404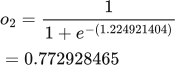 LaTeX:
o_{2}=\frac{1}{1+e^{-(1.224921404)}}=0.772928465Step 2 loss convention. The photos explicitly use ½(t₁−o₁)² + ½(t₂−o₂)². With exactly two output components, this equals their mean squared error, 0.298371109. The unhalved sum is 0.596742218.
Prediction minus target = [0.74136507, -0.217071535]. Squared errors = [0.549622166, 0.047120051]. Half-sum squared loss = 0.298371109; mean squared error = 0.298371109. These are different unless the number of output components makes the scale coincide.
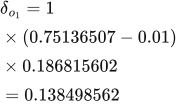
Output delta 1:
 LaTeX:
\delta_{o_1} = 1 \times (0.75136507-0.01) \times 0.186815602 = 0.138498562The derivative is o(1−o).
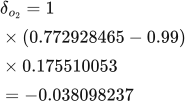
Output delta 2:
 LaTeX:
\delta_{o_2} = 1 \times (0.772928465-0.99) \times 0.175510053 = -0.038098237The derivative is o(1−o).
Step 3 output weights. Gradient = receiving delta × sending activation. An output bias gradient equals its delta.
h1 → o1:
Subtract η × gradient = 0.04108352. This weight decreases.
The sending value and receiving delta have different roles. All deltas still use the original forward-pass weights.
The receiving neuron supplies the delta; the sending neuron supplies its activation.
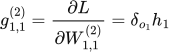 LaTeX:
g_{1,1}^{(2)}=\frac{\partial L}{\partial W^{(2)}_{1,1}}=\delta_{o_1}h_1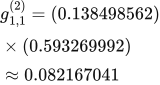 LaTeX:
g_{1,1}^{(2)}=(0.138498562)\times(0.593269992)\approx 0.082167041Apply the learning rate to this gradient and subtract the result from the old weight.
 LaTeX:
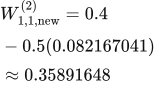
W^{(2)}_{1,1,\mathrm{new}}=0.4-0.5(0.082167041)\approx 0.35891648h2 → o1:
Subtract η × gradient = 0.041333814. This weight decreases.
The sending value and receiving delta have different roles. All deltas still use the original forward-pass weights.
The receiving neuron supplies the delta; the sending neuron supplies its activation.
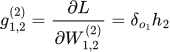 LaTeX:
g_{1,2}^{(2)}=\frac{\partial L}{\partial W^{(2)}_{1,2}}=\delta_{o_1}h_2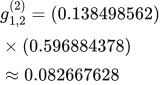 LaTeX:
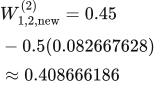
g_{1,2}^{(2)}=(0.138498562)\times(0.596884378)\approx 0.082667628Apply the learning rate to this gradient and subtract the result from the old weight.
 LaTeX:
W^{(2)}_{1,2,\mathrm{new}}=0.45-0.5(0.082667628)\approx 0.408666186h1 → o2:
Subtract η × gradient = −0.01130127. This weight increases.
The sending value and receiving delta have different roles. All deltas still use the original forward-pass weights.
The receiving neuron supplies the delta; the sending neuron supplies its activation.
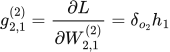 LaTeX:
g_{2,1}^{(2)}=\frac{\partial L}{\partial W^{(2)}_{2,1}}=\delta_{o_2}h_1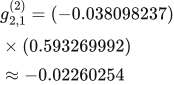 LaTeX:
g_{2,1}^{(2)}=(-0.038098237)\times(0.593269992)\approx -0.02260254Apply the learning rate to this gradient and subtract the result from the old weight.
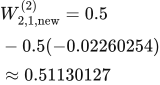 LaTeX:
W^{(2)}_{2,1,\mathrm{new}}=0.5-0.5(-0.02260254)\approx 0.51130127h2 → o2:
Subtract η × gradient = −0.011370121. This weight increases.
The sending value and receiving delta have different roles. All deltas still use the original forward-pass weights.
The receiving neuron supplies the delta; the sending neuron supplies its activation.
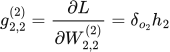 LaTeX:
g_{2,2}^{(2)}=\frac{\partial L}{\partial W^{(2)}_{2,2}}=\delta_{o_2}h_2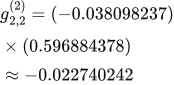 LaTeX:
g_{2,2}^{(2)}=(-0.038098237)\times(0.596884378)\approx -0.022740242Apply the learning rate to this gradient and subtract the result from the old weight.
 LaTeX:
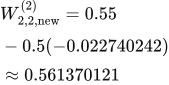
W^{(2)}_{2,2,\mathrm{new}}=0.55-0.5(-0.022740242)\approx 0.561370121Step 4 hidden deltas. A hidden unit can influence EVERY connected output, so add those paths BEFORE multiplying by the hidden activation derivative.
Hidden 1 downstream contribution:
Calculate each outgoing path using the old outgoing weight and that output's delta.
Multiply within each path. Add the resulting contributions at the shared hidden neuron.
Contribution from output 1.
 LaTeX:
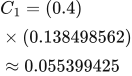
C_1=(0.4)\times(0.138498562)\approx 0.055399425Contribution from output 2.
 LaTeX:
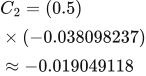
C_2=(0.5)\times(-0.038098237)\approx -0.019049118Accumulate the contributions, then apply the hidden activation derivative below.
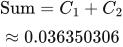 LaTeX:
\text{Sum}=C_1+C_2\approx 0.036350306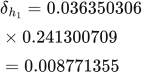 LaTeX:
\delta_{h_1} = 0.036350306 \times 0.241300709 = 0.008771355Hidden 2 downstream contribution:
Calculate each outgoing path using the old outgoing weight and that output's delta.
Multiply within each path. Add the resulting contributions at the shared hidden neuron.
Contribution from output 1.
 LaTeX:
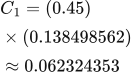
C_1=(0.45)\times(0.138498562)\approx 0.062324353Contribution from output 2.
 LaTeX:
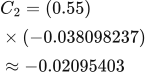
C_2=(0.55)\times(-0.038098237)\approx -0.02095403Accumulate the contributions, then apply the hidden activation derivative below.
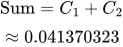 LaTeX:
\text{Sum}=C_1+C_2\approx 0.041370323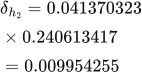 LaTeX:
\delta_{h_2} = 0.041370323 \times 0.240613417 = 0.009954255Step 5 input weights. Multiply the hidden delta by the corresponding raw input, not by the hidden output.
x1 → h1:
Subtract η × gradient = 0.000219284. This weight decreases.
The sending value and receiving delta have different roles. All deltas still use the original forward-pass weights.
The receiving neuron supplies the delta; the sending neuron supplies the input value.
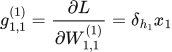 LaTeX:
g_{1,1}^{(1)}=\frac{\partial L}{\partial W^{(1)}_{1,1}}=\delta_{h_1}x_1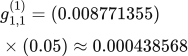 LaTeX:
g_{1,1}^{(1)}=(0.008771355)\times(0.05)\approx 0.000438568Apply the learning rate to this gradient and subtract the result from the old weight.
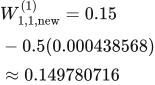 LaTeX:
W^{(1)}_{1,1,\mathrm{new}}=0.15-0.5(0.000438568)\approx 0.149780716x2 → h1:
Subtract η × gradient = 0.000438568. This weight decreases.
The sending value and receiving delta have different roles. All deltas still use the original forward-pass weights.
The receiving neuron supplies the delta; the sending neuron supplies the input value.
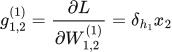 LaTeX:
g_{1,2}^{(1)}=\frac{\partial L}{\partial W^{(1)}_{1,2}}=\delta_{h_1}x_2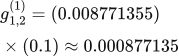 LaTeX:
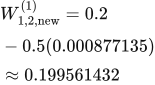
g_{1,2}^{(1)}=(0.008771355)\times(0.1)\approx 0.000877135Apply the learning rate to this gradient and subtract the result from the old weight.
 LaTeX:
W^{(1)}_{1,2,\mathrm{new}}=0.2-0.5(0.000877135)\approx 0.199561432x1 → h2:
Subtract η × gradient = 0.000248856. This weight decreases.
The sending value and receiving delta have different roles. All deltas still use the original forward-pass weights.
The receiving neuron supplies the delta; the sending neuron supplies the input value.
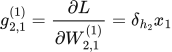 LaTeX:
g_{2,1}^{(1)}=\frac{\partial L}{\partial W^{(1)}_{2,1}}=\delta_{h_2}x_1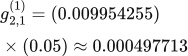 LaTeX:
g_{2,1}^{(1)}=(0.009954255)\times(0.05)\approx 0.000497713Apply the learning rate to this gradient and subtract the result from the old weight.
 LaTeX:
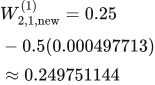
W^{(1)}_{2,1,\mathrm{new}}=0.25-0.5(0.000497713)\approx 0.249751144x2 → h2:
Subtract η × gradient = 0.000497712. This weight decreases.
The sending value and receiving delta have different roles. All deltas still use the original forward-pass weights.
The receiving neuron supplies the delta; the sending neuron supplies the input value.
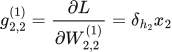 LaTeX:
g_{2,2}^{(1)}=\frac{\partial L}{\partial W^{(1)}_{2,2}}=\delta_{h_2}x_2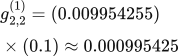 LaTeX:
g_{2,2}^{(1)}=(0.009954255)\times(0.1)\approx 0.000995425Apply the learning rate to this gradient and subtract the result from the old weight.
 LaTeX:
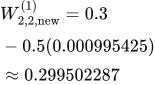
W^{(1)}_{2,2,\mathrm{new}}=0.3-0.5(0.000995425)\approx 0.299502287Step 6 bias updates. A bias receives a constant input 1, so its gradient equals the corresponding delta. Use the same old forward pass and learning rate as the weight updates.
 LaTeX:
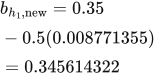
b_{h_1,\mathrm{new}}=0.35-0.5(0.008771355)=0.345614322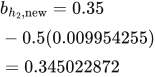 LaTeX:
b_{h_2,\mathrm{new}}=0.35-0.5(0.009954255)=0.345022872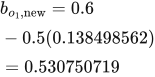 LaTeX:
b_{o_1,\mathrm{new}}=0.6-0.5(0.138498562)=0.530750719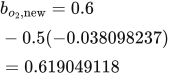 LaTeX:
b_{o_2,\mathrm{new}}=0.6-0.5(-0.038098237)=0.619049118These are independent per-neuron biases. If the question fixes biases, keep them fixed. If it specifies a single tied bias, add all deltas sharing that bias before updating it.
Why the photos add two terms for h₁: dL/dh₁ = δo₁w₅ + δo₂w₇ = 0.138498562 × 0.4 + (−0.038098237) × 0.5 = 0.055399425−0.019049118 = 0.036350306. Now multiply by h₁(1−h₁) = 0.241300709 to obtain δh₁ = 0.008771355; multiply by x₁ = 0.05 to obtain dL/dw₁ = 0.000438568. Adding the two output paths is essential.
Memory sequence: error → output slope → outgoing weight → add paths → hidden slope → input. If you can explain why each factor appears, changed numbers or extra output neurons are much less confusing.
Bias convention: the photo draws one bias value per layer. If these are literally tied scalars rather than equal initial per-neuron biases, sum the relevant deltas: hidden shared b becomes 0.35−0.5(0.008771355+0.009954255) = 0.340637195; output shared b becomes 0.6−0.5(0.138498562−0.038098237) = 0.549799837. If only weights are requested, do not invent a bias update requirement.