Deep Learning · TEE · section
F25 Q1b
Final examination December 2025 fully solved
Question
Question (5 marks). For automated leaf-disease image classification, discuss factors affecting loss selection. For classes Normal, Mild, Severe with target [0,1,0] and predicted probabilities [0.1,0.8,0.1], compute and interpret categorical cross-entropy.
Answer — step by step
Given
Classes = Normal,Mild,Severe; target = [0,1,0].
Predicted probabilities = [0.1,0.8,0.1]; use natural logarithms.
To find
Calculate categorical cross-entropy and interpret the result.
Formula — which one and why
Categorical cross-entropy. For mutually exclusive classes with a one-hot target, all zero-target terms disappear. The loss is the negative log of the probability assigned to the true class.
yⱼ = target entry; pⱼ = predicted probability; c = index of the true class. Use natural logarithms unless another base is specified.
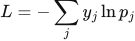 LaTeX:
L=-\sum_j y_j\ln p_j LaTeX:
L=-\ln p_cYaad rakhne ka cue: One-hot mein sirf correct class ki probability ka minus ln.
Solution — step by step
Select a loss according to the task and output meaning: real-valued regression often uses MSE/MAE, binary classification uses binary cross-entropy, and one-of-K classification uses categorical cross-entropy. Consider class imbalance, noisy labels/outliers, whether outputs are calibrated probabilities, and differentiability for optimization.
Step 1: expand the categorical cross-entropy sum.
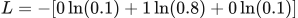 LaTeX:
L=-[0\ln(0.1)+1\ln(0.8)+0\ln(0.1)]Step 2: keep the term for the true class.
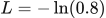 LaTeX:
L=-\ln(0.8)Step 3: calculate its natural logarithm.
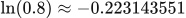 LaTeX:
\ln(0.8)\approx-0.223143551Step 4: negate the logarithm.
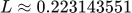 LaTeX:
L\approx0.223143551Final answer: loss ≈ 0.223144 nats. The true class received probability 0.8, so the loss is relatively small; probability 1 would give loss zero.