Deep Learning · TEE · section
F25 Q5a
Final examination December 2025 fully solved
Question
Question (10 marks). State the purpose of each LSTM gate. For “Artificial Intelligence has revolutionized every domain. The work force will have to update themselves to remain relevant,” explain a context change. Calculate C and h given i = 0.7, f = 0.4, o = 0.8, candidate = 0.9, Cprevious = 0.5. Why is LSTM more effective than a simple RNN for language modeling?
Answer — step by step
Given
Activated gate values: i = 0.7,f = 0.4,o = 0.8.
Candidate = 0.9; old cell = 0.5.
To find
Explain the context change in the question; calculate the new cell and hidden state.
Formula — which one and why
LSTM cell and hidden state. Multiply old memory by the forget gate; multiply candidate content by the input gate; add those two contributions. Apply tanh to the new cell and multiply by the output gate.
f,i,o = activated forget/input/output gates; C_old = previous cell; C_tilde = candidate content; C = new cell; h = visible hidden state. ⊙ means elementwise multiplication.
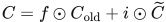 LaTeX:
C=f\odot C_{\mathrm{old}}+i\odot\widetilde C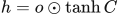 LaTeX:
h=o\odot\tanh CYaad rakhne ka cue: Purana rakho + naya lo; phir tanh aur output gate.
Solution — step by step
An LSTM contains a cell state C and hidden state h. Sigmoid gates control the fractions of information retained, admitted and exposed; a tanh transform proposes new content.
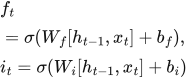 LaTeX:
f_t=\sigma(W_f[h_{t-1},x_t]+b_f),\quad i_t=\sigma(W_i[h_{t-1},x_t]+b_i)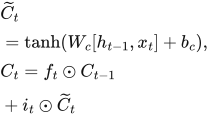 LaTeX:
\widetilde C_t=\tanh(W_c[h_{t-1},x_t]+b_c),\quad C_t=f_t\odot C_{t-1}+i_t\odot\widetilde C_t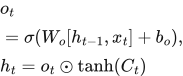 LaTeX:
o_t=\sigma(W_o[h_{t-1},x_t]+b_o),\quad h_t=o_t\odot\tanh(C_t)The forget gate f near 1 retains old content; near 0 removes it. The input gate i controls candidate admission. The output gate o selects the visible state. The additive cell path helps useful information and training signals travel over longer intervals, especially when forget gates retain relevant components.
In language modeling, the cell can retain an earlier subject while intervening words modify other features. When the topic changes, a learned forget gate can reduce obsolete information while the input gate admits new context. These are intuitive interpretations, not numeric gate values derivable from words alone. Exact values require weights, inputs and previous states. LSTMs often learn longer dependencies more effectively than vanilla RNNs, but do not guarantee perfect indefinite memory.
The second sentence shifts attention toward the workforce while retaining useful prior AI context. Input gates can admit the new subject; forget gates can reduce obsolete details.
Step 1: retain old memory.
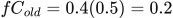 LaTeX:
fC_{old}=0.4(0.5)=0.2Step 2: admit candidate content.
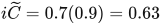 LaTeX:
i\widetilde C=0.7(0.9)=0.63Step 3: add the two contributions.
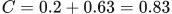 LaTeX:
C=0.2+0.63=0.83Step 4: apply tanh to the updated cell.
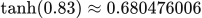 LaTeX:
\tanh(0.83)\approx0.680476006Step 5: multiply by the output gate.
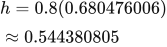 LaTeX:
h=0.8(0.680476006)\approx0.544380805Final answer: C = 0.83 and h ≈ 0.544380805. The supplied gates are already activated; do not apply sigmoid again.