Deep Learning · TEE · section
F25 Q7a
Final examination December 2025 fully solved
Question
Question (10 marks). Explain feedforward information flow, weights, biases and activations, then calculate the output. Input x = [1, 0]. Each row below lists the incoming weights of one receiving neuron. W₁ is shown below; b₁ = [0.1, 0.2]; W₂ is shown below; b₂ = [0.1]. Hidden and output activations are ReLU.
Answer — step by step
Given
Input x = [1, 0].
W₁ is printed with the question.
b₁ = [0.1, 0.2].
W₂ is printed with the question.
b₂ = [0.1].
Hidden and output activations are ReLU.
To find
Find all preactivations, hidden activations and the final output. Explain the role of weights, biases and activations in this forward pass.
Formula — which one and why
Forward propagation. Evaluate one layer completely before supplying its activated outputs to the next layer. Each layer has its own weights and biases.
x = input vector; h = hidden outputs; W₁,b₁ = hidden parameters; W₂,b₂ = output parameters; f₁,f₂ = the stated activations.
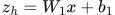 LaTeX:
z_h=W_1x+b_1 LaTeX:
h=f_1(z_h)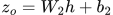 LaTeX:
z_o=W_2h+b_2 LaTeX:
o=f_2(z_o)Yaad rakhne ka cue: Pehli layer ka activated output hi agli layer ka input hai.
ReLU and Leaky ReLU. ReLU returns zero for negative input and retains positive input. Leaky ReLU instead multiplies a negative input by its supplied slope.
z = preactivation; α (alpha) = supplied negative-side slope for Leaky ReLU. The derivative at zero needs an explicit convention.
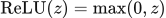 LaTeX:
\operatorname{ReLU}(z)=\max(0,z)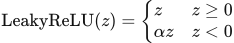 LaTeX:
\operatorname{LeakyReLU}(z)=\begin{cases}z&z\ge0\\\alpha z&z<0\end{cases}Yaad rakhne ka cue: Positive ko rehne do; negative ko zero. Leaky mein chhota negative rehne do.
Solution — step by step
A feedforward network transforms inputs layer by layer with no recurrent feedback. Weights scale contributions; bias shifts the preactivation; activation supplies the nonlinear transformation.
Step 1 map the arrows. Each row of W₁ receives all inputs; each row of W₂ receives all hidden outputs. Bias is added once per receiving neuron.
Hidden neuron 1:
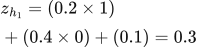 LaTeX:
z_{h_1} = (0.2 \times 1) + (0.4 \times 0) + (0.1) = 0.3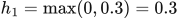 LaTeX:
h_{1} = \max(0,0.3) = 0.3Hidden neuron 2:
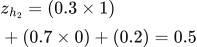 LaTeX:
z_{h_2} = (0.3 \times 1) + (0.7 \times 0) + (0.2) = 0.5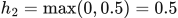 LaTeX:
h_{2} = \max(0,0.5) = 0.5Output neuron 1:
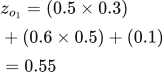 LaTeX:
z_{o_1} = (0.5 \times 0.3) + (0.6 \times 0.5) + (0.1) = 0.55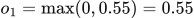 LaTeX:
o_{1} = \max(0,0.55) = 0.55Matrix-orientation note: this solution uses column input and rows as receiving neurons, giving 0.55. The historical key uses the transpose interpretation for W₁ and obtains 0.61. If the problem does not define its orientation, state your convention; do not silently swap it during calculation. Under the alternative: hidden values = [0.3,0.6], output = 0.5 × 0.3+0.6 × 0.6+0.1 = 0.61.