Deep Learning · TEE · section
R26 Q4b
Re examination February 2026 fully solved
Question
Question. Compare LSTM and GRU gates and architecture. Explain the potential computational efficiency of GRU and how its gates can reduce the effect of irrelevant tokens.
Syllabus-aligned extract: source R26 Q4b, parts i–iii. Marks for these retained parts are not separately stated.
Answer — step by step
A GRU uses an update gate and reset gate, with one hidden state and no separate LSTM-style cell state. Under the convention used here, z admits the new candidate:
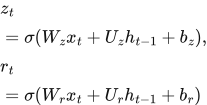 LaTeX:
z_t=\sigma(W_zx_t+U_zh_{t-1}+b_z),\quad r_t=\sigma(W_rx_t+U_rh_{t-1}+b_r)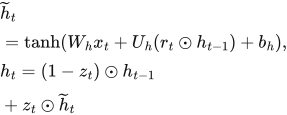 LaTeX:
\widetilde h_t=\tanh(W_hx_t+U_h(r_t\odot h_{t-1})+b_h),\quad h_t=(1-z_t)\odot h_{t-1}+z_t\odot\widetilde h_tThe reset gate controls how much prior hidden information enters the candidate. The update gate balances retention and replacement. A small z retains most of the old state under this formula; another textbook convention swaps z and 1−z. State the formula before interpreting the gate.
Compared with an LSTM's input, forget and output gates plus candidate transform, a standard GRU has two gates plus a candidate transform and usually fewer parameters at equal hidden width. This may reduce training cost and the amount of data needed to estimate parameters, but small-dataset superiority is not guaranteed. Validation should decide. To ignore an unhelpful token, a trained GRU can keep the prior state by admitting little candidate content; it still executes the recurrence rather than literally deleting the token. Both GRU and LSTM help long-range learning compared with an ungated vanilla RNN.