Deep Learning · TEE · section
R24 Q1b
Re examination February 2024 fully solved
Question
Question (5 marks). Draw an animal-classification network with 10 inputs, three hidden layers of 5 neurons each and 4 output classes. Every hidden/output neuron has a bias. Count all trainable parameters.
Answer — step by step
Given
10 input features → 5 hidden → 5 hidden → 5 hidden → 4 output classes.
One bias per hidden/output neuron.
To find
Draw the layer structure and count weights and biases.
Formula — which one and why
Dense-layer parameters. Every output neuron receives every input, so multiply inputs by outputs for weights. Add one bias per receiving neuron. Sum separate layers.
n_in = incoming features; n_out = receiving neurons. The input layer itself has no learned receiving weights or biases.
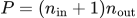 LaTeX:
P=(n_{\mathrm{in}}+1)n_{\mathrm{out}}Yaad rakhne ka cue: Har output ke liye saare inputs plus ek bias.
Solution — step by step
Architecture: 10 → 5 → 5 → 5 → 4. Each non-input neuron has one bias.
Layer 10 → 5
Step 1: count connections.
 LaTeX:
10(5)=50Step 2: count receiving-neuron biases.
There are 5 receiving neurons, so 5 biases.
Step 3: add weights and biases.
 LaTeX:
50+5=55Layer 5 → 5
Step 1: count connections.
 LaTeX:
5(5)=25Step 2: count receiving-neuron biases.
There are 5 receiving neurons, so 5 biases.
Step 3: add weights and biases.
 LaTeX:
25+5=30Layer 5 → 5
Step 1: count connections.
LaTeX: 5(5)=25Step 2: count receiving-neuron biases.
There are 5 receiving neurons, so 5 biases.
Step 3: add weights and biases.
LaTeX: 25+5=30Layer 5 → 4
Step 1: count connections.
 LaTeX:
5(4)=20Step 2: count receiving-neuron biases.
There are 4 receiving neurons, so 4 biases.
Step 3: add weights and biases.
 LaTeX:
20+4=24Total = 139. Input values and activations are not trainable parameters.
Use hidden nonlinearities such as ReLU and a 4-class softmax. Learned parameters are the connections and biases; the number of layers and units are design choices.