Deep Learning · TEE · section
R24 Q3b
Re examination February 2024 fully solved
Question
Question (10 marks). Explain why regularization matters, list techniques and elaborate one.
Answer — step by step
Overfitting means learning training-specific patterns that do not generalize well. Very good training results with substantially worse validation results suggest overfitting, provided both sets are comparable and correctly evaluated. Regularization limits this tendency; its strength should be chosen using validation data.
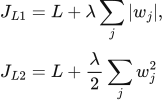 LaTeX:
J_{L1}=L+\lambda\sum_j|w_j|,\qquad J_{L2}=L+\frac{\lambda}{2}\sum_jw_j^2L1 adds a magnitude penalty and can make weights exactly zero at the optimum, encouraging sparsity. Away from zero its added gradient is λ sign(w). L2 adds gradient λw under the displayed convention and smoothly discourages large weights. L2 generally shrinks many weights without making them exactly zero. Some notes omit the half in L2; their added gradient is 2 λw.
Dropout randomly removes selected activations during training, reducing dependence on a particular combination of units. With inverted dropout, retained units are divided by the keep probability q; at inference dropout is disabled and the ordinary network is used. Early stopping monitors validation loss and restores the best validation checkpoint before prolonged fitting to training noise. Data augmentation creates label-preserving input variations. Too much regularization may underfit: both training and validation performance can then worsen.
Elaborating L2: add(λ/2)Σw² to the data loss. For weight w = .5, data gradient.2, λ = .1, η = .1, total gradient = .2+.1 × .5 = .25, so wnew = .5−.1 × .25 = .475. Relative to the data-only update.48, the penalty pulls the weight further toward 0. Too large λ can remove useful signal, so tune on validation data.