Deep Learning · TEE · section
Drill 23 Nesterov variation 2
Numerical practice from direct to mixed
Question
Question. J(θ) = ½(θ−1)², θ₀ = -0.5, η = 0.1. Perform two Nesterov updates. Use β = 0.9, v₀ = 0 and signed velocity.
Answer — step by step
Given
Objective: J(θ) = ½(θ−1)².
Initial θ₀ = −0.5; η = 0.1; two iterations.
β = 0.9; initial signed velocity v₀ = 0.
To find
Find every stored state needed by the method and the parameter after each of two updates.
Formula — which one and why
Nesterov lookahead. First look ahead using the old velocity. Measure the gradient there, form the new velocity, then add that velocity to the original current parameter.
θ_look = temporary gradient-evaluation point; v = signed displacement; β = momentum coefficient; η = learning rate.
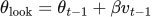 LaTeX:
\theta_{\mathrm{look}}=\theta_{t-1}+\beta v_{t-1}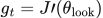 LaTeX:
g_t=J\prime(\theta_{\mathrm{look}})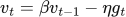 LaTeX:
v_t=\beta v_{t-1}-\eta g_t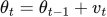 LaTeX:
\theta_t=\theta_{t-1}+v_tYaad rakhne ka cue: Pehle look ahead; gradient wahan; update original position se.
Solution — step by step
Meaning of the symbols
θ (theta) is the number we update. η (eta) is learning rate 0.1. g is the derivative of the objective, evaluated at the required position. A subscript counts updates; θ₀ means the starting value.
Differentiate the objective first
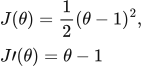 LaTeX:
J(\theta)=\frac12(\theta-1)^2,\qquad J\prime(\theta)=\theta-1The power rule brings down 2, which cancels the half. The inside derivative is 1, so the remaining gradient is θ minus 1.
Update formulas
v stores the signed movement from the previous update. β = 0.9 retains 90% of that movement. Start v₀ = 0.
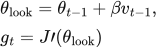 LaTeX:
\theta_{\mathrm{look}}=\theta_{t-1}+\beta v_{t-1},\quad g_t=J\prime(\theta_{\mathrm{look}})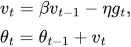 LaTeX:
v_t=\beta v_{t-1}-\eta g_t,\quad \theta_t=\theta_{t-1}+v_tStep 1: Update 1.
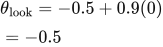 LaTeX:
\theta_{\mathrm{look}}=-0.5+0.9(0)=-0.5 LaTeX:
g_1=-0.5-(1)=-1.5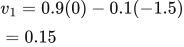 LaTeX:
v_1=0.9(0)-0.1(-1.5)=0.15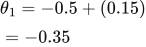 LaTeX:
\theta_1=-0.5+(0.15)=-0.35Step 2: Update 2.
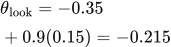 LaTeX:
\theta_{\mathrm{look}}=-0.35+0.9(0.15)=-0.215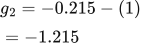 LaTeX:
g_2=-0.215-(1)=-1.215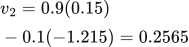 LaTeX:
v_2=0.9(0.15)-0.1(-1.215)=0.2565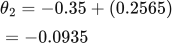 LaTeX:
\theta_2=-0.35+(0.2565)=-0.0935Final parameter after two updates: -0.0935. The lookahead locates the gradient; the new velocity is added to the old actual parameter, not to the lookahead.