Deep Learning · TEE · section
Drill 32 L2 update
Numerical practice from direct to mixed
Question
Question. w = [0.5,−0.2], data gradients = [0.1,0.3], λ = 0.2, η = 0.1. Use(λ/2)Σw².
Answer — step by step
Given
Old weights = [0.5,−0.2]; data gradients = [0.1,0.3].
λ = 0.2; η = 0.1; penalty = (λ/2)Σw².
To find
Find penalty gradients, total gradients and updated weights.
Formula — which one and why
L2 penalty with a factor of one-half. Square each weight, sum and multiply by λ/2. The one-half cancels the factor 2 when differentiating, so the extra gradient is λw.
λ = penalty strength; w = old weight; J_data and g_data = data loss and its gradient.
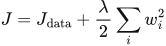 LaTeX:
J=J_{\mathrm{data}}+\frac\lambda2\sum_iw_i^2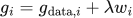 LaTeX:
g_i=g_{\mathrm{data},i}+\lambda w_i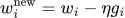 LaTeX:
w_i^{\mathrm{new}}=w_i-\eta g_iYaad rakhne ka cue: Half wala L2 derivative mein lambda × weight deta hai.
Solution — step by step
Formula and its reason
The derivative of (λ/2)w² is λw: the 2 from the square cancels the half. Add that regularization gradient to the given data gradient before updating.
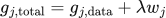 LaTeX:
g_{j,\mathrm{total}}=g_{j,\mathrm{data}}+\lambda w_j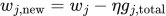 LaTeX:
w_{j,\mathrm{new}}=w_j-\eta g_{j,\mathrm{total}}Step 1: Weight 1.
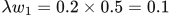 LaTeX:
\lambda w_1=0.2\times0.5=0.1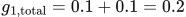 LaTeX:
g_{1,\mathrm{total}}=0.1+0.1=0.2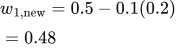 LaTeX:
w_{1,\mathrm{new}}=0.5-0.1(0.2)=0.48Step 2: Weight 2.
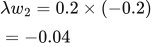 LaTeX:
\lambda w_2=0.2\times(-0.2)=-0.04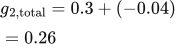 LaTeX:
g_{2,\mathrm{total}}=0.3+(-0.04)=0.26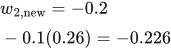 LaTeX:
w_{2,\mathrm{new}}=-0.2-0.1(0.26)=-0.226Final answer: [0.48, −0.226]. The second data gradient dominates the regularization term, explaining why that negative weight becomes more negative.