Deep Learning · TEE · section
Drill 4 Dot product and bias
Numerical practice from direct to mixed
Question
Question. Find z for x = [2,−1,0.5], w = [0.3,0.4,−0.2], b = 0.1; then apply ReLU.
Answer — step by step
Given
Inputs x = [2, −1, 0.5].
Weights w = [0.3, 0.4, −0.2]; bias b = 0.1.
Activation: ReLU.
To find
Find the weighted sum z and ReLU output.
Formula — which one and why
Weighted sum and activation. Each input is multiplied by its connection weight. Add these contributions, add the bias once, then apply the stated activation.
xᵢ = input i; wᵢ = its weight; b = bias; z = sum before activation; a = output after activation; f = the specified activation function.
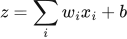 LaTeX:
z=\sum_iw_ix_i+b LaTeX:
a=f(z)Yaad rakhne ka cue: Input × weight, sabka sum, bias once, phir activation.
ReLU and Leaky ReLU. ReLU returns zero for negative input and retains positive input. Leaky ReLU instead multiplies a negative input by its supplied slope.
z = preactivation; α (alpha) = supplied negative-side slope for Leaky ReLU. The derivative at zero needs an explicit convention.
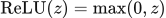 LaTeX:
\operatorname{ReLU}(z)=\max(0,z)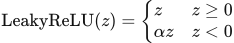 LaTeX:
\operatorname{LeakyReLU}(z)=\begin{cases}z&z\ge0\\\alpha z&z<0\end{cases}Yaad rakhne ka cue: Positive ko rehne do; negative ko zero. Leaky mein chhota negative rehne do.
Solution — step by step
Meaning and formulas
A dot product means multiply corresponding entries, then add the products. A bias is one extra value added after the sum. ReLU keeps a positive result and replaces a negative result with zero.
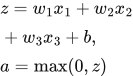 LaTeX:
z=w_1x_1+w_2x_2+w_3x_3+b,\qquad a=\max(0,z)Here x contains inputs, w contains weights, b is bias, z is the weighted sum, and a is the activated output.
Step 1: multiply the matching pairs
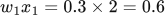 LaTeX:
w_1x_1=0.3\times2=0.6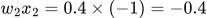 LaTeX:
w_2x_2=0.4\times(-1)=-0.4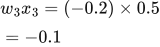 LaTeX:
w_3x_3=(-0.2)\times0.5=-0.1Step 2: add all products and add bias once
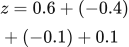 LaTeX:
z=0.6+(-0.4)+(-0.1)+0.1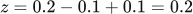 LaTeX:
z=0.2-0.1+0.1=0.2Step 3: apply the activation
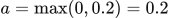 LaTeX:
a=\max(0,0.2)=0.2Final answer: weighted sum z = 0.2; ReLU output a = 0.2. The two numbers happen to match because z is positive.