Deep Learning · TEE · section
The one page method map
Formula reference and exam revision
| Question clue | First action | Core formula or check |
|---|---|---|
| Neuron output | Multiply each input by its matching weight | 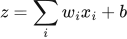 LaTeX: z=\sum_iw_ix_i+b, then activate |
| Network prediction | Finish one whole layer before the next | 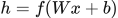 LaTeX: h=f(Wx+b) |
| Backpropagation | State loss then prediction-minus-target | delta times sending activation |
| Optimizer update | Identify current gradient and stored state | old parameter minus update |
| CNN dimensions | Write N K S P and channels | 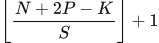 LaTeX: \left\lfloor\frac{N+2P-K}{S}\right\rfloor+1 |
| CNN parameters | Count one filter then all filters | 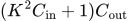 LaTeX: (K^2C_{\mathrm{in}}+1)C_{\mathrm{out}} |
| Pooling | Draw every valid window | Maximum, or mean of the window |
| Dense parameters | Count connections and receiving biases | 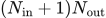 LaTeX: (N_{\mathrm{in}}+1)N_{\mathrm{out}} |
| RNN hidden state | Add new-input and old-state transforms | 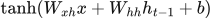 LaTeX: \tanh(W_{xh}x+W_{hh}h_{t-1}+b) |
| LSTM | Retain old add new then expose | Retain old cell, add admitted candidate, then apply output gate |
| GRU | Check the stated z convention | 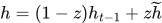 LaTeX: h=(1-z)h_{t-1}+z\widetilde h |