Deep Learning · TEE · section
R25 Q5a · ResNet shortcut and Inception1×1
February 2025 re-exam · complete solved paper
Question
Question. Describe skip connections and their benefit in ResNet. Explain a1×1convolution’s role in Inception with an example. (10 marks)
Answer — step by step
Definition. A residual network uses shortcut connections to learn a residual mapping relative to a block's input. A basic residual block adds the block transformation F(x) to a shortcut representation of x.
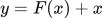 LaTeX:
y=F(x)+xIf the desired mapping is H(x), the residual branch represents F(x) = H(x) − x. When the useful mapping is close to identity, a small residual can be easier to optimize than reconstructing identity through the entire branch.
Effect on gradient propagation
For the identity-shortcut formulation, the derivative includes a direct identity contribution.
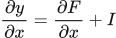 LaTeX:
\frac{\partial y}{\partial x}=\frac{\partial F}{\partial x}+IThis provides a path for information and derivatives that does not require passing through every weight layer in the residual branch. It helps optimize deep networks and addresses the degradation problem. It does not imply that every possible ResNet is immune to vanishing gradients.
Projection when dimensions differ
If channels or spatial dimensions change, use a projection shortcut, often a 1 × 1 convolution with suitable stride.
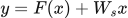 LaTeX:
y=F(x)+W_sxAn identity shortcut has no learned parameters. A projection does. For Cᵢ input channels and Cₒ output channels, a biased 1 × 1 projection has CᵢCₒ + Cₒ parameters. The residual branch's output must match the projection output for addition.
Question. Let x = [1, 2, 3] and F(x) = [0.1, −0.2, 0.3]. Find the residual sum.
Given
x = [1,2,3]; residual branch F(x) = [0.1,−0.2,0.3].
To find
Find the three components of x+F(x).
Formula — which one and why
Residual addition. Add corresponding components of the input shortcut and learned branch. Apply the output activation afterward if requested.
x = shortcut/input; F(x) = residual branch output. Both arrays must have matching shapes before addition.
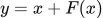 LaTeX:
y=x+F(x)Yaad rakhne ka cue: Same position ke numbers add; shape same rehni chahiye.
Solution — step by step
Step 1: add the first matching pair.
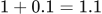 LaTeX:
1+0.1=1.1Step 2: add the second matching pair.
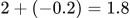 LaTeX:
2+(-0.2)=1.8Step 3: add the third matching pair.
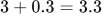 LaTeX:
3+0.3=3.3Step 4: assemble in the original order.
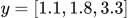 LaTeX:
y=[1.1,1.8,3.3]The vector length remains 3. Concatenating these vectors would give length 6 and would implement a different operation. Any post-addition activation specified in the architecture is applied after this sum.
Definition. A 1 × 1 convolution combines the input channels independently at each spatial location. A bottleneck uses fewer output channels before a larger spatial convolution, reducing its parameter and multiplication counts.
Question. Input is 28 × 28 × 192. Compare a direct same-padded 5 × 5 convolution with 32 filters against a 1 × 1 reduction to 16 channels followed by the same 5 × 5 convolution. Count MACs and ignore bias additions.
Given
Both paths produce 28 × 28 × 32. The direct layer receives 192 channels; the bottleneck's spatial layer receives 16 channels. Stride is 1 and padding preserves spatial size.
To find
Direct MACs, total two-stage bottleneck MACs and percentage saved.
Formula — which one and why
Each output scalar uses one product per input-channel kernel entry. Multiply that cost by the number of output positions and channels. The two bottleneck layers require separate counts, which are added.
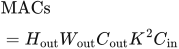 LaTeX:
\mathrm{MACs}=H_{\mathrm{out}}W_{\mathrm{out}}C_{\mathrm{out}}K^2C_{\mathrm{in}}One MAC counts one multiply–accumulate pair. A convention counting multiplication and addition separately gives approximately twice as many FLOPs.
Solution — step by step
Step 1: direct layer. Each output uses 5 × 5 × 192 = 4,800 products. There are 28 × 28 × 32 = 25,088 outputs.
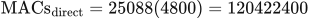 LaTeX:
\mathrm{MACs}_{\mathrm{direct}}=25088(4800)=120422400Step 2: 1 × 1 reduction. There are 16 receiving filters, each spanning all 192 original channels.
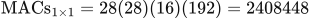 LaTeX:
\mathrm{MACs}_{1\times1}=28(28)(16)(192)=2408448Step 3: reduced-depth spatial layer. Its 32 filters now span 16 channels.
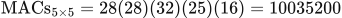 LaTeX:
\mathrm{MACs}_{5\times5}=28(28)(32)(25)(16)=10035200Step 4: add the two bottleneck costs.
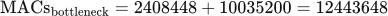 LaTeX:
\mathrm{MACs}_{\mathrm{bottleneck}}=2408448+10035200=12443648Step 5: calculate the saving.
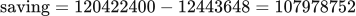 LaTeX:
\mathrm{saving}=120422400-12443648=107978752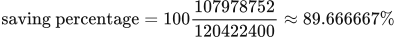 LaTeX:
\mathrm{saving\ percentage}=100\frac{107978752}{120422400}\approx89.666667\%Final answer: direct = 120,422,400 MACs; bottleneck = 12,443,648 MACs, saving about 89.67%. Spatial size is unchanged; the saving comes from reducing the channels entering the expensive 5 × 5 layer. If the reduction width is not supplied, use a symbol for it and label any numerical choice as an assumption.
A second bottleneck with different dimensions
Question. An 8 × 8 × 16 input must produce 8 channels using a same-padded 3 × 3 convolution. Compare direct computation with a 1 × 1 reduction to 4 channels followed by the 3 × 3 layer. Count MACs and ignore bias additions.
Given
Spatial output = 8 × 8; original channels = 16; final filters = 8; bottleneck channels = 4; stride = 1.
To find
Direct MACs, bottleneck MACs and saving.
Formula — which one and why
Use the same MAC formula above once for the direct path and once for each bottleneck stage. Every branch must include all of its layers.
Solution — step by step
Step 1: direct spatial convolution.
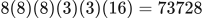 LaTeX:
8(8)(8)(3)(3)(16)=73728Step 2: 1 × 1 reduction.
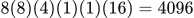 LaTeX:
8(8)(4)(1)(1)(16)=4096Step 3: reduced-depth 3 × 3 convolution.
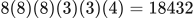 LaTeX:
8(8)(8)(3)(3)(4)=18432Step 4: add the stages and subtract from the direct cost.
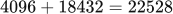 LaTeX:
4096+18432=22528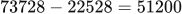 LaTeX:
73728-22528=51200Final answer: direct = 73,728 MACs; bottleneck = 22,528 MACs; saving = 51,200 MACs, about 69.44%. Both paths produce 8 × 8 × 8, but they are different learned transformations and need not produce identical feature values.