Deep Learning · TEE · section
Faculty Assignment2 Q3 · 28×28 CNN
Faculty Assignment 2 · worked practice
Question
Question. Input28×28×1; conv5,6valid; pool2stride2; conv5,16valid; pool2stride2; dense120,dense84,dense10. Find layer dimensions and parameters. (Faculty assignment: no marks printed)
Answer — step by step
Given
Input=[28, 28, 1]
| Layer | Kernel | Stride | Padding | Filters / units |
|---|---|---|---|---|
| Conv | 5 | 1 | 0 | 6 |
| Pool | 2 | 2 | 0 | 0 |
| Conv | 5 | 1 | 0 | 16 |
| Pool | 2 | 2 | 0 | 0 |
| Dense | 0 | 0 | 0 | 120 |
| Dense | 0 | 0 | 0 | 84 |
| Dense | 0 | 0 | 0 | 10 |
To find
Each output shape and all trainable weights plus biases.
Formula: which one and why
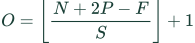 LaTeX:
O=\left\lfloor\frac{N+2P-F}{S}\right\rfloor+1 LaTeX:
P_{conv}=(F_hF_wC_{in}+1)C_{out},\quad P_{dense}=(n_{in}+1)n_{out}Each filter/unit has one bias. Pooling has zero learned parameters. Flatten preserves the number of values, then a dense layer connects every input value to every output unit.
Step 1. Work layer by layer
| Layer | Input | Full substitution and reason | Output | Parameters |
|---|---|---|---|---|
| Conv | 28×28×1 | ⌊(28+2×0−5)/1⌋+1=24; parameters=(5×5×1+1)×6=156 | 24×24×6 | 156 |
| Pool | 24×24×6 | ⌊(24−2)/2⌋+1=12; channels stay 6; no trainable weights | 12×12×6 | 0 |
| Conv | 12×12×6 | ⌊(12+2×0−5)/1⌋+1=8; parameters=(5×5×6+1)×16=2416 | 8×8×16 | 2416 |
| Pool | 8×8×16 | ⌊(8−2)/2⌋+1=4; channels stay 16; no trainable weights | 4×4×16 | 0 |
| Dense | 4×4×16 | Flatten/input length=4×4×16=256; parameters=(256+1)×120=30840 | 120 | 30840 |
| Dense | 1×1×120 | Flatten/input length=1×1×120=120; parameters=(120+1)×84=10164 | 84 | 10164 |
| Dense | 1×1×84 | Flatten/input length=1×1×84=84; parameters=(84+1)×10=850 | 10 | 850 |
Step 2. Sum only trainable parameters
156 + 2416 + 30840 + 10164 + 850 = 44426
Final answer
Total parameters=44426. Shape and parameter count are separate results.