Deep Learning · TEE · section
A vector is a list and a matrix is a table
The maths behind a network
The input [2, 3] is a vector containing two features. A matrix is a rectangle of numbers. “2 by 3” means two rows and three columns. A column vector with two entries has shape 2 by 1. Always write rows before columns.
In this course, unless a question’s diagram explicitly uses another convention, each row of a weight matrix belongs to one receiving neuron. Thus W has shape number of output neurons by number of input features, and the input is a column vector.
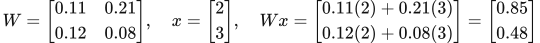 LaTeX:
W=\begin{bmatrix}0.11&0.21\\0.12&0.08\end{bmatrix},\quad x=\begin{bmatrix}2\\3\end{bmatrix},\quad Wx=\begin{bmatrix}0.11(2)+0.21(3)\\0.12(2)+0.08(3)\end{bmatrix}=\begin{bmatrix}0.85\\0.48\end{bmatrix}Do it slowly: row 1 says 0.11 × 2 = 0.22 and 0.21 × 3 = 0.63, so its answer is 0.85. Row 2 says 0.12 × 2 = 0.24 and 0.08 × 3 = 0.24, so its answer is 0.48. Matrix multiplication is several weighted sums written together.
Shape check: (2 by 2) × (2 by 1) gives (2 by 1). The inside numbers must match; the outside numbers are the answer shape. This check catches many transposed-weight errors before arithmetic begins.
Transpose swaps rows and columns. Elementwise multiplication does not do row-by-column sums: [2, 3] ⊙ [4, 5] = [8, 15]. Dot product does add: [2, 3] · [4, 5] = 8 + 15 = 23. LSTM gates use elementwise multiplication, not a dot product.
Practice. Multiply W =  LaTeX:
\begin{bmatrix}1 & 2\\3 & 4\end{bmatrix} by x = [2, 1] as a column. Answer: first row 1 × 2 + 2 × 1 = 4; second row 3 × 2 + 4 × 1 = 10. With b = [1, −1], Wx + b = [5, 9].