Deep Learning · TEE · section
The ordinary gradient descent update
Optimization algorithms
Definition. Gradient descent is an iterative first-order optimization algorithm that updates parameters in the negative direction of the current objective gradient, scaled by a positive learning rate.
Explanation and working
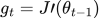 LaTeX:
g_t=J\prime(\theta_{t-1})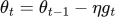 LaTeX:
\theta_t=\theta_{t-1}-\eta g_tHere update numbers start at t = 1: calculate g₁ at θ₀, obtain θ₁, then calculate g₂ at θ₁. The subscript counts completed updates; it is not an exponent.
Read it aloud: “new parameter equals old parameter minus learning rate times current gradient.” The old parameter is where you are. The gradient gives the local uphill direction. The learning rate controls how far you move in the opposite direction.
Question. J(θ) = 0.7 θ³; θ₀ = 1; η = 0.1. Perform two iterations.
Given
J(θ) = 0.7θ³; initial θ₀ = 1; η = 0.1.
To find
Differentiate J and perform two gradient-descent iterations.
Formula — which one and why
Gradient descent. Evaluate the gradient at the current parameter, multiply by the learning rate and subtract. If the objective is supplied, differentiate it and recompute the gradient after each update.
θ (theta) = trainable parameter; g = derivative of the stated objective J; η = learning rate; t labels the update number.
LaTeX: g_t=J\prime(\theta_{t-1})LaTeX: \theta_t=\theta_{t-1}-\eta g_tYaad rakhne ka cue: Naya = purana − learning rate × current gradient.
Solution — step by step
Step 1. Differentiate. g(θ) = 0.7 × 3 × θ² = 2.1 θ².
Step 2. First update. g₁ = 2.1(1)² = 2.1. θ₁ = 1 − 0.1(2.1) = 0.79.
Step 3. Second gradient. Square the new value: 0.79² = 0.6241. Multiply: g₂ = 2.1 × 0.6241 = 1.31061.
Step 4. Second update. θ₂ = 0.79 − 0.1(1.31061) = 0.79 − 0.131061 = 0.658939.
The paper calls this SGD. With only a scalar objective supplied, no sample selection is specified; the arithmetic is the stated gradient-descent update. Also, this cubic is not bounded below over all real values. Do not claim these two steps prove convergence to a global minimum.
Common error: using the loss J itself instead of its derivative g. Another error is repeatedly using θ₀ to calculate later gradients.