Deep Learning · TEE · section
Model answer: batch, stochastic and mini-batch training
Optimization algorithms
Question
Question. Differentiate batch gradient descent, stochastic gradient descent and mini-batch gradient descent. Explain an epoch, a batch and an iteration.
Answer — step by step
All three methods update model parameters using gradients. Their difference is the number of training examples used to estimate the gradient for one update.
A batch is the group of examples used together for an update. An iteration, in this context, is one optimizer update. An epoch is one complete pass through the chosen training dataset. One epoch usually contains several iterations.
| Basis | Batch GD | Stochastic GD | Mini-batch GD |
|---|---|---|---|
| Examples in one gradient | Entire training dataset | One example | A smaller group of B examples |
| Updates per epoch | One | N | Ceiling of N/B if the remainder is retained |
| Gradient behavior | Full-data gradient | Noisy sample gradient | Intermediate averaging |
| Practical implication | Updates can be expensive on large datasets | Many small, sequential updates | Common compromise for vectorized computation |
Example to distinguish the three counts
With 105 examples and batch size 20, five batches use 100 examples and a sixth uses the remaining 5. Therefore one epoch has 6 mini-batch updates. Three epochs give 18 updates. It would be 5 updates per epoch only if the problem explicitly discarded the incomplete batch.
The basic parameter update is unchanged:
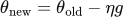 LaTeX:
\theta_{\mathrm{new}}=\theta_{\mathrm{old}}-\eta gFor batch or mini-batch training, g normally represents the gradient of the stated aggregate loss over that group. For sequential SGD, update after each example and use the new parameter for the next example. Consequently, one SGD epoch need not equal one batch update even when both use the same examples.