Deep Learning · TEE · section
Reading LeNet and AlexNet layer diagrams
CNN architectures and transfer learning
A layer diagram describes two different things: the size of the data moving through the network and the trainable operations that transform that data. A number such as 9,216 beside a flatten operation describes data length; it does not automatically mean another dense layer with 9,216 neurons.
LeNet: follow the image as it becomes a class prediction
The classroom LeNet layout begins with a 32 × 32 grayscale image. A valid 5 × 5 convolution with six filters produces 28 × 28 × 6. A 2 × 2 pooling operation with stride 2 produces 14 × 14 × 6. The next valid 5 × 5 convolution produces 10 × 10 × 16, and pooling reduces this to 5 × 5 × 16. A 5 × 5 convolution across those 16 channels produces 1 × 1 × 120. The final representation passes through 84 units and then ten class outputs.
| Stage | What happens | Output shape |
|---|---|---|
| Input | One grayscale image | 32 × 32 × 1 |
| C1 | Six 5 × 5 filters, stride 1, no padding | 28 × 28 × 6 |
| S2 | 2 × 2 average pooling, stride 2 | 14 × 14 × 6 |
| C3 | Sixteen 5 × 5 filters, stride 1, no padding | 10 × 10 × 16 |
| S4 | 2 × 2 average pooling, stride 2 | 5 × 5 × 16 |
| C5 | 120 filters covering the complete 5 × 5 spatial map | 1 × 1 × 120 |
| F6 | Dense transformation | 84 values |
| Classifier | Modern classroom softmax classifier | Ten probabilities |
The original LeNet-5 used details such as partial channel connectivity, trainable subsampling and an RBF output. A modern full-channel implementation with ordinary pooling and softmax is a different parameter-count convention. For a numerical, follow the question's diagram and state the convention. The complete LeNet parameter numerical in the solved-paper section uses the modern classroom convention.
AlexNet: identify the flatten step correctly
For the faculty's 227 × 227 × 3 classroom input, the main shape sequence is 55 × 55 × 96 → 27 × 27 × 96 → 27 × 27 × 256 → 13 × 13 × 256 → 13 × 13 × 384 → 13 × 13 × 384 → 13 × 13 × 256 → 6 × 6 × 256. Flattening gives 9,216 values; the three dense outputs are 4,096, 4,096 and 1,000. There is no extra learned 9,216-unit layer between flattening and the first 4,096-unit layer.
Question (practice, 3 marks). An AlexNet-style first layer receives a 227 × 227 RGB image and uses 96 filters of size 11 × 11, stride 4 and no padding. Find its output shape, trainable parameters including bias, and the number of output activation values.
Given
Input height and width = 227; input channels = 3; kernel = 11; stride = 4; padding = 0; output filters = 96. One bias is used per filter.
To find
The three-dimensional output shape, parameter count and activation count.
Formula — which one and why
The output-size formula counts valid window positions. Parameter count counts stored filter coefficients, reused at every position. Activation count counts the values produced for one image.
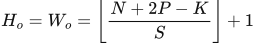 LaTeX:
H_o=W_o=\left\lfloor\frac{N+2P-K}{S}\right\rfloor+1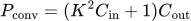 LaTeX:
P_{\mathrm{conv}}=(K^2C_{\mathrm{in}}+1)C_{\mathrm{out}}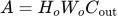 LaTeX:
A=H_oW_oC_{\mathrm{out}}Here N is input side length, P is padding per side, K is kernel side length, S is stride, and C denotes channel count. The symbol P in the output formula means padding; the labelled quantity P_conv means parameters.
Solution — step by step
Step 1: calculate one spatial side.
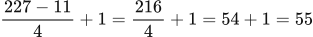 LaTeX:
\frac{227-11}{4}+1=\frac{216}{4}+1=54+1=55Step 2: attach the output depth. There is one output map per filter, so the output is 55 × 55 × 96.
Step 3: count the weights in one filter.
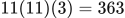 LaTeX:
11(11)(3)=363Step 4: add one bias and multiply by 96 filters.
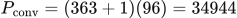 LaTeX:
P_{\mathrm{conv}}=(363+1)(96)=34944Step 5: count activation values for one image.
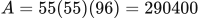 LaTeX:
A=55(55)(96)=290400Final answer: output = 55 × 55 × 96; parameters = 34,944; activations = 290,400. The weights are reused, so parameters and activations are different counts. The full faculty-style ungrouped AlexNet table totals 62,378,344 parameters; the original grouped model uses different channel connectivity.
Yaad rakho: shape = kitne answers nikle; parameters = kitne numbers seekhe.