Deep Learning · TEE · section
The faculty's 480-channel bottleneck numerical
CNN architectures and transfer learning
Question (practice, 3 marks). Compare a direct same-padded 5 × 5 convolution with 48 filters on a 14 × 14 × 480 input against a 1 × 1 reduction to 16 channels followed by the same 5 × 5, 48-filter layer. Use stride 1. Count MACs, ignore bias additions, and find the percentage reduction.
Given
Both paths produce 14 × 14 × 48. Direct spatial filters span 480 channels; reduced spatial filters span 16. The reduction has 16 output filters.
To find
MACs for the direct path, both bottleneck stages, their total and percentage saved.
Formula — which one and why
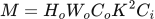 LaTeX:
M=H_oW_oC_oK^2C_iM is the MAC count. H_oW_oC_o counts output values; K²C_i is the products used for each output. One MAC means one multiply-accumulate pair. Count both layers of the bottleneck.
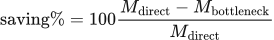 LaTeX:
\mathrm{saving}\%=100\frac{M_{\mathrm{direct}}-M_{\mathrm{bottleneck}}}{M_{\mathrm{direct}}}Solution — step by step
Step 1: direct output count. 14 × 14 × 48 = 9,408.
Step 2: products per direct output. 5 × 5 × 480 = 12,000.
Step 3: direct MACs.
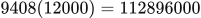 LaTeX:
9408(12000)=112896000Step 4: reduction-layer MACs. Each of 14 × 14 × 16 outputs combines 480 values.
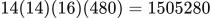 LaTeX:
14(14)(16)(480)=1505280Step 5: reduced spatial-layer MACs. Each of 9,408 outputs now combines 5 × 5 × 16 = 400 values.
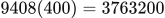 LaTeX:
9408(400)=3763200Step 6: add both bottleneck costs.
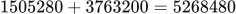 LaTeX:
1505280+3763200=5268480Step 7: calculate the saving.
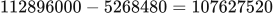 LaTeX:
112896000-5268480=107627520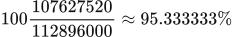 LaTeX:
100\frac{107627520}{112896000}\approx95.333333\%Final answer: direct = 112.896 million MACs; bottleneck = 5.26848 million MACs; saving ≈ 95.33%. The lecture's 112.9M and 5.3M are rounded versions. This arithmetic proves reduced computation; equal prediction accuracy is not guaranteed by the count alone.