Intelligent Systems II · TEE · formulas
GA and PSO formulas, symbols and memory rules
All M2 formulas
One place for the formulas, meanings, conditions and links to full worked examples.
Binary decoding
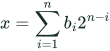 LaTeX:
x=\sum_{i=1}^{n}b_i2^{n-i}bᵢ is a bit; the maximum n-bit unsigned integer is 2ⁿ−1.
Full explanation and worked solutions →
Roulette selection
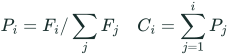 LaTeX:
P_i=F_i/\sum_jF_j\quad C_i=\sum_{j=1}^iP_jFitness weights must be nonnegative with a positive total. For minimisation use the specified transformation or selection method. C is cumulative probability.
Full explanation and worked solutions →
Population average
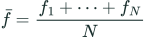 LaTeX:
\bar f=\frac{f_1+\cdots+f_N}{N}N is the number of individuals. Compare both best and average; mutation need not improve either.
Full explanation and worked solutions →
PSO velocity
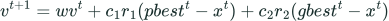 LaTeX:
v^{t+1}=wv^t+c_1r_1(pbest^t-x^t)+c_2r_2(gbest^t-x^t)w weights inertia; c₁r₁ weights personal pull; c₂r₂ weights social pull. Apply the same equation separately to each coordinate.
Full explanation and worked solutions →
PSO position
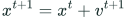 LaTeX:
x^{t+1}=x^t+v^{t+1}Use the new velocity, not the old one. Then reevaluate the objective.
Full explanation and worked solutions →
Memory updates: minimise → replace a pbest only for a lower score; maximise → only for a higher score. gbest is a position selected from the personal bests. Store the corresponding objective score alongside it. Keep previous best on ties unless instructed otherwise.
Yaad rakho: Formula ke pehle objective direction aur old state likho. Iteration 2 mein fresh positions aur retained memories use karo.
Encoding and minimisation conventions
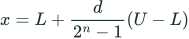 LaTeX:
x=L+\frac{d}{2^n-1}(U-L)For the specified uniform real-range encoding: decode n bits into unsigned integer d first. L and U are the physical limits. Endpoint examples →
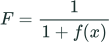 LaTeX:
F=\frac{1}{1+f(x)}This is the stated roulette transformation in our nonnegative-cost minimisation example. It is not required for every GA. It converts a smaller cost into a larger selection weight. Complete minimisation example →