Intelligent Systems II · TEE · formulas
Unit 1 formulas: probability, Bayes, naive Bayes, Bayesian networks, GMM
TEE formula sheet · Units 1 and 4
Probability, Bayes, GMM/EM, Markov chains and Bellman equations (Units 2–3 are in the M2 sheet)
Conditions and notation for this revision sheet
Conditional probabilities require nonzero evidence probability. “Prior” means the class probability before the features; “likelihood” is the feature probability given a class; “posterior” is the class probability after evidence. Σ adds alternatives; Π multiplies factors; argmax returns the winning label. For Laplace smoothing, Nc is the class count and k is the number of possible values of the particular feature.
For the Jensen expression below, λ weights are nonnegative, sum to 1, and the logged arguments are positive. For a Gaussian, σ>0. GMM weights πk are nonnegative and sum to 1; γik or λki are responsibilities, not the mixing weights themselves.
Worked explanations: Naive Bayes · CPTs and Bayesian networks · Mean, variance and likelihood · EM update.
| Conditional | 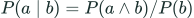 LaTeX: P(a\mid b)=P(a\land b)/P(b) |
|---|---|
| Product rule | 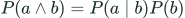 LaTeX: P(a\land b)=P(a\mid b)P(b) |
| Marginalisation | 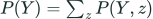 LaTeX: P(Y)=\sum_zP(Y,z) |
| Normalisation | 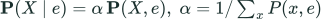 LaTeX: \mathbf P(X\mid e)=\alpha\,\mathbf P(X,e),\;\alpha=1/\sum_xP(x,e) |
| Bayes' rule | 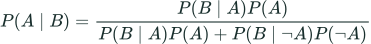 LaTeX: P(A\mid B)=\dfrac{P(B\mid A)P(A)}{P(B\mid A)P(A)+P(B\mid\lnot A)P(\lnot A)} |
| Naive Bayes | 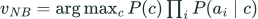 LaTeX: v_{NB}=\arg\max_cP(c)\prod_iP(a_i\mid c); Laplace:  LaTeX: \frac{n_{ic}+1}{N_c+k} |
| BN chain rule | 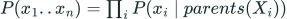 LaTeX: P(x_1..x_n)=\prod_iP(x_i\mid parents(X_i)) |
| BN query |  LaTeX: P(X\mid e)=\alpha\sum_{\text{hidden}}\prod P(\cdot\mid parents) |
| CPT size | Boolean node with k Boolean parents: independent probability parameters =  LaTeX: 2^k numbers |
| GMM density | 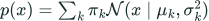 LaTeX: p(x)=\sum_k\pi_k\mathcal N(x\mid\mu_k,\sigma_k^2) |
| Gaussian | 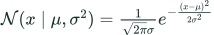 LaTeX: \mathcal N(x\mid\mu,\sigma^2)=\frac1{\sqrt{2\pi}\sigma}e^{-\frac{(x-\mu)^2}{2\sigma^2}} |
| Log-likelihood |  LaTeX: \log L=\sum_i\log\sum_k\pi_k\mathcal N(x_i\mid\mu_k,\sigma_k^2) |
| Jensen (log concave) |  LaTeX: \log\sum_k\lambda_ka_k\ge\sum_k\lambda_k\log a_k |
| E-step | 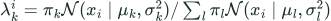 LaTeX: \lambda_k^i=\pi_k\mathcal N(x_i\mid\mu_k,\sigma_k^2)/\sum_l\pi_l\mathcal N(x_i\mid\mu_l,\sigma_l^2) |
| M-step | 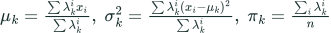 LaTeX: \mu_k=\frac{\sum\lambda_k^ix_i}{\sum\lambda_k^i},\;\sigma_k^2=\frac{\sum\lambda_k^i(x_i-\mu_k)^2}{\sum\lambda_k^i},\;\pi_k=\frac{\sum_i\lambda_k^i}{n} |
| GMM parameters | 1-D:  LaTeX: 3K-1 (K = 5 → 14) |