Intelligent Systems II · TEE · papers
Q7(d) Bellman equation [5]
Re-examination · 25 Jun 2024
Actual historical paper ·100 marks attempted /140 offered · Q1 compulsory + any four of Q2–Q7. Source defects and solution assumptions are explicitly identified.
Explain the Bellman equation in reinforcement learning.
Answer
The Bellman equation expresses a state’s long-term value as immediate expected reward plus discounted value of the next state. It follows by splitting the return into its first reward and the remaining return.
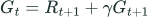 LaTeX:
G_t=R_{t+1}+\gamma G_{t+1}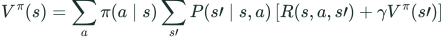 LaTeX:
V^\pi(s)=\sum_a\pi(a\mid s)\sum_{s\prime}P(s\prime\mid s,a)\left[R(s,a,s\prime)+\gamma V^\pi(s\prime)\right]| Symbol | Meaning |
|---|---|
| s, a, s′ | Current state, chosen action, next state |
| π(a|s) | Policy probability of choosing actiona |
| P(s′|s, a) | Environment transition probability |
| R(s, a, s′) | Expected immediate reward for that transition |
| γ | Discount factor, usually 0≤γ<1 for continuing tasks |
| Vπ(s) | Expected discounted return following policyπ |
For a fixed policy, average over its action probabilities. For the optimal value, replace the policy-weighted average by the best action:
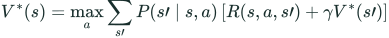 LaTeX:
V^*(s)=\max_a\sum_{s\prime}P(s\prime\mid s,a)\left[R(s,a,s\prime)+\gamma V^*(s\prime)\right]Numerical illustration. An action gives reward 2, then reaches a value 10 state with probability.6 or a value 4 state with probability.4. With γ=.9, its value is.6(2+.9×10)+.4(2+.9×4)=.6×11+.4×5.6=6.6+2.24=8.84. If another action has value 8, the optimality update chooses 8.84. An action value is not just the immediate reward. Bellman recursion underlies policy evaluation, value iteration and many temporal-difference methods.