Intelligent Systems II · TEE · papers
Q7(b) Bellman equations and reinforcement-learning applications [10]
Final / re-examination · 28 Apr 2025
Actual historical paper ·100 marks attempted /140 offered · Q1 compulsory + any four of Q2–Q7. Source defects and solution assumptions are explicitly identified.
Explain Bellman equation in reinforcement learning. Also give applications of reinforcement learning.
Answer
Reinforcement learning (RL) studies an agent that chooses actions, receives rewards and learns a policy to maximize expected cumulative reward through interaction. A policyπ(a|s) describes which action is chosen in a state; the value function measures expected future return, not only the immediate reward.
| Symbol | Meaning |
|---|---|
| s, a | Current state and selected action |
| s′, r | Next state and one-step reward |
| γ | Discount factor; usually 0≤γ<1 for discounted continuing tasks |
| π(a|s) | Probability of actiona under the policy |
| Vπ(s) | Expected discounted return starting in state s and followingπ |
| Qπ(s, a) | Expected discounted return after first choosinga in s, then followingπ |
Step 1. Split the return into present reward and remaining future
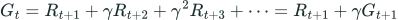 LaTeX:
G_t=R_{t+1}+\gamma R_{t+2}+\gamma^2R_{t+3}+\cdots=R_{t+1}+\gamma G_{t+1}This one-step decomposition is the basis of the Bellman equation: value now equals expected immediate reward plus discounted value of what follows.
Step 2. Write the Bellman expectation equation
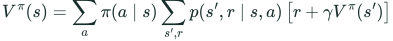 LaTeX:
V^\pi(s)=\sum_a\pi(a\mid s)\sum_{s',r}p(s',r\mid s,a)\left[r+\gamma V^\pi(s')\right]The inner sum averages over uncertain transitions and rewards. The outer sum averages over the policy's actions. For a deterministic action and transition, it reduces toV(s)=r+γV(s′).
Step 3. Write the optimality form
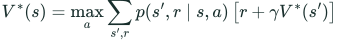 LaTeX:
V^*(s)=\max_a\sum_{s',r}p(s',r\mid s,a)\left[r+\gamma V^*(s')\right]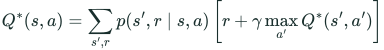 LaTeX:
Q^*(s,a)=\sum_{s',r}p(s',r\mid s,a)\left[r+\gamma\max_{a'}Q^*(s',a')\right]Expectation evaluates a given policy; the maximum chooses the best available action. Value iteration applies this backup repeatedly. Q-learning estimates a corresponding action-value backup from sampled transitions instead of requiring the complete transition model.
Step 4. Use a concrete numerical example
Assumeγ=0.9 and deterministic transitions. ActionA gives reward 2 and a next-state value 10. ActionB gives reward 5 and a next-state value 4.
| Action | Bellman backup | Value |
|---|---|---|
| A | 2+0.9×10 | 11 |
| B | 5+0.9×4 | 8.6 |
The optimality backup choosesA because 11>8.6, even thoughB gives the larger immediate reward. Under a policy selecting both equally, the expectation backup is 0.5×11+0.5×8.6=9.8. These are one-step backups using the given continuation values.
Applications
| Application | State / action / reward example |
|---|---|
| Robot navigation | State:location/sensors; action:move; reward:goal reached with penalties for collision and delay |
| Game playing | State:board configuration; action:legal move; reward:win/loss or a carefully designed game score |
| Traffic-signal control | State:queue lengths; action:signal phase; reward:reduced delay with safety constraints |
| Resource scheduling | State:workload/resources; action:allocate jobs; reward:throughput or energy objective |
| Adaptive recommendation | State:user/context history; action:recommend an item; reward:measured engagement or another validated long-term outcome |
Rewards and exploration policies matter. An agent can optimize the wrong behavior if the reward ignores safety, fairness or the true task objective. A Bellman equation defines the value relation; it does not guarantee that a learned policy is already optimal.