Intelligent Systems II · TEE · papers
Q2(b) GMM: compare with k-means, log-likelihood, parameters [10]
Final examination · 24 Nov 2025
Actual TEE paper · 100 marks · 3 hours · Q1 compulsory + any 4 of Q2–Q7 · every answer verified (key errors flagged)
With reference to the Gaussian Mixture Model (GMM): compare GMM with the k-means algorithm; derive the equation for the log-likelihood function; state the number of parameters to be computed if K = 5. [10 marks]
Answer
Read the derivation’s symbols first
“i.i.d.” means the observations are modelled as independent draws from the same distribution. The product Π runs over observations; the inner sum Σ runs over components. λki in some notes is the same responsibility that other sections call γik. A superscript i here labels the observation, not an exponent.
Jensen’s inequality gives a lower bound on the log of the component sum. EM chooses responsibilities making that bound touch the current likelihood, then updates the parameters to maximise the bound with those responsibilities fixed. This explains the two alternating steps; λ values are not arbitrary new model parameters.
| Parameter | Number in a 1D K-component GMM | Why |
|---|---|---|
| Means | K | One centre for each component |
| Variances | K | One spread for each component |
| Independent mixing weights | K−1 | The last weight is 1 minus the others |
| Total | 3K−1 | K+K+(K−1) |
For K=2, choose μ₁,μ₂,σ₁²,σ₂² and π₁: five free numbers. Then π₂=1−π₁. For K=5, 5+5+4=14. In 2D with a full covariance matrix, each component instead has two means and three independent covariance entries (two variances and one shared off-diagonal covariance). Five such components have 5×(2+3)+4=29 free parameters.
1. GMM versus k-means
| Aspect | k-means | GMM |
|---|---|---|
| Assignment | Hard: each point in exactly one cluster | Soft: probability  LaTeX: \lambda_k^i of belonging to each cluster |
| Model | Geometric: nearest centroid | Probabilistic generative model 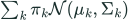 LaTeX: \sum_k\pi_k\mathcal N(\mu_k,\Sigma_k) |
| Cluster shape | Spherical, similar size | Elliptical, any size/orientation; overlapping clusters |
| Parameters | K centroids | Weights, means, covariances (1-D: 3K − 1) |
| Algorithm / objective | Assign–update; minimise squared distances | EM; maximise log-likelihood |
| Output | Hard labels and fitted centroids | Labels, membership probabilities and a density (useful for anomaly detection) |
| Relation | The hard-assignment, equal spherical variance, small-variance limit of a Gaussian-mixture objective leads to the k-means objective. Ordinary finite-variance EM is not the same algorithm as k-means. Both need K in advance and depend on initialisation. | |
2. Derivation of the log-likelihood
Step 1. Model. Each point is generated by choosing component k with probability  LaTeX:
\pi_k and drawing 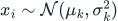 LaTeX:
x_i\sim\mathcal N(\mu_k,\sigma_k^2), so its density is 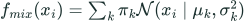 LaTeX:
f_{mix}(x_i)=\sum_k\pi_k\mathcal N(x_i\mid\mu_k,\sigma_k^2).
Step 2. Likelihood. Points are i.i.d., so the likelihood is a product (θ = all parameters):
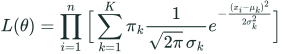 LaTeX:
L(\theta)=\prod_{i=1}^{n}\Big[\sum_{k=1}^{K}\pi_k\frac{1}{\sqrt{2\pi}\,\sigma_k}e^{-\frac{(x_i-\mu_k)^2}{2\sigma_k^2}}\Big]Step 3. Log-likelihood. Logs turn the product into a sum:
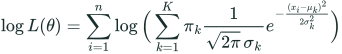 LaTeX:
\log L(\theta)=\sum_{i=1}^{n}\log\Big(\sum_{k=1}^{K}\pi_k\frac{1}{\sqrt{2\pi}\,\sigma_k}e^{-\frac{(x_i-\mu_k)^2}{2\sigma_k^2}}\Big)Step 4. Why it cannot be solved directly. The sum sits inside the log, so setting derivatives to zero gives no closed-form solution.
Step 5. Jensen's inequality. log is concave, so for weights 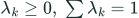 LaTeX:
\lambda_k\ge0,\;\sum\lambda_k=1: 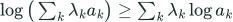 LaTeX:
\log\big(\sum_k\lambda_ka_k\big)\ge\sum_k\lambda_k\log a_k. Introduce LaTeX: \lambda_k^i for every point ( LaTeX:
\sum_k\lambda_k^i=1), multiply and divide inside the log:
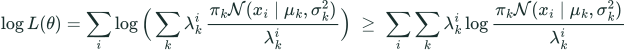 LaTeX:
\log L(\theta)=\sum_i\log\Big(\sum_k\lambda_k^i\,\frac{\pi_k\mathcal N(x_i\mid\mu_k,\sigma_k^2)}{\lambda_k^i}\Big)\;\ge\;\sum_i\sum_k\lambda_k^i\log\frac{\pi_k\mathcal N(x_i\mid\mu_k,\sigma_k^2)}{\lambda_k^i}Step 6. Estimation (EM). Maximise the lower bound alternately. Fixing θ gives the E-step 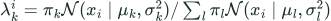 LaTeX:
\lambda_k^i=\pi_k\mathcal N(x_i\mid\mu_k,\sigma_k^2)/\sum_l\pi_l\mathcal N(x_i\mid\mu_l,\sigma_l^2). Fixing λ and differentiating (with a Lagrange multiplier for  LaTeX:
\sum\pi_k=1) gives the M-step:
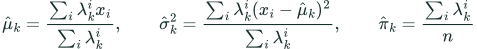 LaTeX:
\hat\mu_k=\frac{\sum_i\lambda_k^ix_i}{\sum_i\lambda_k^i},\qquad\hat\sigma_k^2=\frac{\sum_i\lambda_k^i(x_i-\hat\mu_k)^2}{\sum_i\lambda_k^i},\qquad\hat\pi_k=\frac{\sum_i\lambda_k^i}{n}3. Number of parameters for K = 5
The dimension and covariance structure must also be specified. For the one-dimensional, independent-variance model used in the derivation:
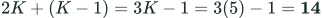 LaTeX:
2K+(K-1)=3K-1=3(5)-1=\mathbf{14}(5 means + 5 variances + 4 free weights, since the 5 weights must add to 1.) In two dimensions with full covariance it would be 29.
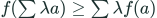 LaTeX:
f(\sum\lambda a)\ge\sum\lambda f(a) (≥, not >).