Intelligent Systems II · TEE · papers
Q7(b) Bellman equation and applications of RL [10]
Re-examination · 31 Jan 2026
Actual TEE re-exam · 100 marks · 3 hours · Q1 compulsory + any 4 of Q2–Q7 · every answer verified (key errors flagged)
Explain the Bellman equation in reinforcement learning. Also give applications of reinforcement learning. [10 marks]
Answer
Write the answer below in this order. It fits in about two pages.
Part A · Bellman equation (5 marks)
1. Setting. Reinforcement learning problems are modelled as a Markov decision process 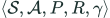 LaTeX:
\langle\mathcal S,\mathcal A,P,R,\gamma\rangle. The agent follows a policy  LaTeX:
\pi(a\mid s) and wants to maximise the return 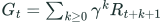 LaTeX:
G_t=\sum_{k\ge0}\gamma^kR_{t+k+1}.
2. Value functions. 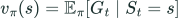 LaTeX:
v_\pi(s)=\mathbb E_\pi[G_t\mid S_t=s] and 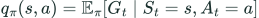 LaTeX:
q_\pi(s,a)=\mathbb E_\pi[G_t\mid S_t=s,A_t=a].
3. Key idea. The return is recursive: 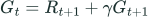 LaTeX:
G_t=R_{t+1}+\gamma G_{t+1}. Taking expectations gives the Bellman expectation equation:
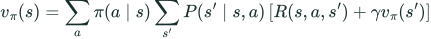 LaTeX:
v_\pi(s)=\sum_a\pi(a\mid s)\sum_{s'}P(s'\mid s,a)\,[R(s,a,s')+\gamma v_\pi(s')]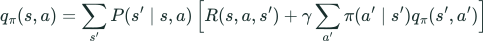 LaTeX:
q_\pi(s,a)=\sum_{s'}P(s'\mid s,a)\,\Big[R(s,a,s')+\gamma\sum_{a'}\pi(a'\mid s')q_\pi(s',a')\Big]4. Optimality. For the optimal policy the average over actions becomes a maximum (Bellman optimality equation):
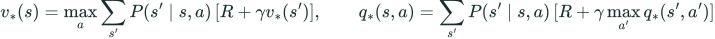 LaTeX:
v_*(s)=\max_a\sum_{s'}P(s'\mid s,a)\,[R+\gamma v_*(s')],\qquad q_*(s,a)=\sum_{s'}P(s'\mid s,a)\,[R+\gamma\max_{a'}q_*(s',a')]5. Meaning and use. The value of a state equals the immediate reward plus the discounted value of the successor state. This breaks a long-horizon problem into one-step sub-problems (dynamic programming). It is the basis of policy evaluation, policy iteration, value iteration and Q-learning; the optimal policy is 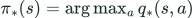 LaTeX:
\pi_*(s)=\arg\max_a q_*(s,a).
6. Small illustration (adds clarity): if staying in a state gives +1 each step with  LaTeX:
\gamma=0.9, then 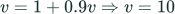 LaTeX:
v=1+0.9v\Rightarrow v=10.
Part B · Applications of reinforcement learning (5 marks)
- Game playing: AlphaGo (defeated Lee Sedol, 2016), Atari agents (DQN), and the Mario agent built in this course's lab.
- Robotics: walking, grasping and balancing learned by trial and error in simulation.
- Autonomous driving: lane changing, merging and parking decisions.
- Recommendation systems: choosing content to maximise long-term engagement rather than single clicks.
- Finance: trading and portfolio rebalancing as sequential decisions.
- Healthcare: dynamic treatment regimes (dose adjustment over time).
- Resource and energy management: data-centre cooling control, traffic-signal timing, inventory control.
- Language models: reinforcement learning from human feedback (RLHF) for chatbots.
One application in detail: traffic-signal control
| Agent | Controller at an intersection. |
|---|---|
| State | Queue length and waiting time on each approach, current signal phase. |
| Actions | Keep the current phase or switch to the next green phase. |
| Reward | Negative of total waiting time (or vehicles cleared per cycle). |
| Learning | Q-learning updates  LaTeX: Q(s,a) from observed traffic; ε-greedy exploration tries alternative timings. |
| Benefit | Adapts to rush hours and incidents; fixed timers cannot. |
| Challenge | Safety during exploration, so agents are trained in simulation first. |