Intelligent Systems II · TEE · revision
Units 1 and 4 in one page
Last-day revision · TEE
Read the night before the TEE
Unit 1
- Logic fails under uncertainty (laziness, theoretical and practical ignorance) → degrees of belief. Decision theory = probability + utility; maximise expected utility.
- Full joint: add the cells where the statement is true; for “given”, divide by the evidence cells. Check the table sums to 1.
- Bayes: posterior = likelihood × prior ÷ evidence. A low prior can make the posterior surprisingly small even after positive evidence; calculate using the stated sensitivity and false-positive rate.
- Naive Bayes: prior × product of class-conditional likelihoods. Without smoothing, one zero likelihood makes the class score zero. Apply Laplace smoothing only when required or when you explicitly state that modelling choice.
- Bayesian network: DAG + CPTs; joint = Π P(node | parents); a node is independent of non-descendants given its parents;
 LaTeX:
2^knumbers per Boolean node. - Query with evidence: sum over hidden variables, both query values, normalise (α). Sprinkler PYQ: P(W | ¬R) = 0.1919 / 0.5 = 0.3838. Flu PYQ: P(Fever | ¬Flu) = 0.2735 / 0.725 = 0.3772.
- Univariate GMM:
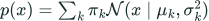 LaTeX:
p(x)=\sum_k\pi_k\mathcal N(x\mid\mu_k,\sigma_k^2). With K separate means, K variances and K weights summing to 1, there are 3K − 1 free parameters (K=5 → 14). Higher-dimensional covariance models have different counts. EM alternates responsibilities and weighted parameter updates. - EM: E-step calculates responsibilities. M-step calculates weighted means and variances, with πₖ=Nₖ/n. GMM uses soft assignments and likelihood; k-means uses hard nearest-centroid assignments and squared distance. Elliptical covariance applies to a multivariate GMM with full covariance matrices.
Unit 4
- Agent, environment, state, action, reward, policy, value, model; exploration vs exploitation (ε-greedy).
- Markov chain: rows = from, columns = to; row sums 1; next = row vector × P; diagram with self-loops.
- Steady state: π = πP, Σπ = 1; compare with today's shares for gain/loss; diagonal = retention.
- MP ⟨S, P⟩ → MRP ⟨S, P, R, γ⟩ → MDP ⟨S, A, P, R, γ⟩.
- Bellman: value = immediate reward + γ × expected next value; optimality replaces Σπ by max.
- Applications: games, robotics, self-driving, recommendation, finance, healthcare, traffic signals, data-centre cooling, RLHF.
Unit 1 and 4 traps: (1) dividing by the wrong evidence in conditional questions; (2) forgetting hidden variables in Bayes nets; (3) writing 15 instead of 14 GMM parameters; (4) multiplying the transition matrix the wrong way; (5) calling a state absorbing when it is not (Pii must be 1).