Natural Language Processing · M2 · formulas
Trigram estimates: two-word history, not two denominators
N-grams & probability
Formulas explained through full worked examples
A trigram model predicts the next word from the two preceding words. The numerator is the count of a triple. The denominator is the count of its two-word history with an available next token. Do not multiply two independent bigram probabilities and call that a trigram probability.
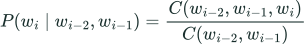 LaTeX:
P(w_i\mid w_{i-2},w_{i-1})=\frac{C(w_{i-2},w_{i-1},w_i)}{C(w_{i-2},w_{i-1})}Question. A corpus contains 12 occurrences of “prime minister”. Eight are followed by “of”, three by “said”, and one by “visited”. Estimate the three trigram probabilities.
Given
History h = (prime, minister). Count of this history = 12. Triple counts for of, said, visited are 8, 3, 1.
To find
The conditional distribution of the next word.
Formula and why it applies
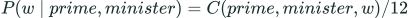 LaTeX:
P(w\mid prime,minister)=C(prime,minister,w)/12All three candidates share one two-word history, so they share denominator 12.
Solution
Step 1. Calculate of
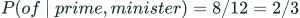 LaTeX:
P(of\mid prime,minister)=8/12=2/3Step 2. Calculate said
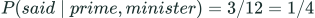 LaTeX:
P(said\mid prime,minister)=3/12=1/4Step 3. Calculate visited
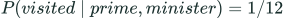 LaTeX:
P(visited\mid prime,minister)=1/12Step 4. Confirm normalization
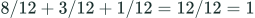 LaTeX:
8/12+3/12+1/12=12/12=1Question. Train a trigram model on “I like tea”, “I like coffee” and “you like tea”. Use two start markers and one end marker. Score “I like tea”.
Given
Three sentences. Padded first sentence is <s> <s> I like tea </s>; pad the other two in the same way.
To find
Four trigram prediction probabilities and the sentence probability.
Formula and why it applies
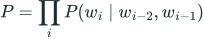 LaTeX:
P=\prod_i P(w_i\mid w_{i-2},w_{i-1})Each prediction uses a two-token context; the two start markers supply the first history.
Solution
Step 1. Count the first-word event
The history (<s>,<s>) occurs three times, and two are followed by I.
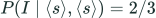 LaTeX:
P(I\mid\langle s\rangle,\langle s\rangle)=2/3Step 2. Count the second-word event
(<s>,I) occurs twice; both are followed by like.
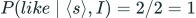 LaTeX:
P(like\mid\langle s\rangle,I)=2/2=1Step 3. Count the third-word event
(I,like) occurs twice; one is followed by tea.
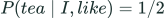 LaTeX:
P(tea\mid I,like)=1/2Step 4. Count the end event
(like,tea) occurs twice; both are followed by end.
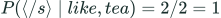 LaTeX:
P(\langle/s\rangle\mid like,tea)=2/2=1Step 5. Multiply all four
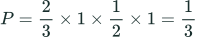 LaTeX:
P=\frac23\times1\times\frac12\times1=\frac13Question. A trigram model supplies P(we|<s>,<s>)=0.4, P(study|<s>,we)=0.5, P(NLP|we,study)=0.8 and P(</s>|study,NLP)=0.25. Score “we study NLP”.
Given
Four trigram conditional factors. The end marker is included.
To find
The complete sentence probability.
Formula and why it applies
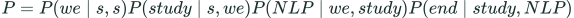 LaTeX:
P=P(we\mid s,s)P(study\mid s,we)P(NLP\mid we,study)P(end\mid study,NLP)Use each supplied two-word history exactly; do not swap its word order.
Solution
Step 1. Insert the values
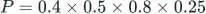 LaTeX:
P=0.4\times0.5\times0.8\times0.25Step 2. Multiply the first pair
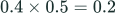 LaTeX:
0.4\times0.5=0.2Step 3. Include NLP
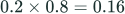 LaTeX:
0.2\times0.8=0.16Step 4. Include the end
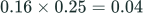 LaTeX:
0.16\times0.25=0.04Yaad rakho: Trigram: teen-word count upar, pehle do-word count neeche.
Why larger n is not automatically better. More context can capture local order more precisely, but each longer history occurs less often. Parameter count, storage and sparsity grow. A model trained on Shakespeare may assign poor probabilities to financial news because training and test distributions differ. Keep a held-out test set; do not evaluate only on memorized training sentences.