Natural Language Processing · M2 · formulas
Unigram estimation and complete worked examples
N-grams & probability
Formulas explained through full worked examples
Maximum likelihood estimation (MLE) chooses probabilities equal to observed relative frequencies. In a unigram model, every word is predicted independently of its surrounding words. If a word occurs c times in N training tokens, its estimate is c/N. To score m specified words, multiply their m unigram probabilities.
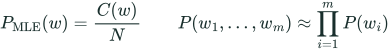 LaTeX:
P_{\mathrm{MLE}}(w)=\frac{C(w)}{N}\qquad P(w_1,\ldots,w_m)\approx\prod_{i=1}^{m}P(w_i)Choose a tokenization convention before counting. Lowercasing, punctuation handling and boundary markers can change the vocabulary and counts. Never count words with one convention and form the denominator with another. A unigram model gives the same product to rearrangements of the same word multiset; that is one of its limitations.
Question. Train an unpadded, case-insensitive unigram model on “I like tea” and “I like coffee”. Find the probability of “I like tea”.
Given
Training sentences: I like tea; I like coffee. Use lowercase words; exclude punctuation and sentence boundaries.
To find
The vocabulary, word probabilities and test-sentence probability.
Formula and why it applies
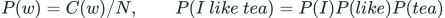 LaTeX:
P(w)=C(w)/N,\qquad P(I\ like\ tea)=P(I)P(like)P(tea)The unigram approximation ignores order and uses total token count for every denominator.
Solution
Step 1. Count every training token
Each sentence contains three words, so N = 3+3 = 6.
Step 2. Count types and frequencies
| Word | Count | MLE probability |
|---|---|---|
| i | 2 | 2/6 = 1/3 |
| like | 2 | 2/6 = 1/3 |
| tea | 1 | 1/6 |
| coffee | 1 | 1/6 |
Vocabulary size V = 4.
Step 3. Write one factor per test word
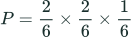 LaTeX:
P=\frac{2}{6}\times\frac{2}{6}\times\frac{1}{6}Step 4. Multiply the fractions
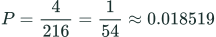 LaTeX:
P=\frac{4}{216}=\frac{1}{54}\approx0.018519Question. A corpus contains counts a: 4, b: 3 and c: 1. Find the unigram probability of “a b a”.
Given
C(a)=4, C(b)=3, C(c)=1. No boundary markers.
To find
P(a b a).
Formula and why it applies
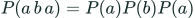 LaTeX:
P(a\,b\,a)=P(a)P(b)P(a)A repeated test word contributes a probability factor at every occurrence; do not include it just once.
Solution
Step 1. Find the total
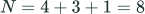 LaTeX:
N=4+3+1=8Step 2. Estimate the required probabilities
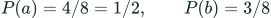 LaTeX:
P(a)=4/8=1/2,\qquad P(b)=3/8Step 3. Use both occurrences of a
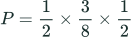 LaTeX:
P=\frac12\times\frac38\times\frac12Step 4. Simplify
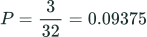 LaTeX:
P=\frac3{32}=0.09375Yaad rakho: Repeated word ka probability bhi repeat multiply hoga.
Question. An unsmoothed unigram model is trained on “red blue red”. Find the probability of “red green”.
Given
N=3. Counts: red=2, blue=1, green=0. The test contains red and green.
To find
The unsmoothed test probability and the reason for its value.
Formula and why it applies
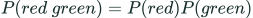 LaTeX:
P(red\ green)=P(red)P(green)MLE assigns zero to an unseen outcome. Smoothing is needed if an unseen in-vocabulary item must receive probability.
Solution
Step 1. Estimate red
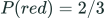 LaTeX:
P(red)=2/3Step 2. Estimate the unseen word
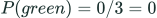 LaTeX:
P(green)=0/3=0Step 3. Multiply
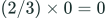 LaTeX:
(2/3)\times0=0