Natural Language Processing · M2 · formulas
A path score is not the probability of the observed sentence
HMM & decoding
Formulas explained through full worked examples
Question. An HMM has π(H)=0.8, π(C)=0.2; transitions H:(0.7,0.3), C:(0.4,0.6); emissions H:(0.2,0.4,0.4), C:(0.5,0.4,0.1) for labels1,2,3. For observations 1,3, calculate the probability of the observations by summing all four two-state paths.
Given
Initial probabilities: π(H)=0.8, π(C)=0.2. Transition matrix: H→H=0.7, H→C=0.3, C→H=0.4, C→C=0.6. Emissions for labels (1,2,3): H=(0.2,0.4,0.4), C=(0.5,0.4,0.1). There is no END-state factor.
To find
P(observations 1,3), not just the best-path score.
Formula and why it applies
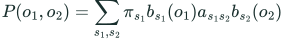 LaTeX:
P(o_1,o_2)=\sum_{s_1,s_2}\pi_{s_1}b_{s_1}(o_1)a_{s_1s_2}b_{s_2}(o_2)The hidden path is unspecified, so its mutually exclusive alternatives must be summed.
Solution
Step 1. Score H,H
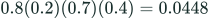 LaTeX:
0.8(0.2)(0.7)(0.4)=0.0448Step 2. Score H,C
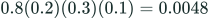 LaTeX:
0.8(0.2)(0.3)(0.1)=0.0048Step 3. Score C,H
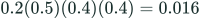 LaTeX:
0.2(0.5)(0.4)(0.4)=0.016Step 4. Score C,C
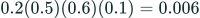 LaTeX:
0.2(0.5)(0.6)(0.1)=0.006Step 5. Add all paths
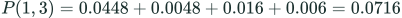 LaTeX:
P(1,3)=0.0448+0.0048+0.016+0.006=0.0716If asked for the posterior of path H,H given observations 1,3, normalize: 0.0448/0.0716 ≈0.625698. Viterbi chooses the best path using joint scores because the observation denominator is common to every candidate. It does not compute that denominator by taking a maximum.